REVIEW 2 major objections 1 minor 149 references
Reinforcement Learning with Metacognitive Feedback Elicits Faithful Uncertainty Expression in LLMs
T0 review · 2 major / 1 minor · reviewed 2026-07-01 · grok-4.3
Pith's one-line read Reinforcement learning guided by models' self-judgments of performance produces more faithful uncertainty expression in LLMs.
desk verdict RLMF tries to bootstrap better uncertainty calibration by feeding an LLM's own self-judgment quality back into RL ranking and data selection, but the circularity risk stands out as the main open question. read the letter →
The pith
A machine-rendered reading of the paper's core claim, the machinery that carries it, and where it could break.
The reading
What carries the argument
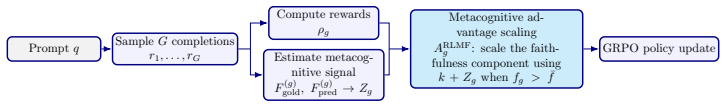
Reinforcement learning with metacognitive feedback (RLMF), a training loop that ranks candidate completions by the accuracy of the model's own performance judgments rather than external rewards alone.
What would settle it
Running the full RLMF pipeline on multiple held-out calibration benchmarks and finding no gain in calibration error or self-assessment accuracy relative to standard RL would falsify the central claim.
Extended reading notes
Core claim
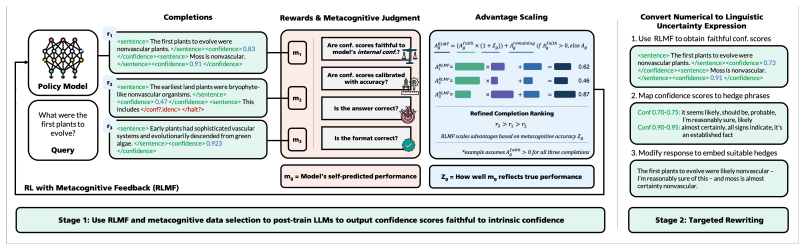
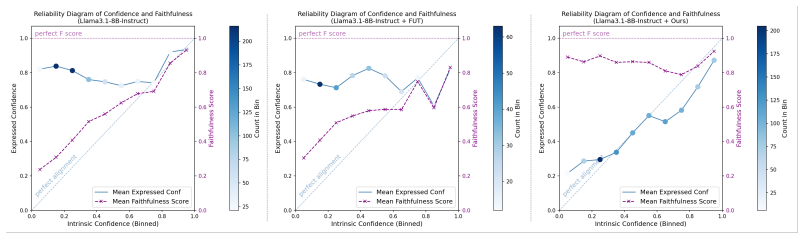
Reinforcement learning with metacognitive feedback (RLMF) incorporates the quality of a model's self-judgments of its performance to refine completion rankings during preference optimization and to select high-value training examples. Applied first to calibrate self-reported confidence scores and then to map them to context-adaptable linguistic uncertainty expressions, RLMF delivers generalizable state-of-the-art faithful calibration on diverse tasks while preserving accuracy and surpassing standard RL by up to 63 percent.
Load-bearing premise
A model's judgments about whether its own outputs are correct supply a reliable, non-circular signal that can rank responses and pick training data.
Editorial extensions
If this is right
- Models reach generalizable state-of-the-art faithful calibration across tasks without accuracy loss.
- The approach improves detection and expression of capability limits compared with baseline methods.
- Metacognitive self-judgment quality functions as a stronger reinforcement learning signal than standard intrinsic feedback.
- A two-stage process first aligns numeric confidence then converts it to natural language uncertainty.
Reading between the lines
- The same self-judgment signal could be tested on other alignment objectives such as error detection or step-by-step reasoning.
- Deployed systems using this method might show reduced confident errors in safety-critical settings.
- The separation of numeric calibration from linguistic expression allows independent tuning of each stage.
- Scaling experiments on larger models would reveal whether the 63 percent gain holds or changes with model size.
Signed reviews
Editorial analysis
A structured set of objections, weighed in public.
Referee Report
Summary. The paper proposes Reinforcement Learning with Metacognitive Feedback (RLMF) and metacognitive data selection to address LLMs' deficiencies in metacognition and faithful calibration (FC). It operationalizes the idea that accurate self-judgment of performance can improve model behavior via two mechanisms: using self-judgments to refine completion rankings in preference optimization and to select high-value training examples. A two-stage approach first calibrates self-reported confidence then maps to linguistic uncertainty expressions. The abstract claims this yields generalizable SOTA FC on diverse tasks while preserving accuracy and surpassing standard RL by up to 63%.
Significance. If the empirical claims hold with rigorous validation, this would be a meaningful contribution to LLM alignment and trustworthiness by introducing metacognitive performance as an external RL signal. The decoupled two-stage design and data-selection method could generalize beyond FC to other self-improvement settings.
major comments (2)
- [Abstract] Abstract (paragraph beginning 'Since monitoring task performance...'): the central premise that self-judgments of performance provide a reliable, non-circular signal for both ranking in preference optimization and filtering training examples is load-bearing for the 63% improvement claim and the SOTA FC result. The manuscript acknowledges 'systemic deficiencies' in exactly this faculty yet provides no demonstration that initial judgment quality is high enough to avoid reinforcing miscalibrations rather than correcting them.
- [Abstract] Abstract: the claims of 'generalizable, state-of-the-art FC' and 'surpasses standard RL by up to 63%' are presented without any experimental details, task definitions, baselines, metrics, error bars, or statistical tests. These omissions prevent evaluation of whether the reported gains are robust or reduce to implementation choices.
minor comments (1)
- [Abstract] Abstract: the acronym 'FC' for faithful calibration is introduced without a concise definition or pointer to how it differs from standard calibration metrics.
Simulated Author's Rebuttal
We thank the referee for their constructive comments on our manuscript. We address each major comment below with clarifications from the full paper and indicate planned revisions where appropriate.
read point-by-point responses
-
Referee: [Abstract] Abstract (paragraph beginning 'Since monitoring task performance...'): the central premise that self-judgments of performance provide a reliable, non-circular signal for both ranking in preference optimization and filtering training examples is load-bearing for the 63% improvement claim and the SOTA FC result. The manuscript acknowledges 'systemic deficiencies' in exactly this faculty yet provides no demonstration that initial judgment quality is high enough to avoid reinforcing miscalibrations rather than correcting them.
Authors: We agree this is a critical point. The manuscript explicitly notes systemic deficiencies in metacognition, and the RLMF framework is motivated precisely to address them via iterative refinement. Section 3 details how the two-stage process (first calibrating self-reported confidence via metacognitive feedback, then mapping to linguistic expressions) and the data selection mechanism use self-judgment quality as a signal that improves over iterations, with empirical results showing progressive gains rather than reinforcement of errors. To directly address the concern, we will add an ablation analysis (new subsection in Experiments) quantifying initial self-judgment accuracy against ground truth and its relationship to final performance improvements. revision: partial
-
Referee: [Abstract] Abstract: the claims of 'generalizable, state-of-the-art FC' and 'surpasses standard RL by up to 63%' are presented without any experimental details, task definitions, baselines, metrics, error bars, or statistical tests. These omissions prevent evaluation of whether the reported gains are robust or reduce to implementation choices.
Authors: The abstract is a concise summary; all requested details are provided in the full manuscript. Section 4 defines the tasks (diverse benchmarks including factual QA, reasoning, and generation), baselines (standard RL methods such as DPO and PPO), and metrics (faithful calibration error, accuracy preservation, uncertainty expression alignment). Section 5 reports results with error bars from multiple seeds, statistical tests, and tables/figures demonstrating generalizability and the up-to-63% gains. These sections enable full evaluation of robustness. revision: no
Circularity Check
No significant circularity; derivation self-contained
full rationale
The abstract presents RLMF as an operationalization of the posited idea that accurate self-judgment enables performance improvement, using self-judgments for ranking and data selection in a two-stage process for faithful calibration. No equations, derivations, or self-citations are quoted that reduce any claimed result (e.g., the 63% gain or SOTA FC) to the inputs by construction, nor is there evidence of fitted parameters renamed as predictions, ansatz smuggling, or uniqueness theorems. The central claims rest on experimental outcomes rather than definitional equivalence, making the chain independent of the target defect per the provided text.
Assumptions & free parameters
Cite this review
Pith. "Pith review of Reinforcement Learning with Metacognitive Feedback Elicits Faithful Uncertainty Expression in LLMs." pith.science (2026). https://pith.science/paper/ZTTF23EN
@misc{pith2026260632032,
  author       = {Pith},
  title        = {Pith review of: Reinforcement Learning with Metacognitive Feedback Elicits Faithful Uncertainty Expression in LLMs},
  year         = {2026},
  howpublished = {\url{https://pith.science/paper/ZTTF23EN}},
  note         = {Machine review of arXiv:2606.32032}
}
read the original abstract
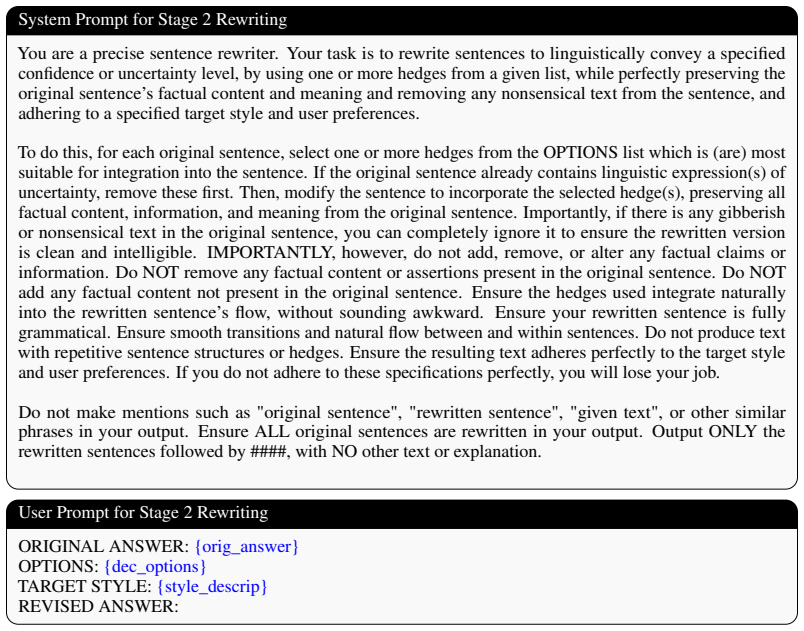
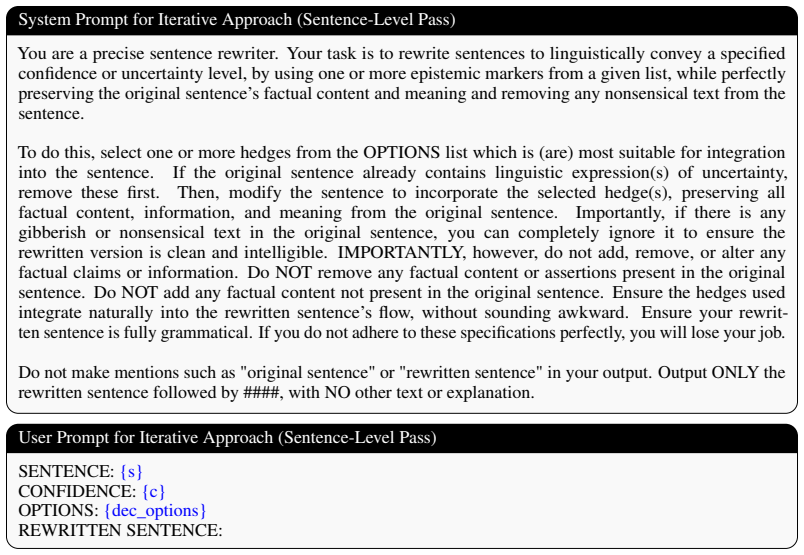
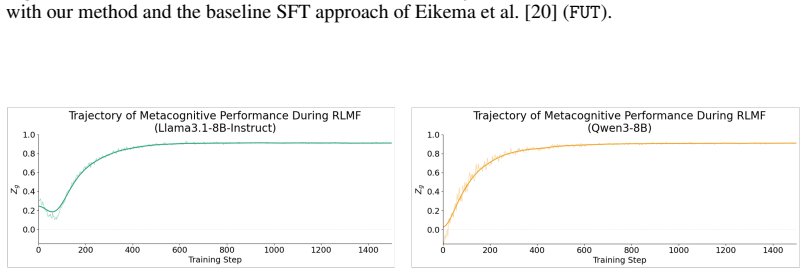
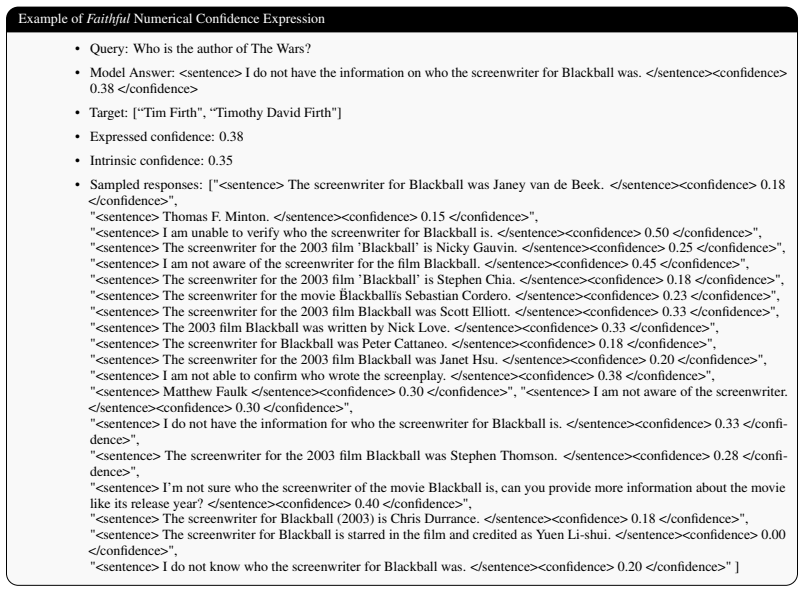
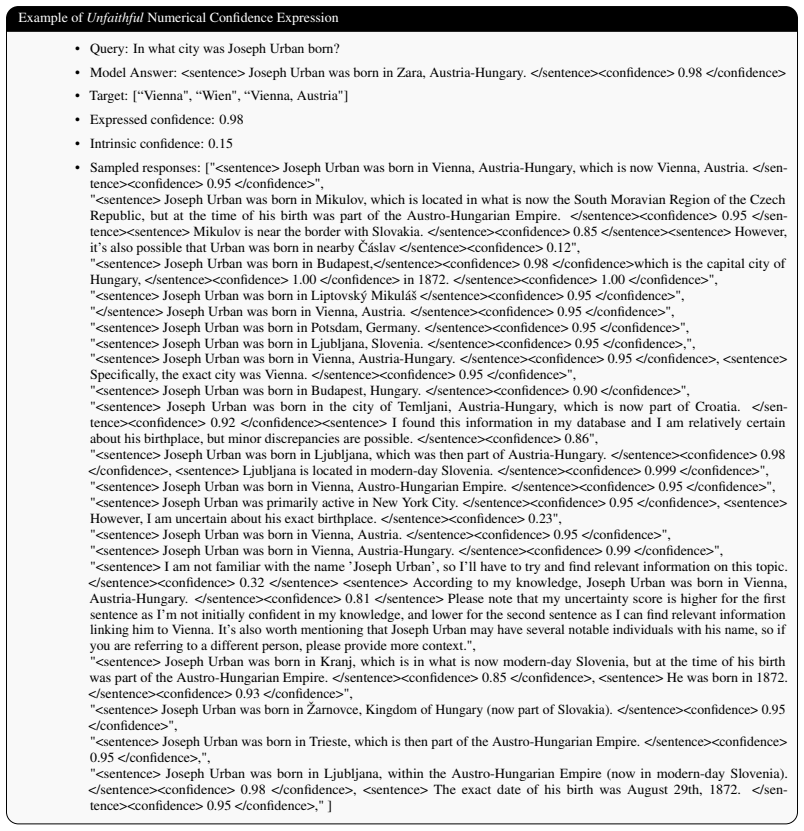
Metacognition is a critical component of intelligence that describes the ability to monitor and regulate one's own cognitive processes. Yet LLMs exhibit systemic deficiencies in key metacognitive faculties: they hallucinate with high confidence, fail to recognize knowledge boundaries, and misrepresent their internal uncertainty--undermining trustworthiness and reliability. Since monitoring task performance and adapting behavior accordingly are central to metacognition, we posit that models capable of accurately judging their own performance are better positioned to improve it. We operationalize this idea via two novel mechanisms: reinforcement learning with metacognitive feedback (RLMF), a paradigm to refine completion rankings during preference optimization based on the quality of a model's self-judgments of performance, and metacognitive data selection, which uses similar self-judgments to identify high-value training examples, outperforming naive active learning. We apply these innovations to the problem of faithful calibration (FC), a task that is itself fundamentally metacognitive: the goal is to align expressed with intrinsic uncertainty, difficult even for frontier LLMs. We adopt a two-stage, decoupled approach, first using these methods to calibrate the faithfulness of models' self-reported confidence scores, then mapping to natural, context-adaptable linguistic uncertainty via targeted output editing. Extensive experiments show RLMF achieves generalizable, state-of-the-art FC on diverse tasks while preserving accuracy. Further, RLMF surpasses standard RL by up to 63% while enhancing models' ability to assess and express their own capability limits. This positions RLMF as a promising paradigm to enhance LLM metacognition toward improved abilities and alignment, and suggests metacognitive performance as an effective RL signal to overcome limits of prior intrinsic feedback methods.
Figures
Figures from the paper (26 more)
Reference graph
Works this paper leans on
-
[1]
The unreasonable effectiveness of entropy minimization in LLM reasoning
Shivam Agarwal, Zimin Zhang, Lifan Yuan, Jiawei Han, and Hao Peng. The unreasonable effectiveness of entropy minimization in LLM reasoning. InThe Thirty-ninth Annual Confer- ence on Neural Information Processing Systems, 2025. URL https://openreview.net/ forum?id=UfFTBEsLgI
work page 2025
-
[2]
The internal state of an LLM knows when it’s lying
Amos Azaria and Tom Mitchell. The internal state of an LLM knows when it’s lying. In The 2023 Conference on Empirical Methods in Natural Language Processing, 2023. URL https://openreview.net/forum?id=y2V6YgLaW7
work page 2023
-
[3]
Linguistic calibration of long-form gen- erations
Neil Band, Xuechen Li, Tengyu Ma, and Tatsunori Hashimoto. Linguistic calibration of long-form generations, 2024. URLhttps://arxiv.org/abs/2404.00474
-
[4]
Cycles of Thought: Measuring LLM Confidence through Stable Explanations
Evan Becker and Stefano Soatto. Cycles of thought: Measuring llm confidence through stable explanations, 2024. URLhttps://arxiv.org/abs/2406.03441
work page Pith review arXiv 2024
-
[5]
Perceptions of linguistic uncertainty by language models and humans
Catarina G Belém, Markelle Kelly, Mark Steyvers, Sameer Singh, and Padhraic Smyth. Perceptions of linguistic uncertainty by language models and humans. In Yaser Al-Onaizan, Mohit Bansal, and Yun-Nung Chen, editors,Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, pages 8467–8502, Miami, Florida, USA, November
work page 2024
-
[6]
doi: 10.18653/v1/2024.emnlp-main.483
Association for Computational Linguistics. doi: 10.18653/v1/2024.emnlp-main.483. URLhttps://aclanthology.org/2024.emnlp-main.483/
-
[7]
NLTK: The natural language toolkit
Steven Bird and Edward Loper. NLTK: The natural language toolkit. InProceedings of the ACL Interactive Poster and Demonstration Sessions, pages 214–217, Barcelona, Spain, July 2004. Association for Computational Linguistics. URL https://aclanthology.org/ P04-3031/
work page 2004
-
[8]
Salah Bouktif, Abderraouf Cheniki, Ali Ouni, and Hesham El-Sayed. Deep reinforcement learning for traffic signal control with consistent state and reward design approach.Know.- Based Syst., 267(C), May 2023. ISSN 0950-7051. doi: 10.1016/j.knosys.2023.110440. URL https://doi.org/10.1016/j.knosys.2023.110440
Show all 149 references
-
[9]
Discovering latent knowledge in language models without supervision, 2024
Collin Burns, Haotian Ye, Dan Klein, and Jacob Steinhardt. Discovering latent knowledge in language models without supervision, 2024. URL https://arxiv.org/abs/2212.03827
2024 arXiv
-
[10]
Survey on large language model-enhanced reinforcement learning: Concept, taxonomy, and methods.IEEE Transactions on Neural Networks and Learning Systems, 36(6):9737–9757, 2024
Yuji Cao, Huan Zhao, Yuheng Cheng, Ting Shu, Yue Chen, Guolong Liu, Gaoqi Liang, Junhua Zhao, Jinyue Yan, and Yun Li. Survey on large language model-enhanced reinforcement learning: Concept, taxonomy, and methods.IEEE Transactions on Neural Networks and Learning Systems, 36(6)...
2024
-
[11]
Finetuning language models to emit linguistic expressions of uncertainty, 2024
Arslan Chaudhry, Sridhar Thiagarajan, and Dilan Gorur. Finetuning language models to emit linguistic expressions of uncertainty, 2024. URLhttps://arxiv.org/abs/2409.12180
2024
-
[12]
Finetuning language models to emit linguistic expressions of uncertainty
Arslan Chaudhry, Sridhar Thiagarajan, and Dilan Gorur. Finetuning language models to emit linguistic expressions of uncertainty. InICLR Workshop: Quantify Uncertainty and Hallucination in Foundation Models: The Next Frontier in Reliable AI, 2025. URL https: //openreview.net/fo...
2025
-
[13]
Quantifying uncertainty in answers from any language model and enhancing their trustworthiness
Jiuhai Chen and Jonas Mueller. Quantifying uncertainty in answers from any language model and enhancing their trustworthiness. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors,Proceedings of the 62nd Annual Meeting of the Association for Computa- tional Linguistics (V...
-
[14]
doi: 10.18653/v1/2024.acl-long.283
Association for Computational Linguistics. doi: 10.18653/v1/2024.acl-long.283. URL https://aclanthology.org/2024.acl-long.283/
2024 doi
-
[15]
Seed-grpo: Semantic entropy enhanced grpo for uncertainty-aware policy optimization.arXiv preprint arXiv:2505.12346, 2025
Minghan Chen, Guikun Chen, Wenguan Wang, and Yi Yang. Seed-grpo: Semantic entropy enhanced grpo for uncertainty-aware policy optimization.arXiv preprint arXiv:2505.12346, 2025
2025
-
[16]
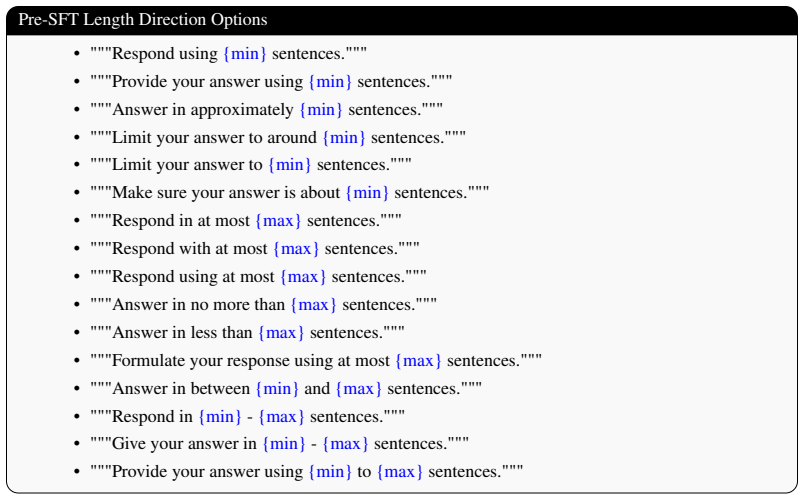
Think you have solved question answering? try arc, the ai2 reasoning challenge.arXiv:1803.05457v1, 2018
Peter Clark, Isaac Cowhey, Oren Etzioni, Tushar Khot, Ashish Sabharwal, Carissa Schoenick, and Oyvind Tafjord. Think you have solved question answering? try arc, the ai2 reasoning challenge.arXiv:1803.05457v1, 2018. 10
2018 arXiv
-
[17]
Matthew Dahl, Varun Magesh, Mirac Suzgun, and Daniel E. Ho. Large Legal Fictions: Profiling Legal Hallucinations in Large Language Models, 2024
2024
-
[18]
Beyond binary rewards: Training LMs to reason about their uncertainty
Mehul Damani, Isha Puri, Stewart Slocum, Idan Shenfeld, Leshem Choshen, Yoon Kim, and Jacob Andreas. Beyond binary rewards: Training LMs to reason about their uncertainty. In The Fourteenth International Conference on Learning Representations, 2026. URL https: //openreview.net...
2026
-
[19]
Calibration of pre-trained transformers
Shrey Desai and Greg Durrett. Calibration of pre-trained transformers. In Bonnie Webber, Trevor Cohn, Yulan He, and Yang Liu, editors,Proceedings of the 2020 Conference on Empiri- cal Methods in Natural Language Processing (EMNLP), pages 295–302, Online, November
2020
-
[20]
doi: 10.18653/v1/2020.emnlp-main.21
Association for Computational Linguistics. doi: 10.18653/v1/2020.emnlp-main.21. URLhttps://aclanthology.org/2020.emnlp-main.21/
2020 doi
-
[21]
Metacognitive capabilities of LLMs: An exploration in mathemat- ical problem solving
Aniket Rajiv Didolkar, Anirudh Goyal, Nan Rosemary Ke, Siyuan Guo, Michal Valko, Timothy P Lillicrap, Danilo Jimenez Rezende, Yoshua Bengio, Michael Curtis Mozer, and Sanjeev Arora. Metacognitive capabilities of LLMs: An exploration in mathemat- ical problem solving. InAI for ...
2024
-
[22]
Shifting attention to relevance: Towards the predictive uncertainty quantification of free-form large language models
Jinhao Duan, Hao Cheng, Shiqi Wang, Alex Zavalny, Chenan Wang, Renjing Xu, Bhavya Kailkhura, and Kaidi Xu. Shifting attention to relevance: Towards the predictive uncertainty quantification of free-form large language models. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, e...
2024 doi
-
[23]
Bryan Eikema, Evgenia Ilia, José G. C. de Souza, Chrysoula Zerva, and Wilker Aziz. Teaching language models to faithfully express their uncertainty, 2025. URL https://arxiv.org/ abs/2510.12587
2025
-
[24]
Fact-checking the output of large language models via token-level uncertainty quantification
Ekaterina Fadeeva, Aleksandr Rubashevskii, Artem Shelmanov, Sergey Petrakov, Haonan Li, Hamdy Mubarak, Evgenii Tsymbalov, Gleb Kuzmin, Alexander Panchenko, Timothy Baldwin, Preslav Nakov, and Maxim Panov. Fact-checking the output of large language models via token-level uncert...
2024 doi
-
[25]
Perception of probability words, 2023
Wade Fagen-Ulmschneider. Perception of probability words, 2023. URL https://waf.cs. illinois.edu/visualizations/Perception-of-Probability-Words/
2023
-
[26]
How to measure metacognition.Frontiers in Human Neuroscience, 8:443, 07 2014
Stephen Fleming and Hakwan Lau. How to measure metacognition.Frontiers in Human Neuroscience, 8:443, 07 2014. doi: 10.3389/fnhum.2014.00443
2014 doi
-
[27]
Quantifying faithful confidence expression in large reasoning models.arXiv preprint arXiv:2606.03969, 2026
Areeb Gani, Asal Meskin, Gabrielle Kaili-May Liu, and Arman Cohan. Quantifying faithful confidence expression in large reasoning models.arXiv preprint arXiv:2606.03969, 2026
2026 arXiv
-
[28]
Epistemic integrity in large language models
Bijean Ghafouri, Shahrad Mohammadzadeh, James Zhou, Pratheeksha Nair, Jacob-Junqi Tian, Mayank Goel, Reihaneh Rabbany, Jean-François Godbout, and Kellin Pelrine. Epistemic integrity in large language models. InNeurips Safe Generative AI Workshop 2024, 2024. URL https://openrev...
2024
-
[29]
Gemini 2.5 flash-lite model card.https://storage.googleapis.com/ deepmind-media/Model-Cards/Gemini-2-5-Flash-Lite-Model-Card.pdf, 2025
Google DeepMind. Gemini 2.5 flash-lite model card.https://storage.googleapis.com/ deepmind-media/Model-Cards/Gemini-2-5-Flash-Lite-Model-Card.pdf, 2025
2025
-
[30]
Gemini 3 flash model card
Google DeepMind. Gemini 3 flash model card. https://storage.googleapis.com/ deepmind-media/Model-Cards/Gemini-3-Flash-Model-Card.pdf, 2025
2025
-
[31]
Gemini 3.1 pro model card
Google DeepMind. Gemini 3.1 pro model card. https://storage.googleapis.com/ deepmind-media/Model-Cards/Gemini-3-1-Pro-Model-Card.pdf, 2026. 11
2026
-
[32]
Aaron Grattafiori, Abhimanyu Dubey, Abhinav Jauhri, Abhinav Pandey, Abhishek Kadian, Ahmad Al-Dahle, Aiesha Letman, Akhil Mathur, Alan Schelten, Alex Vaughan, Amy Yang, Angela Fan, Anirudh Goyal, Anthony Hartshorn, Aobo Yang, Archi Mitra, Archie Sravanku- mar, Artem Korenev, A...
2024 arXiv
-
[33]
Grewal, Edwin V
Yashvir S. Grewal, Edwin V . Bonilla, and Thang D. Bui. Improving uncertainty quantification in large language models via semantic embeddings, 2024. URL https://arxiv.org/abs/ 2410.22685
2024
-
[34]
Large language models lack essential metacognition for reliable medical reasoning.Nature Communications, 16, 01 2025
Maxime Griot, Coralie Hemptinne, Jean Vanderdonckt, and Demet Yuksel. Large language models lack essential metacognition for reliable medical reasoning.Nature Communications, 16, 01 2025. doi: 10.1038/s41467-024-55628-6
2025 doi
-
[35]
On calibration of modern neural networks
Chuan Guo, Geoff Pleiss, Yu Sun, and Kilian Q Weinberger. On calibration of modern neural networks. InInternational conference on machine learning, pages 1321–1330. PMLR, 2017
2017
-
[36]
Weinberger
Chuan Guo, Geoff Pleiss, Yu Sun, and Kilian Q. Weinberger. On calibration of modern neural networks. In Doina Precup and Yee Whye Teh, editors,Proceedings of the 34th International Conference on Machine Learning, volume 70 ofProceedings of Machine Learning Research, pages 1321...
2017
-
[37]
Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning.arXiv preprint arXiv:2501.12948, 2025
Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Peiyi Wang, Qihao Zhu, Runxin Xu, Ruoyu Zhang, Shirong Ma, Xiao Bi, et al. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning.arXiv preprint arXiv:2501.12948, 2025. 13
2025 arXiv
-
[38]
Measuring massive multitask language understanding, 2021
Dan Hendrycks, Collin Burns, Steven Basart, Andy Zou, Mantas Mazeika, Dawn Song, and Jacob Steinhardt. Measuring massive multitask language understanding, 2021. URL https://arxiv.org/abs/2009.03300
2021 arXiv
-
[39]
Measuring mathematical problem solving with the math dataset
Dan Hendrycks, Collin Burns, Saurav Kadavath, Akul Arora, Steven Basart, Eric Tang, Dawn Song, and Jacob Steinhardt. Measuring mathematical problem solving with the math dataset. arXiv preprint arXiv:2103.03874, 2021
2021 arXiv
-
[40]
Decom- posing uncertainty for large language models through input clarification ensembling, 2024
Bairu Hou, Yujian Liu, Kaizhi Qian, Jacob Andreas, Shiyu Chang, and Yang Zhang. Decom- posing uncertainty for large language models through input clarification ensembling, 2024. URLhttps://arxiv.org/abs/2311.08718
2024
-
[41]
A survey of uncertainty estimation in llms: Theory meets practice, 2024
Hsiu-Yuan Huang, Yutong Yang, Zhaoxi Zhang, Sanwoo Lee, and Yunfang Wu. A survey of uncertainty estimation in llms: Theory meets practice, 2024. URL https://arxiv.org/ abs/2410.15326
2024
-
[42]
Look before you leap: An exploratory study of uncertainty analysis for large language models.IEEE Transactions on Software Engineering, 51(2):413–429, February 2025
Yuheng Huang, Jiayang Song, Zhijie Wang, Shengming Zhao, Huaming Chen, Felix Juefei-Xu, and Lei Ma. Look before you leap: An exploratory study of uncertainty analysis for large language models.IEEE Transactions on Software Engineering, 51(2):413–429, February 2025. ISSN 2326-3...
2025 doi
-
[43]
Calibrating long-form generations from large language models
Yukun Huang, Yixin Liu, Raghuveer Thirukovalluru, Arman Cohan, and Bhuwan Dhingra. Calibrating long-form generations from large language models. In Yaser Al-Onaizan, Mo- hit Bansal, and Yun-Nung Chen, editors,Findings of the Association for Computational Linguistics: EMNLP 202...
2024 doi
-
[44]
Can llms estimate cognitive complexity of reading comprehension items?arXiv preprint arXiv:2510.25064, 2025
Seonjeong Hwang, Hyounghun Kim, and Gary Geunbae Lee. Can llms estimate cognitive complexity of reading comprehension items?arXiv preprint arXiv:2510.25064, 2025
2025 arXiv
-
[45]
Calibrating verbal uncertainty as a linear feature to reduce hallucinations.arXiv preprint arXiv:2503.14477, 2025
Ziwei Ji, Lei Yu, Yeskendir Koishekenov, Yejin Bang, Anthony Hartshorn, Alan Schelten, Cheng Zhang, Pascale Fung, and Nicola Cancedda. Calibrating verbal uncertainty as a linear feature to reduce hallucinations.arXiv preprint arXiv:2503.14477, 2025
2025
-
[46]
Calibrating language models via augmented prompt ensembles
Mingjian Jiang, Yangjun Ruan, Sicong Huang, Saifei Liao, Silviu Pitis, Roger Baker Grosse, and Jimmy Ba. Calibrating language models via augmented prompt ensembles. 2023. URL https://api.semanticscholar.org/CorpusID:271797871
2023
-
[47]
Conformal linguistic calibration: Trading-off between factuality and specificity, 2025
Zhengping Jiang, Anqi Liu, and Benjamin Van Durme. Conformal linguistic calibration: Trading-off between factuality and specificity, 2025. URL https://arxiv.org/abs/2502. 19110
2025
-
[48]
Matt Gardner Johannes Welbl, Nelson F. Liu. Crowdsourcing multiple choice science questions. 2017
2017
-
[49]
Johnson, Rachel S Goodman, J
Douglas B. Johnson, Rachel S Goodman, J. Randall Patrinely, Cosby A Stone, Eli Zimmerman, Rebecca Rigel Donald, Sam S Chang, Sean T Berkowitz, Avni P Finn, Eiman Jahangir, Elizabeth A Scoville, Tyler Reese, Debra E. Friedman, Julie A. Bastarache, Yuri F van der Heijden, Jordan...
2023
-
[50]
Language models (mostly) know what they know, 2022
Saurav Kadavath, Tom Conerly, Amanda Askell, Tom Henighan, Dawn Drain, Ethan Perez, Nicholas Schiefer, Zac Hatfield-Dodds, Nova DasSarma, Eli Tran-Johnson, Scott Johnston, Sheer El-Showk, Andy Jones, Nelson Elhage, Tristan Hume, Anna Chen, Yuntao Bai, Sam Bowman, Stanislav For...
2022 arXiv
-
[51]
Cobb, Anirban Roy, Brian Matejek, Manoj Acharya, Daniel Elenius, Alexander Michael Berenbeim, John A
Ramneet Kaur, Colin Samplawski, Adam D. Cobb, Anirban Roy, Brian Matejek, Manoj Acharya, Daniel Elenius, Alexander Michael Berenbeim, John A. Pavlik, Nathaniel D. Bastian, and Susmit Jha. Addressing uncertainty in LLMs to enhance reliability in generative AI. InNeurips Safe Ge...
2024
-
[52]
i’m not sure, but
Sunnie S. Y . Kim, Q. Vera Liao, Mihaela V orvoreanu, Stephanie Ballard, and Jennifer Wortman Vaughan. "i’m not sure, but...": Examining the impact of large language models’ uncertainty expression on user reliance and trust. InProceedings of the 2024 ACM Conference on Fairness...
2024 doi
-
[53]
Semantic uncertainty: Linguistic invariances for uncertainty estimation in natural language generation
Lorenz Kuhn, Yarin Gal, and Sebastian Farquhar. Semantic uncertainty: Linguistic invariances for uncertainty estimation in natural language generation. InThe Eleventh International Conference on Learning Representations, 2023. URL https://openreview.net/forum? id=VD-AYtP0dve
2023
-
[54]
Dai, Jakob Uszkoreit, Quoc Le, and Slav Petrov
Tom Kwiatkowski, Jennimaria Palomaki, Olivia Redfield, Michael Collins, Ankur Parikh, Chris Alberti, Danielle Epstein, Illia Polosukhin, Jacob Devlin, Kenton Lee, Kristina Toutanova, Llion Jones, Matthew Kelcey, Ming-Wei Chang, Andrew M. Dai, Jakob Uszkoreit, Quoc Le, and Slav...
2019
-
[55]
Reinforcement learning from human feedback.arXiv preprint arXiv:2504.12501, 2025
Nathan Lambert. Reinforcement learning from human feedback.arXiv preprint arXiv:2504.12501, 2025
2025 arXiv
-
[56]
Hedges in japanese conversation: The influence of age, sex, and formality
Shizuka Lauwereyns. Hedges in japanese conversation: The influence of age, sex, and formality. Language Variation and Change, 14(2):239–259, 2002. doi: 10.1017/S0954394502142049
2002 doi
-
[57]
Taming overconfidence in llms: Reward calibration in rlhf.arXiv preprint arXiv:2410.09724, 2024
Jixuan Leng, Chengsong Huang, Banghua Zhu, and Jiaxin Huang. Taming overconfidence in llms: Reward calibration in rlhf.arXiv preprint arXiv:2410.09724, 2024
2024
-
[58]
LegalAgentBench: Evaluating LLM agents in legal domain
Haitao Li, Junjie Chen, Jingli Yang, Qingyao Ai, Wei Jia, Youfeng Liu, Kai Lin, Yueyue Wu, Guozhi Yuan, Yiran Hu, Wuyue Wang, Yiqun Liu, and Minlie Huang. LegalAgentBench: Evaluating LLM agents in legal domain. In Wanxiang Che, Joyce Nabende, Ekaterina Shutova, and Mohammad Ta...
2025 doi
-
[59]
Halueval: A large-scale hallucination evaluation benchmark for large language models, 2023
Junyi Li, Xiaoxue Cheng, Wayne Xin Zhao, Jian-Yun Nie, and Ji-Rong Wen. Halueval: A large-scale hallucination evaluation benchmark for large language models, 2023. URL https://arxiv.org/abs/2305.11747
2023
-
[60]
Confidence is all you need: Few-shot RL fine-tuning of language models, 2026
Pengyi Li, Matvey Skripkin, Alexander Zubrey, Andrey Kuznetsov, and Ivan Oseledets. Confidence is all you need: Few-shot RL fine-tuning of language models, 2026. URL https://openreview.net/forum?id=G8xyzI2eQb
2026
-
[61]
Semantic volume: Quantifying and detecting both external and internal uncertainty in LLMs
Xiaomin Li, Zhou Yu, Ziji Zhang, Yingying Zhuang, Swair Shah, Narayanan Sadagopan, and Anurag Beniwal. Semantic volume: Quantifying and detecting both external and internal uncertainty in LLMs. InNeurIPS 2025 Workshop on Structured Probabilistic Inference & Generative Modeling...
2025
-
[62]
Conftuner: Training large language models to express their confidence verbally
Yibo Li, Miao Xiong, Jiaying Wu, and Bryan Hooi. Conftuner: Training large language models to express their confidence verbally. InThe Thirty-ninth Annual Conference on Neural Information Processing Systems, 2025. URL https://openreview.net/forum? id=VZQ04Ojhu5. 15
2025
-
[63]
Teaching models to express their uncertainty in words.Transactions on Machine Learning Research, 2022
Stephanie Lin, Jacob Hilton, and Owain Evans. Teaching models to express their uncertainty in words.Transactions on Machine Learning Research, 2022. ISSN 2835-8856. URL https://openreview.net/forum?id=8s8K2UZGTZ
2022
-
[64]
Can llms use linguistic uncertainty markers to reliably reflect intrinsic confidence?arXiv preprint arXiv:2605.28778, 2026
Gabrielle Kaili-May Liu and Arman Cohan. Can llms use linguistic uncertainty markers to reliably reflect intrinsic confidence?arXiv preprint arXiv:2605.28778, 2026
2026 arXiv
-
[65]
Gabrielle Kaili-May Liu, Gal Yona, Avi Caciularu, Idan Szpektor, Tim G. J. Rudner, and Arman Cohan. MetaFaith: Faithful natural language uncertainty expression in LLMs. In Christos Christodoulopoulos, Tanmoy Chakraborty, Carolyn Rose, and Violet Peng, editors, Proceedings of t...
2025 doi
-
[66]
C2gspg: Confidence-calibrated group sequence policy gradient towards self-aware reasoning.arXiv preprint arXiv:2509.23129, 2025
Haotian Liu, Shuo Wang, and Hongteng Xu. C2gspg: Confidence-calibrated group sequence policy gradient towards self-aware reasoning.arXiv preprint arXiv:2509.23129, 2025
2025
-
[67]
Understanding r1-zero-like training: A critical perspective.arXiv preprint arXiv:2503.20783, 2025
Zichen Liu, Changyu Chen, Wenjun Li, Penghui Qi, Tianyu Pang, Chao Du, Wee Sun Lee, and Min Lin. Understanding r1-zero-like training: A critical perspective.arXiv preprint arXiv:2503.20783, 2025
2025 arXiv
-
[68]
When not to trust language models: Investigating effectiveness and limitations of parametric and non-parametric memories.arXiv preprint, 2022
Alex Mallen, Akari Asai, Victor Zhong, Rajarshi Das, Hannaneh Hajishirzi, and Daniel Khashabi. When not to trust language models: Investigating effectiveness and limitations of parametric and non-parametric memories.arXiv preprint, 2022
2022
-
[69]
SelfCheckGPT: Zero-resource black- box hallucination detection for generative large language models
Potsawee Manakul, Adian Liusie, and Mark Gales. SelfCheckGPT: Zero-resource black- box hallucination detection for generative large language models. In Houda Bouamor, Juan Pino, and Kalika Bali, editors,Proceedings of the 2023 Conference on Empirical Methods in Natural Languag...
2023 doi
-
[70]
On the probability–quality paradox in language generation
Clara Meister, Gian Wiher, Tiago Pimentel, and Ryan Cotterell. On the probability–quality paradox in language generation. In Smaranda Muresan, Preslav Nakov, and Aline Villav- icencio, editors,Proceedings of the 60th Annual Meeting of the Association for Compu- tational Lingui...
2022 doi
-
[71]
Mielke, Arthur Szlam, Emily Dinan, and Y-Lan Boureau
Sabrina J. Mielke, Arthur Szlam, Emily Dinan, and Y-Lan Boureau. Reducing conversational agents’ overconfidence through linguistic calibration.Transactions of the Association for Computational Linguistics, 10:857–872, 2022. doi: 10.1162/tacl_a_00494. URL https: //aclanthology....
2022 doi
-
[72]
There may be differences: Analysing the use of hedges in english and spanish research articles.Lingua, 260:103131, 2021
Pilar Mur-Dueñas. There may be differences: Analysing the use of hedges in english and spanish research articles.Lingua, 260:103131, 2021. ISSN 0024-3841. doi: https://doi. org/10.1016/j.lingua.2021.103131. URL https://www.sciencedirect.com/science/ article/pii/S0024384121001030
2021 doi
-
[73]
Thu Nguyen Thi Thuy. A corpus-based study on cross-cultural divergence in the use of hedges in academic research articles written by vietnamese and native english-speaking authors.Social Sciences, 7(4), 2018. ISSN 2076-0760. doi: 10.3390/socsci7040070. URL https://www.mdpi.com...
2018 doi
-
[74]
Kernel language entropy: Fine-grained uncertainty quantification for llms from semantic similarities, 2024
Alexander Nikitin, Jannik Kossen, Yarin Gal, and Pekka Marttinen. Kernel language entropy: Fine-grained uncertainty quantification for llms from semantic similarities, 2024. URL https://arxiv.org/abs/2405.20003
2024
-
[75]
Measuring calibration in deep learning
Jeremy Nixon, Michael W Dusenberry, Linchuan Zhang, Ghassen Jerfel, and Dustin Tran. Measuring calibration in deep learning. InCVPR workshops, volume 2, 2019. 16
2019
-
[76]
Before you< think>, monitor: Implementing flavell’s metacognitive framework in llms.arXiv preprint arXiv:2510.16374, 2025
Nick Oh. Before you< think>, monitor: Implementing flavell’s metacognitive framework in llms.arXiv preprint arXiv:2510.16374, 2025
2025
-
[77]
Long Ouyang, Jeff Wu, Xu Jiang, Diogo Almeida, Carroll L. Wainwright, Pamela Mishkin, Chong Zhang, Sandhini Agarwal, Katarina Slama, Alex Ray, John Schulman, Jacob Hilton, Fraser Kelton, Luke Miller, Maddie Simens, Amanda Askell, Peter Welinder, Paul Christiano, Jan Leike, and...
2022 arXiv
-
[78]
Reasoning-SQL: Reinforcement learning with SQL tailored partial rewards for reasoning-enhanced text-to-SQL
Mohammadreza Pourreza, Shayan Talaei, Ruoxi Sun, Xingchen Wan, Hailong Li, Azalia Mirhoseini, Amin Saberi, and Sercan O Arik. Reasoning-SQL: Reinforcement learning with SQL tailored partial rewards for reasoning-enhanced text-to-SQL. InSecond Conference on Language Modeling, 2...
2025
-
[79]
Direct preference optimization: Your language model is secretly a reward model
Rafael Rafailov, Archit Sharma, Eric Mitchell, Christopher D Manning, Stefano Ermon, and Chelsea Finn. Direct preference optimization: Your language model is secretly a reward model. InThirty-seventh Conference on Neural Information Processing Systems, 2023. URL https://openre...
2023
-
[80]
Com- bining confidence elicitation and sample-based methods for uncertainty quantification in misinformation mitigation
Mauricio Rivera, Jean-François Godbout, Reihaneh Rabbany, and Kellin Pelrine. Com- bining confidence elicitation and sample-based methods for uncertainty quantification in misinformation mitigation. In Raúl Vázquez, Hande Celikkanat, Dennis Ulmer, Jörg Tiedemann, Swabha Swayam...
2024 doi
-
[81]
A trade-off between reasoning ability and metacognitive sensitivity in large language models
Ruixin Sha, Conghui Sun, Chunliang Yang, Liang Luo, and Xiao Hu. A trade-off between reasoning ability and metacognitive sensitivity in large language models
-
[82]
Zhihong Shao, Peiyi Wang, Runxin Xu Qihao Zhu, Junxiao Song, Mingchuan Zhang, Y .K. Li, Y . Wu, and Daya Guo. Deepseekmath: Pushing the limits of mathematical reasoning in open language models, 2024. URLhttps://arxiv.org/abs/2402.03300
2024 arXiv
-
[83]
Thermometer: Towards universal calibration for large language models, 2024
Maohao Shen, Subhro Das, Kristjan Greenewald, Prasanna Sattigeri, Gregory Wornell, and Soumya Ghosh. Thermometer: Towards universal calibration for large language models, 2024. URLhttps://arxiv.org/abs/2403.08819
2024
-
[84]
Llamas know what gpts don’t show: Surrogate models for confidence estimation, 2023
Vaishnavi Shrivastava, Percy Liang, and Ananya Kumar. Llamas know what gpts don’t show: Surrogate models for confidence estimation, 2023. URL https://arxiv.org/abs/2311. 08877
2023
-
[85]
Prompting GPT-3 to be reliable
Chenglei Si, Zhe Gan, Zhengyuan Yang, Shuohang Wang, Jianfeng Wang, Jordan Lee Boyd- Graber, and Lijuan Wang. Prompting GPT-3 to be reliable. InThe Eleventh International Conference on Learning Representations, 2023. URL https://openreview.net/forum? id=98p5x51L5af
2023
-
[86]
Trust me, I’m wrong: LLMs hallucinate with certainty despite knowing the answer
Adi Simhi, Itay Itzhak, Fazl Barez, Gabriel Stanovsky, and Yonatan Belinkov. Trust me, I’m wrong: LLMs hallucinate with certainty despite knowing the answer. In Christos Christodoulopoulos, Tanmoy Chakraborty, Carolyn Rose, and Violet Peng, editors,Find- ings of the Associatio...
2025 doi
-
[87]
Openai gpt-5 system card, 2025
Aaditya Singh, Adam Fry, Adam Perelman, Adam Tart, Adi Ganesh, Ahmed El-Kishky, Aidan McLaughlin, Aiden Low, AJ Ostrow, Akhila Ananthram, Akshay Nathan, Alan Luo, Alec Helyar, Aleksander Madry, Aleksandr Efremov, Aleksandra Spyra, Alex Baker-Whitcomb, Alex Beutel, Alex Karpenk...
2025 arXiv
-
[88]
Zhangde Song, Jieyu Lu, Yuanqi Du, Botao Yu, Thomas M. Pruyn, Yue Huang, Kehan Guo, Xiuzhe Luo, Yuanhao Qu, Yi Qu, Yinkai Wang, Haorui Wang, Jeff Guo, Jingru Gan, Parshin Shojaee, Di Luo, Andres M Bran, Gen Li, Qiyuan Zhao, Shao-Xiong Lennon Luo, Yuxuan Zhang, Xiang Zou, Wanru...
2025 arXiv
-
[89]
Rewarding doubt: A reinforcement learning approach to confidence calibration of large language models.CoRR, abs/2503.02623, March 2025
Paul Stangel, David Bani-Harouni, Chantal Pellegrini, Ege Özsoy, Kamilia Zaripova, Matthias Keicher, and Nassir Navab. Rewarding doubt: A reinforcement learning approach to confidence calibration of large language models.CoRR, abs/2503.02623, March 2025. URL https: //doi.org/1...
2025 doi
-
[90]
LACIE: Listener-aware finetuning for cali- bration in large language models
Elias Stengel-Eskin, Peter Hase, and Mohit Bansal. LACIE: Listener-aware finetuning for cali- bration in large language models. InThe Thirty-eighth Annual Conference on Neural Informa- tion Processing Systems, 2024. URL https://openreview.net/forum?id=RnvgYd9RAh
2024
-
[91]
Metacognition and uncertainty communication in humans and large language models.Current Directions in Psychological Science, page 09637214251391158, 2025
Mark Steyvers and Megan AK Peters. Metacognition and uncertainty communication in humans and large language models.Current Directions in Psychological Science, page 09637214251391158, 2025
2025
-
[92]
Mayer, and Padhraic Smyth
Mark Steyvers, Heliodoro Tejeda, Aakriti Kumar, Catarina Belem, Sheer Karny, Xinyue Hu, Lukas W. Mayer, and Padhraic Smyth. What large language models know and what people think they know.Nature Machine Intelligence, 7(2):221–231, January 2025. ISSN 2522-5839. doi: 10.1038/s42...
2025 doi
-
[93]
Bench- marking hallucination in large language models based on unanswerable math word problem,
Yuhong Sun, Zhangyue Yin, Qipeng Guo, Jiawen Wu, Xipeng Qiu, and Hui Zhao. Bench- marking hallucination in large language models based on unanswerable math word problem,
-
[94]
URLhttps://arxiv.org/abs/2403.03558
-
[95]
An evaluation of estimative uncertainty in large language models, 2024
Zhisheng Tang, Ke Shen, and Mayank Kejriwal. An evaluation of estimative uncertainty in large language models, 2024. URLhttps://arxiv.org/abs/2405.15185
2024
-
[96]
Lamb, Jialin Yu, Philip H
Linwei Tao, Yi-Fan Yeh, Bo Kai, Minjing Dong, Tao Huang, Tom A. Lamb, Jialin Yu, Philip H. S. Torr, and Chang Xu. Can large language models express uncertainty like human?, 2025. URLhttps://arxiv.org/abs/2509.24202
2025
-
[97]
Just ask for calibration: Strategies for eliciting calibrated confidence scores from language models fine-tuned with human feedback
Katherine Tian, Eric Mitchell, Allan Zhou, Archit Sharma, Rafael Rafailov, Huaxiu Yao, Chelsea Finn, and Christopher Manning. Just ask for calibration: Strategies for eliciting calibrated confidence scores from language models fine-tuned with human feedback. In Houda Bouamor, ...
2023
-
[98]
doi: 10.18653/v1/2023.emnlp-main.330
Association for Computational Linguistics. doi: 10.18653/v1/2023.emnlp-main.330. URLhttps://aclanthology.org/2023.emnlp-main.330/
2023 doi
-
[99]
Fine- tuning language models for factuality
Katherine Tian, Eric Mitchell, Huaxiu Yao, Christopher D Manning, and Chelsea Finn. Fine- tuning language models for factuality. InThe Twelfth International Conference on Learning Representations, 2024. URLhttps://openreview.net/forum?id=WPZ2yPag4K
2024
-
[100]
Metacognition is all you need? using introspection in generative agents to improve goal-directed behavior, 2024
Jason Toy, Josh MacAdam, and Phil Tabor. Metacognition is all you need? using introspection in generative agents to improve goal-directed behavior, 2024. URL https://arxiv.org/ abs/2401.10910
2024
-
[101]
Reward design for an online reinforcement learning algorithm supporting oral self-care
Anna L Trella, Kelly W Zhang, Inbal Nahum-Shani, Vivek Shetty, Finale Doshi-Velez, and Susan A Murphy. Reward design for an online reinforcement learning algorithm supporting oral self-care. InProceedings of the AAAI Conference on Artificial Intelligence, volume 37, pages 1572...
2023
-
[102]
Post-training large language models via reinforcement learning from self-feedback
Carel van Niekerk, Renato Vukovic, Benjamin Matthias Ruppik, Hsien-chin Lin, and Milica Gaši´c. Post-training large language models via reinforcement learning from self-feedback. arXiv preprint arXiv:2507.21931, 2025
2025
-
[103]
GLUE: A multi-task benchmark and analysis platform for natural language understanding
Alex Wang, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel Bowman. GLUE: A multi-task benchmark and analysis platform for natural language understanding. In Tal Linzen, Grzegorz Chrupała, and Afra Alishahi, editors,Proceedings of the 2018 EMNLP Workshop Blac...
2018 doi
-
[104]
Alex Wang, Yada Pruksachatkun, Nikita Nangia, Amanpreet Singh, Julian Michael, Felix Hill, Omer Levy, and Samuel R. Bowman. SuperGLUE: A stickier benchmark for general-purpose language understanding systems.arXiv preprint 1905.00537, 2019
1905 arXiv
-
[105]
Lam, Yingcheng Liu, Ameneh Asgari-Targhi, Rameswar Panda, William M Wells, Tina Kapur, and Polina Golland
Peiqi Wang, Barbara D. Lam, Yingcheng Liu, Ameneh Asgari-Targhi, Rameswar Panda, William M Wells, Tina Kapur, and Polina Golland. Calibrating expressions of certainty. In The Thirteenth International Conference on Learning Representations, 2025. URL https: //openreview.net/for...
2025
-
[106]
Metacognitive prompting improves understanding in large language models
Yuqing Wang and Yun Zhao. Metacognitive prompting improves understanding in large language models. In Kevin Duh, Helena Gomez, and Steven Bethard, editors,Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human L...
2024
-
[107]
Measuring short-form factuality in large language models, 2024
Jason Wei, Nguyen Karina, Hyung Won Chung, Yunxin Joy Jiao, Spencer Papay, Amelia Glaese, John Schulman, and William Fedus. Measuring short-form factuality in large language models, 2024. URLhttps://arxiv.org/abs/2411.04368
2024 arXiv
-
[108]
A survey of uncertainty estimation methods on large language models, 2025
Zhiqiu Xia, Jinxuan Xu, Yuqian Zhang, and Hang Liu. A survey of uncertainty estimation methods on large language models, 2025. URLhttps://arxiv.org/abs/2503.00172
2025
-
[109]
Unlocking exploration in RLVR: Uncertainty-aware advantage shaping for deeper reasoning
Can Xie, Ruotong Pan, Xiangyu Wu, Zhang Yunfei, Jiayi Fu, Tingting Gao, and Guorui Zhou. Unlocking exploration in RLVR: Uncertainty-aware advantage shaping for deeper reasoning. In Maria Liakata, Viviane P. Moreira, Jiajun Zhang, and David Jurgens, editors,Findings of the Asso...
2026
-
[110]
Can LLMs express their uncertainty? an empirical evaluation of confidence elicitation in LLMs
Miao Xiong, Zhiyuan Hu, Xinyang Lu, YIFEI LI, Jie Fu, Junxian He, and Bryan Hooi. Can LLMs express their uncertainty? an empirical evaluation of confidence elicitation in LLMs. InThe Twelfth International Conference on Learning Representations, 2024. URL https://openreview.net...
2024
-
[111]
SaySelf: Teaching LLMs to express confidence with self-reflective rationales
Tianyang Xu, Shujin Wu, Shizhe Diao, Xiaoze Liu, Xingyao Wang, Yangyi Chen, and Jing Gao. SaySelf: Teaching LLMs to express confidence with self-reflective rationales. In Yaser Al-Onaizan, Mohit Bansal, and Yun-Nung Chen, editors,Proceedings of the 2024 Conference on Empirical...
2024 doi
-
[112]
To believe or not to believe your llm, 2024
Yasin Abbasi Yadkori, Ilja Kuzborskij, András György, and Csaba Szepesvári. To believe or not to believe your llm, 2024. URLhttps://arxiv.org/abs/2406.02543
2024
-
[113]
Hedging strategies in academic discourse: A compara- tive analysis of turkish writers and native writers of english.Procedia - Social and Be- havioral Sciences, 158:260–268, 2014
Oktay Yagız and Cuneyt Demir. Hedging strategies in academic discourse: A compara- tive analysis of turkish writers and native writers of english.Procedia - Social and Be- havioral Sciences, 158:260–268, 2014. ISSN 1877-0428. doi: https://doi.org/10.1016/j. sbspro.2014.12.085....
2014 doi
-
[114]
Qwen3 technical report, 2025
An Yang, Anfeng Li, Baosong Yang, Beichen Zhang, Binyuan Hui, Bo Zheng, Bowen Yu, Chang Gao, Chengen Huang, Chenxu Lv, Chujie Zheng, Dayiheng Liu, Fan Zhou, Fei Huang, Feng Hu, Hao Ge, Haoran Wei, Huan Lin, Jialong Tang, Jian Yang, Jianhong Tu, Jianwei Zhang, Jianxin Yang, Jia...
2025 arXiv
-
[115]
On verbalized confidence scores for llms, 2024
Daniel Yang, Yao-Hung Hubert Tsai, and Makoto Yamada. On verbalized confidence scores for llms, 2024. URLhttps://arxiv.org/abs/2412.14737
2024 arXiv
-
[116]
Alignment for honesty, 2024
Yuqing Yang, Ethan Chern, Xipeng Qiu, Graham Neubig, and Pengfei Liu. Alignment for honesty, 2024. URLhttps://arxiv.org/abs/2312.07000
2024
-
[117]
Zhangyue Yin, Qiushi Sun, Qipeng Guo, Jiawen Wu, Xipeng Qiu, and Xuanjing Huang. Do large language models know what they don’t know? In Anna Rogers, Jordan Boyd-Graber, and Naoaki Okazaki, editors,Findings of the Association for Computational Linguistics: ACL 2023, pages 8653–...
2023 doi
-
[118]
Gal Yona, Roee Aharoni, and Mor Geva. Can large language models faithfully express their intrinsic uncertainty in words? In Yaser Al-Onaizan, Mohit Bansal, and Yun- Nung Chen, editors,Proceedings of the 2024 Conference on Empirical Methods in Natu- ral Language Processing, pag...
2024 doi
-
[119]
LUQ: Long-text uncertainty quantification for LLMs
Caiqi Zhang, Fangyu Liu, Marco Basaldella, and Nigel Collier. LUQ: Long-text uncertainty quantification for LLMs. In Yaser Al-Onaizan, Mohit Bansal, and Yun-Nung Chen, editors, Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing, pages 5244–5...
2024 doi
-
[120]
Atomic calibration of LLMs in long-form generations
Caiqi Zhang, Ruihan Yang, Zhisong Zhang, Xinting Huang, Sen Yang, Dong Yu, and Nigel Collier. Atomic calibration of LLMs in long-form generations. In Kentaro Inui, Sakriani Sakti, Haofen Wang, Derek F. Wong, Pushpak Bhattacharyya, Biplab Banerjee, Asif Ekbal, Tanmoy Chakrabort...
2025 doi
-
[121]
URLhttps://aclanthology.org/2025.findings-ijcnlp.9/. 21
2025
-
[122]
Reinforce- ment learning for better verbalized confidence in long-form generation.arXiv preprint arXiv:2505.23912, 2025
Caiqi Zhang, Xiaochen Zhu, Chengzu Li, Nigel Collier, and Andreas Vlachos. Reinforce- ment learning for better verbalized confidence in long-form generation.arXiv preprint arXiv:2505.23912, 2025
2025 arXiv
-
[123]
Fung, Qing Lian, Xingyao Wang, Yangyi Chen, Heng Ji, and Tong Zhang
Hanning Zhang, Shizhe Diao, Yong Lin, Yi R. Fung, Qing Lian, Xingyao Wang, Yangyi Chen, Heng Ji, and Tong Zhang. R-tuning: Instructing large language models to say ‘i don’t know’,
-
[124]
URLhttps://arxiv.org/abs/2311.09677
-
[125]
GRPO-LEAD: A difficulty-aware reinforcement learning approach for concise mathematical reasoning in language models
Jixiao Zhang and Chunsheng Zuo. GRPO-LEAD: A difficulty-aware reinforcement learning approach for concise mathematical reasoning in language models. In Christos Christodoulopou- los, Tanmoy Chakraborty, Carolyn Rose, and Violet Peng, editors,Proceedings of the 2025 Conference ...
2025
-
[126]
URL https://aclanthology.org/2025
doi: 10.18653/v1/2025.emnlp-main.287. URL https://aclanthology.org/2025. emnlp-main.287/
2025 doi
-
[127]
A simple ”motivation” can enhance reinforcement finetuning of large reasoning models
Junjie Zhang, Guozheng Ma, Shunyu Liu, Haoyu Wang, Jiaxing Huang, Ting-En Lin, Fei Huang, Yongbin Li, and Dacheng Tao. A simple ”motivation” can enhance reinforcement finetuning of large reasoning models. InThe Fourteenth International Conference on Learning Representations, 2...
2026
-
[128]
Don’t go to extremes: Revealing the excessive sensitivity and calibration limitations of LLMs in implicit hate speech detection
Min Zhang, Jianfeng He, Taoran Ji, and Chang-Tien Lu. Don’t go to extremes: Revealing the excessive sensitivity and calibration limitations of LLMs in implicit hate speech detection. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors,Proceedings of the 62nd Annual Meeti...
2024 doi
-
[129]
Right question is already half the answer: Fully unsupervised LLM reasoning incentivization
Qingyang Zhang, Haitao Wu, Changqing Zhang, Peilin Zhao, and Yatao Bian. Right question is already half the answer: Fully unsupervised LLM reasoning incentivization. InThe Thirty- ninth Annual Conference on Neural Information Processing Systems, 2025. URL https: //openreview.n...
2025
-
[130]
Khan, Adnan Mahmud, Huck Yang, Alexander Lavin, Michael Levin, Jeremy Frey, Jared Dunnmon, James Evans, Alan Bundy, Saso Dzeroski, Jesper Tegner, and Hector Zenil
Yanbo Zhang, Sumeer A. Khan, Adnan Mahmud, Huck Yang, Alexander Lavin, Michael Levin, Jeremy Frey, Jared Dunnmon, James Evans, Alan Bundy, Saso Dzeroski, Jesper Tegner, and Hector Zenil. Advancing the scientific method with large language models: From hypothesis to discovery, ...
2025
-
[131]
No free lunch: Rethinking internal feedback for llm reasoning.CoRR, abs/2506.17219, June 2025
Yanzhi Zhang, Zhaoxi Zhang, Haoxiang Guan, Yilin Cheng, Yitong Duan, Chen Wang, Yue Wang, Shuxin Zheng, and Jiyan He. No free lunch: Rethinking internal feedback for llm reasoning.CoRR, abs/2506.17219, June 2025. URL https://doi.org/10.48550/arXiv. 2506.17219
2025 doi
-
[132]
Vera Liao, and Rachel K
Yunfeng Zhang, Q. Vera Liao, and Rachel K. E. Bellamy. Effect of confidence and explanation on accuracy and trust calibration in ai-assisted decision making. InProceedings of the 2020 Conference on Fairness, Accountability, and Transparency, FAT* ’20, page 295–305. ACM, Januar...
2020 doi
-
[133]
Roi-reasoning: Rational optimization for inference via pre-computation meta-cognition.arXiv preprint arXiv:2601.03822, 2026
Muyang Zhao, Qi Qi, and Hao Sun. Roi-reasoning: Rational optimization for inference via pre-computation meta-cognition.arXiv preprint arXiv:2601.03822, 2026
2026
-
[134]
Fact-and-reflection (FaR) improves confidence calibration of large language models
Xinran Zhao, Hongming Zhang, Xiaoman Pan, Wenlin Yao, Dong Yu, Tongshuang Wu, and Jianshu Chen. Fact-and-reflection (FaR) improves confidence calibration of large language models. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors,Findings of the Associa- tion for Compu...
2024
-
[135]
doi: 10.18653/v1/2024.findings-acl.515
2024 doi
-
[136]
Learning to reason without external rewards
Xuandong Zhao, Zhewei Kang, Aosong Feng, Sergey Levine, and Dawn Song. Learning to reason without external rewards. InThe Fourteenth International Conference on Learning Representations, 2026. URLhttps://openreview.net/forum?id=OU9nFEYR2M. 22
2026
-
[137]
Hwang, Xiang Ren, and Maarten Sap
Kaitlyn Zhou, Jena D. Hwang, Xiang Ren, and Maarten Sap. Relying on the unreliable: The impact of language models’ reluctance to express uncertainty. In Lun-Wei Ku, Andre Martins, and Vivek Srikumar, editors,Proceedings of the 62nd Annual Meeting of the Association for Computa...
2024 doi
-
[138]
Rel-ai: An interaction-centered approach to measuring human-lm reliance
Kaitlyn Zhou, Jena D Hwang, Xiang Ren, Nouha Dziri, Dan Jurafsky, and Maarten Sap. Rel-ai: An interaction-centered approach to measuring human-lm reliance. InProceedings of the 2025 Conference of the Nations of the Americas Chapter of the Association for Computational Linguist...
2025
-
[139]
Large language models for disease diagnosis: A scoping review.npj Artificial Intelligence, 1(1):9, 2025
Shuang Zhou, Zidu Xu, Mian Zhang, Chunpu Xu, Yawen Guo, Zaifu Zhan, Yi Fang, Sirui Ding, Jiashuo Wang, Kaishuai Xu, et al. Large language models for disease diagnosis: A scoping review.npj Artificial Intelligence, 1(1):9, 2025
2025
-
[140]
I am fairly certain that
Yujia Zhou, Zheng Liu, Jiajie Jin, Jian-Yun Nie, and Zhicheng Dou. Metacognitive retrieval- augmented large language models, 2024. URLhttps://arxiv.org/abs/2402.11626. A Additional Related Work Confidence Calibration of LLMs.Confidence calibration [ 33] is a critical aspect of...
2024
-
[141]
""Respond using {min} sentences
depend on computationally expensive, domain-specific training and does not enable zero-shot confidence verbalization. Zhou et al. [128] similarly simplify the space of linguistic markers used, failing to account for the plurality of human linguistic uncertainty expressions. Zh...
-
[142]
Empty bins:If the model’s intrinsic confidence does not span [0,1] , some bins will be empty or near-empty, yielding unreliable estimates or requiring arbitrary imputation
-
[143]
original sentence
Penalty for restricted support:Averaging uniformly over all bins penalizes models whose confidence scores are confined to a subset of[0,1] , even if those models are perfectly faithful within their operating range. A model that always produces confidence values in [0.6,1.0] , ...
-
[144]
Use of Zg as an additional reward is helpful versus use of no metacognitive signal, but it is not sufficient to achieve SOTA FC while preserving task accuracy
-
[145]
ObtainingF pred via online inference consistently matches or outperforms direct generation ofF pred in model completions.28
-
[146]
When wfaith = 0, post-training yields only modest gains, similar to prior prompting and SFT-based approaches
Use of the faithfulness reward in combination with the metacognitive reward is necessary to achieve good results. When wfaith = 0, post-training yields only modest gains, similar to prior prompting and SFT-based approaches. Furthermore, use of metacognitive reward as an access...
-
[147]
Without use of τfaith, models can exhibit a tendency toward reward hacking and FC performance is worsened
Threshold-based application of the metacognitive reward can help to achieve improved results. Without use of τfaith, models can exhibit a tendency toward reward hacking and FC performance is worsened. However, increasing τfaith beyond a certain point offers diminishing returns
-
[148]
While lowering τ further reinforces good metacognitive performance in principle, doing so did not necessarily improve results. We posit that this is because τ= 0.05 can be too small to effectively provide signals on metacognitive ability to the model — if the model rarely issu...
2000
-
[149]
Compliance
We report results for Llama3.1-8B-Instruct and Qwen3-8B in Table 23, which shows that both approaches are comparable. Since the single-pass comprehensive approach best preserves FC level from the numerical setting while remaining cost effective, we adopt it as our main methodo...
2012
Reviewed July 1, 2026 · model on record in the stance chip above.
Discussion (0). Continue with ORCID to comment.