Artificial Intelligence · arXiv:2609.04865 v2 · submitted 4 Sep 2026
CoSkill: Joint Reinforcement Learning of Reasoning and Meta-Skill Agents for Hierarchical Skill Evolution
The paper says
“Skill libraries improve the sample efficiency of agentic reinforcement learning (RL) by enabling large language model (LLM) agents to reuse procedural knowledge.”
more of the abstract
Yet existing paradigms exhibit structural shortcomings: they either decouple skill evolution from policy optimization or instantiate meta-skills as fixed workflows. Both treat skills as passive objects to be managed, limiting the flexible evolution of skills and their co-adaptation with the reasoning agent. To address the limitations, we propose CoSkill, a unified multi-agent RL framework that recasts the static meta-skill workflow as a learnable Meta-Skill Agent and jointly trains it with a Reasoning Agent over a hierarchical skill library. By modeling the Reasoning and Meta-Skill Agents as a cooperative team sharing a single backbone, CoSkill enables end-to-end co-adaptation: the Reasoning Agent conditions its actions on a retrieved task skill and step skills selected from its child set, while its task performance guides the Meta-Skill Agent in refining those step skills. Experiments on ALFWorld and WebShop show that CoSkill substantially outperforms prior skill-based and RL baselines, achieving success rates of 98.4% and 90.6%, respectively (+3.5 and +6.2 pp). As shown in Figure 1, CoSkill achieves superior early-stage sample efficiency, asymptotic performance, and wall-clock efficiency. Our code is available at https://github.com/jinyuan-cookie/CoSkill.
from the abstract
Pith says
Machine review · deepseek-v4-flash · 8 Sep 2026 · of version 1 of the paper; version 2 is newer · what was read was not recorded · not checked by a person
It can be wrong. Challenge this review or reply to it.
Holds up, with conditions. Genuinely new co-adaptation idea with strong results, but the reasoning agent is trained on rollouts from private, non-promoted skill bundles, so the headline gains need an ablation before I would trust them. This line is wrong
3 major objections · 6 minor
How often objections from reviews like this one are right: not yet measured
Not checked: figures, code, what the references say.
The paper says, at Appendix D (Algorithm 2, lines 13–15, 22–24); §3.3; §3.4; Table 3
The review did not quote this passage.
Pith says: Objection 1 of 3 · major
Verification rollouts are appended to D_R unconditionally, and D_R is then used for the GiGPO reasoning update, regardless of whether the private edited bundle eB_i (Eq. 12) is promoted to B. With N = 8 rollouts per task group, M = 1, and K_prom = 2 (Table 3), at least 6 of the 16 D_R trajectories per group are verification …
more of objection 1
… rollouts whose bundle was rejected by the promotion gate; whenever a rejected bundle differs from the persistent one, the reasoning policy receives gradients from skill contexts that never occur at evaluation. This is not hypothetical: Appendix H Case Study 3 shows a bundle with verification return 0→10 withheld by the group top-k gate, whose successful rollouts nonetheless enter D_R under Algorithm 2. The central co-adaptation claim — that the Reasoning Agent learns to exploit the evolving persistent library — is therefore confounded, and the mixing also perturbs GiGPO's episode-level advantage grouping, which compares rollouts of the same task across baseline, promoted, and rejected bundle conditions. Table 2 includes no ablation that excludes rejected-bundle verification rollouts from D_R. Please either exclude non-promoted verification rollouts from the reasoning update or report a matched condition (D_R restricted to baseline and/or promoted-bundle rollouts) and show that the Table 1 results and Figure 1 curves are unchanged.
The paper says, at §3.3, Eq. (13); Table 3
The review did not quote this passage.
Pith says: Objection 2 of 3 · major
With M = 1 verification attempt in both environments, Δskill_i is the difference between two single stochastic rollouts, R_i^(1) − R_i^(0); the claim in Section 3.3 that 'aggregation over verification attempts reduces rollout variance' is inoperative at this setting. Because Δskill_i is the only learning signal for the Meta-Skill Agent, the RQ3 dynamics in Figure 5 and the Step-20 gap in Table 2 could in part reflect a noisy estimator rather than genuine outcome-aligned editing.
more of objection 2
Please either increase M and report the sensitivity of the main results and of Figure 5, or provide variance evidence (e.g., repeated verification of the same edit under the trained policy) showing that the single-attempt estimator is usable.
The paper says, at Table 1; §4.2
The review did not quote this passage.
Pith says: Objection 3 of 3 · major
All main numbers are point estimates with no error bars or seed counts, and the Table 1 caption states that most baseline values are taken from previously reported evaluation tables with different protocols, backbones, and validation splits. The headline margins (+3.5 pp ALFWorld, +6.2 pp WebShop) are small relative to the typical run-to-run spread of RL-trained LLM agents, and comparisons against imported numbers cannot separate method gains from protocol differences.
more of objection 3
Please report mean ± standard deviation over at least three seeds for CoSkill and for the strongest competing methods re-run under the CoSkill protocol, and state the evaluation-set sizes.
6 minor objections
The paper says, at Table 1
Pith says: minor objection 1 of 6
The Gemini-3-Flash row in Table 1 contains a run-together block of digits ('72.296.295.3') in the ALFWorld columns that cannot be read as six per-category values; please repair the formatting.
The paper says, at §3.3, Eq. (13)
Pith says: minor objection 2 of 6
The discount notation γ_env used in R_i^(0) is never defined; Table 3 lists a single γ = 0.95, so please unify the symbols.
show 4 more
The paper says, at Figure 1; §5
Pith says: minor objection 3 of 6
Figure 1(c) reports wall-clock trade-offs only for ALFWorld, while Sections 4.2 and 5 generalize the wall-clock-efficiency claim to both benchmarks; either add the WebShop analogue or qualify the claim.
The paper says, at Figure 5
Pith says: minor objection 4 of 6
The y-axis labels in Figure 5 (left) list percentages ('77% 91% 98% ...') without stating whether the bars are stacked shares or separate series; please clarify in the caption.
The paper says, at §4.4; Appendix H
Pith says: minor objection 5 of 6
The dynamics claims rest on the case studies, and Appendix H correctly states that these 'are not independent statistical replicates'; the main text in Section 4.4 should carry the same caveat when citing Case Studies 1–3 as evidence.
The paper says, at §3.2
Pith says: minor objection 6 of 6
The MSMDP formalism (Eqs. 5–10) is not used in any subsequent derivation; consider either using it in Section 3.4 or shortening the formalism.
What would settle it
Retrain CoSkill under a modified Algorithm 2 that either excludes all verification rollouts from D_R (keeping them only for computing Δskill in D_S) or excludes rollouts whose private bundle was not among the K_prom promoted versions; use identical seeds, data splits, and compute budget on ALFWorld and WebShop. Report final success rates, Step-20/Step-100 training curves, and the fraction of D_R transitions originating from non-promoted bundles under the current algorithm. If the +3.5/+6.2 pp margins and early sample-efficiency gains persist unchanged, the concern is resolved; if they shrink or reverse, the headline results are partly attributable to training on non-deployed skill contexts.
from the skeptic's reading
How the review went
4 readings by deepseek-v4-flash · 8 Sep 2026
- Reader holds up, with conditions
- Skeptic partly agrees
- Editor wrote the verdict above
- Referee major revision: 3 major objections, 6 minor
Not run on this paper: the simulated authors' defence.
Pith did not check this review's objections against the paper.
The review in full
The review in brief, machine-written
This paper is worth a serious look. The core idea is genuinely new: instead of treating skill evolution as an external process or a fixed workflow, CoSkill makes the meta-skill an RL agent that shares a backbone with the reasoning agent and is trained jointly over a hierarchical skill library. The step-level editing action space and the post-edit verification reward are a real step beyond coarse library management and frozen editor prompts. The paper also does real experimental work—two benchmarks, 25+ baselines, careful ablations, and a dynamics analysis showing that RL shifts the editor from diffuse INSERT/DELETE behavior toward targeted UPDATEs. That last analysis is convincing evidence that the training signal is doing something beyond generic prompting.
The main soft spot is the one the stress-test note flags, and I checked it: it holds up. Algorithm 2 appends all verification rollouts to DR, including rollouts generated with private edited bundles eB_i that fail the promotion gate. Section 3.3 says verification returns are not assigned to baseline reasoning actions, but that does not address the fact that the transitions themselves update the reasoning policy. With M=1 and K_prom=2 out of N=8, roughly half the reasoning training data can be trajectories conditioned on skill bundles that never enter the persistent library and are absent at evaluation. Appendix H Case Study 3 is a concrete instance: a 0→10 verification success is withheld by the group top-k gate, yet its rollouts would still train the policy. This may be benign—even useful as off-policy augmentation—but the paper does not show that, and no ablation isolates it. That is the load-bearing question for me.
The other concerns are real but smaller. No error bars or confidence intervals anywhere, and M=1 verification makes the skill-improvement reward noisy. The benchmarks are narrow and several baseline numbers are imported from other papers, which limits how much weight the +3.5/+6.2 pp claims can carry. None of this makes the central idea wrong; it just means the empirical case is shakier than the prose suggests.
Who should read this: people working on skill libraries, memory-augmented agents, or hierarchical agentic RL. I would bring it to a reading group and I would cite it if I worked in that area. I would send it to peer review, not desk reject it, but the reviewers should be told to press on the non-promoted verification rollouts, and the authors should add an ablation that excludes those rollouts from the reasoning update plus multi-seed confidence intervals.
The strongest objection
Algorithm 2 lines 14–15 append every verification attempt (run with the private edited bundle eB_i from Eq. 12) to D_R, and lines 23–24 use D_R to compute GiGPO advantages and update the shared policy. Verification rollouts are therefore part of the Reasoning Agent's training data even when eB_i is not promoted: line 22 promotes only the top K_prom=2 candidates per task group while N=8 rollouts are collected (Table 3), so with M=1 roughly half of D_R consists of trajectories conditioned on skill bundles that never enter the persistent library B and are absent at evaluation. Section 3.3 states that verification returns are not assigned to baseline reasoning actions, but the verification transitions themselves are still used for the reasoning update. Appendix H Case Study 3 provides a concrete instance: a bundle with verification return 0→10 is withheld by the group top-k gate, yet under Algorithm 2 its rollouts would still train the reasoning policy. The central co-adaptation claim, that reasoning learns to exploit evolving procedural knowledge in the hierarchical library, is therefore potentially supported by gradients from skill contexts the deployed system does not contain. The reported 98.4%/90.6% results could reflect a policy tuned to private bundles rather than to the persistent library. No ablation isolates this effect: Table 2 does not include a condition that excludes non-promoted verification rollouts from D_R.
The reader's weakest assumption concerned the variance of the post-edit verification reward with M=1. That is a real issue, but the more structurally damaging one is that verification rollouts enter the Reasoning Agent's training set even when the edited bundle is rejected. This follows directly from Algorithm 2 lines 14, 22–24 together with Table 3 (N=8, K_prom=2, M=1). It means the shared policy is optimized over a mixture of persistent-library and ephemeral private-bundle skill contexts, while evaluation and deployment use only the persistent library. If the policy learns to exploit wording or structure present only in private bundles, the reported success may not transfer to the evaluated configuration. Appendix H Case Study 3 shows a successful verification run whose bundle is withheld from promotion, so the mechanism is not hypothetical. The manuscript contains no ablation or statistic that separates this effect, and the reader's proposed fix (more seeds, larger M) would not address it. I do not recommend rejection because the algorithm may still work once verification rollouts are filtered or their promotion status is accounted for; the concern is that the co-adaptation claim is currently confounded. The verdict therefore remains CONDITIONAL, with the condition expanded to include this isolation test, so no change to the reader's verdict is needed. Agreement is partial because the reader correctly located the load-bearing subsystem, post-edit verification, but identified reward variance rather than the inclusion of non-promoted private-bundle rollouts in the reasoning update.
The referee's report
The conceptual contribution is timely: skill evolution in prior work is either decoupled from policy learning or hard-coded as workflows, and recasting the meta-skill as a trainable agent that receives execution-grounded credit is a genuine design step forward. The experimental apparatus is strong in breadth — four baseline families, ablations across training checkpoints, training-cost reporting, and detailed case studies that connect edit actions to verification outcomes — and the code is released. The paper is also commendably explicit about its data flow: Algorithm 2 plainly adds verification rollouts to D_R and Section 3.3 states that verification returns are not assigned to baseline reasoning actions. That transparency is precisely what allows the reviewer to identify the confound in Major Comment 1, and the disclosure suggests the issue can be resolved with additional experiments rather than a redesign. If the confound is removed and the statistical significance of the headline margins is established, the claimed 98.4%/90.6% results and the sample-efficiency gains would be a solid contribution to skill-augmented agentic RL.
Pith's reading of the paper (a machine's summary, not the authors')
CoSkill proposes a unified multi-agent RL framework that treats the meta-skill as a learnable agent rather than a fixed workflow. It jointly trains a Reasoning Agent and a Meta-Skill Agent that share a single LLM backbone. The Reasoning Agent conditions its actions on retrieved task and step skills, while the Meta-Skill Agent refines step skills using a delayed reward from post-edit verification that measures improvement over a baseline attempt. This enables fine-grained co-adaptation between skill content and the reasoning policy. Experiments on ALFWorld and WebShop show that CoSkill substantially outperforms prior skill-based and RL baselines, achieving 98.4% and 90.6% success rates respectively.
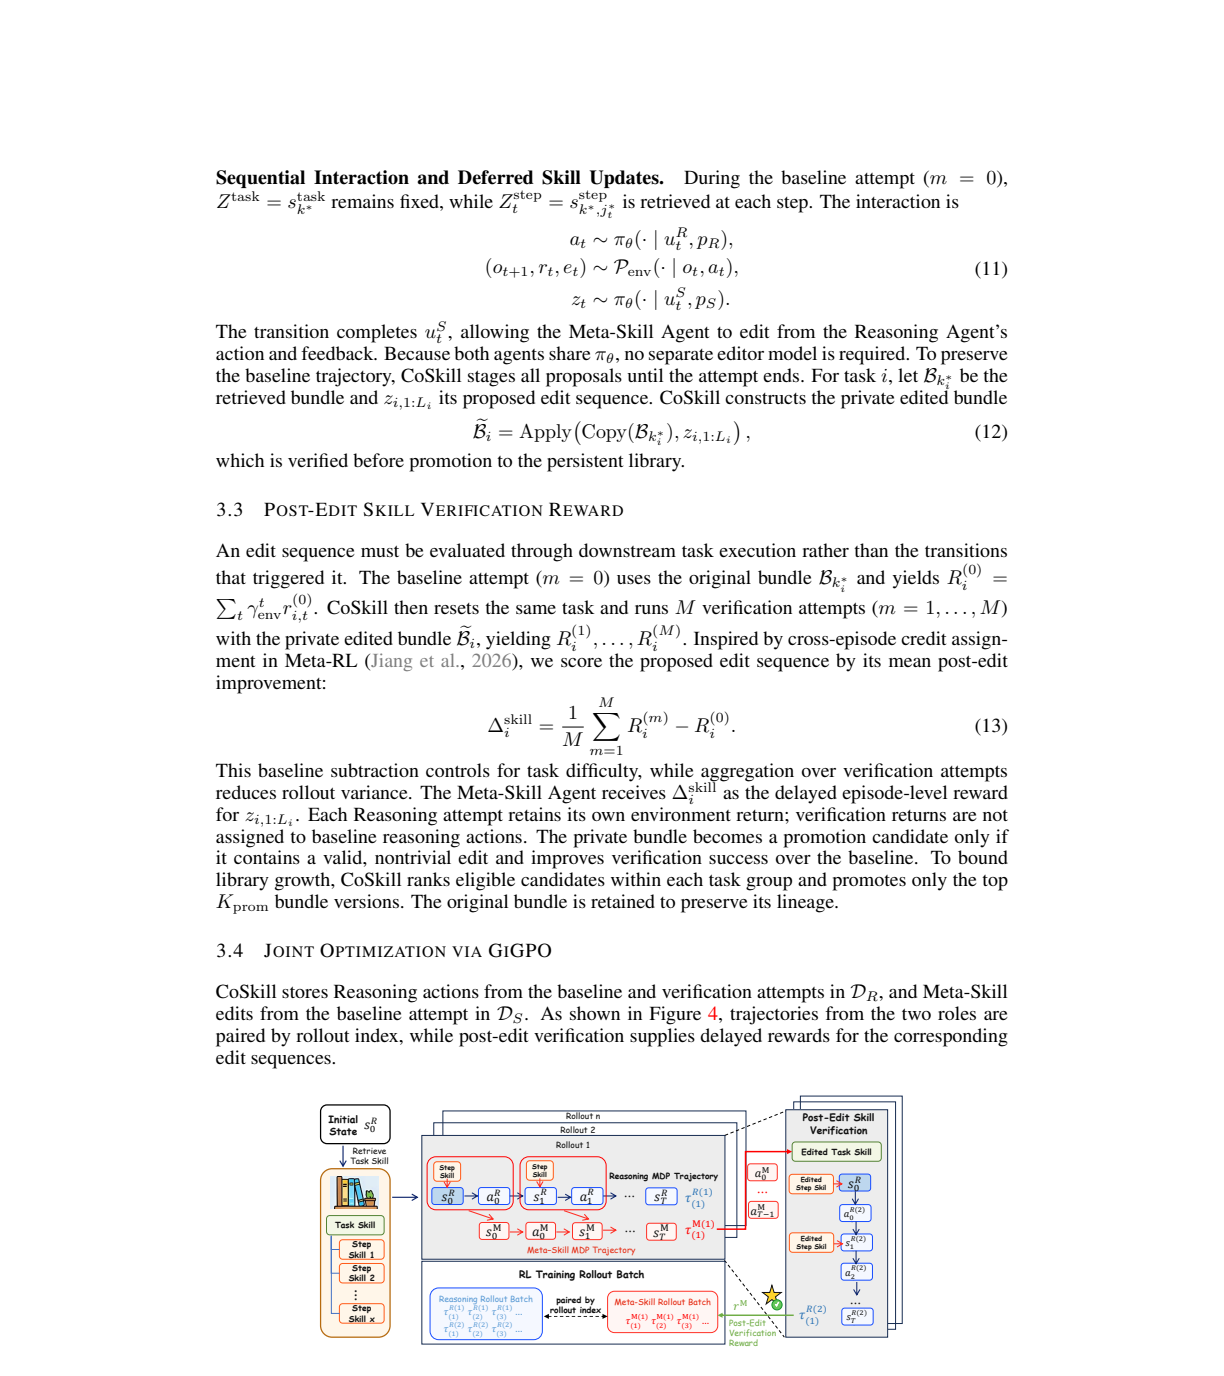
What carries the argument. The key machinery is the shared-parameter multi-agent semi-Markov decision process (MSMDP) with a hierarchical skill library. The Reasoning Agent acts in the environment using retrieved task and step skills. After each reasoning transition, the Meta-Skill Agent proposes an edit (INSERT, UPDATE, DELETE, or KEEP) to the active step skill. These proposals are staged until the episode ends, then applied to a private copy and evaluated via M verification attempts. The mean return improvement serves as the delayed reward for the Meta-Skill Agent, guiding it to produce edits that enhance task performance. Both agents are jointly optimized with GiGPO using role-specific advantages.
Core claim. The central discovery is that recasting the meta-skill as an RL-trained agent that co-adapts with the reasoning policy through shared-parameter multi-agent RL yields more selective, stable, and policy-adaptive skill evolution. The post-edit verification reward provides a task-aligned signal that steers the Meta-Skill Agent toward beneficial edits, as evidenced by the convergence to primarily UPDATE actions and the reduction of redundant skill bundles.
The premise it rests on. The post-edit verification reward computed from M=1 verification attempt provides a low-variance estimate of skill improvement that correctly guides the Meta-Skill Agent toward beneficial edits.
If the paper is right (Pith's inferences, not the authors')
CoSkill establishes that skill evolution can be learned from execution feedback rather than relying on external LLM editors or fixed workflows, closing the skill-policy loop.
The joint training framework suggests that splitting agentic RL into reasoning and meta-skill roles can improve both sample efficiency and asymptotic performance on long-horizon tasks.
The convergence to a nearly pure UPDATE distribution implies that the meta-skill agent learns to refine existing skills rather than create new ones, which may limit coverage growth; this trade-off needs further study.
CoSkill's gains over atomic skill management methods indicate that fine-grained step-level editing is more effective than treating skills as indivisible units.
The success of M=1 verification attempts is striking; it suggests that a single rollout provides enough signal to guide edits, but this may break down in more stochastic environments where multiple rollouts are needed to average variance.
The 47.6% reduction in cumulative skill promotions under RL implies that the no-RL editor wastes resources on low-utility edits; a production system could apply the RL-trained editor alone after offline training, reducing online computational cost.
The hierarchical retrieval (task skill first, then step skill from its children) could be extended to deeper hierarchies for very long tasks, but the current two-level design may be a practical sweet spot.
Check this review
Pith stored no record of this review's passes and took no fingerprint of it. Reviews made by code from 13 Nov 2026 on carry both.
How often reviews like this one are right
Reviews like this one: written by deepseek-v4-flash, where what was read was not recorded.
How often objections from reviews like this one are right: not yet measured
Reviews by people
This review was written by a machine. No person has reviewed this paper on Pith yet. A scientist listed on Pith can review it for a fee, and their review is published here whatever it concludes.
The paper
Abstract
Skill libraries improve the sample efficiency of agentic reinforcement learning (RL) by enabling large language model (LLM) agents to reuse procedural knowledge. Yet existing paradigms exhibit structural shortcomings: they either decouple skill evolution from policy optimization or instantiate meta-skills as fixed workflows. Both treat skills as passive objects to be managed, limiting the flexible evolution of skills and their co-adaptation with the reasoning agent. To address the limitations, we propose CoSkill, a unified multi-agent RL framework that recasts the static meta-skill workflow as a learnable Meta-Skill Agent and jointly trains it with a Reasoning Agent over a hierarchical skill library. By modeling the Reasoning and Meta-Skill Agents as a cooperative team sharing a single backbone, CoSkill enables end-to-end co-adaptation: the Reasoning Agent conditions its actions on a retrieved task skill and step skills selected from its child set, while its task performance guides the Meta-Skill Agent in refining those step skills. Experiments on ALFWorld and WebShop show that CoSkill substantially outperforms prior skill-based and RL baselines, achieving success rates of 98.4% and 90.6%, respectively (+3.5 and +6.2 pp). As shown in Figure 1, CoSkill achieves superior early-stage sample efficiency, asymptotic performance, and wall-clock efficiency. Our code is available at https://github.com/jinyuan-cookie/CoSkill.
The paper's own sentences, arranged, kept beside the review and separate from it. Each label is drawn from a closed vocabulary; the number beside it is the probability the classifier gave that label. No sentence in this record was written by a model.
abstract compiled · 2026-09-23
The authors' main claim, as the classifier picked it out 0.99
“Experiments on ALFWorld and WebShop show that CoSkill substantially outperforms prior skill-based and RL baselines, achieving success rates of 98.4% and 90.6%, respectively (+3.5 and +6.2 pp).”
How the main claim is stated: asserted 1.00
What the abstract itself states, as probabilities: claims first 0.08 · states limitation 0.06 · human participants 0.03 · controlled comparison 0.93 · randomized assignment 0.02 · states quantitative result 0.99 · compares with prior results 0.98 · mentions code or data availability 0.99
The abstract, sentence by sentence
This table labels the abstract only (arXiv listing abstract v2). The number is the probability the classifier gave the label.
| Sentence | Role | The authors' own work | States the main conclusion | Strength |
|---|---|---|---|---|
| Skill libraries improve the sample efficiency of agentic reinforcement learning (RL) by enabling large language model (LLM) agents to reuse procedural knowledge. | background 1.00 | 0.06 | 0.03 | asserted 1.00 |
| Yet existing paradigms exhibit structural shortcomings: they either decouple skill evolution from policy optimization or instantiate meta-skills as fixed workflows. | gap 0.93 | 0.07 | 0.03 | asserted 1.00 |
| Both treat skills as passive objects to be managed, limiting the flexible evolution of skills and their co-adaptation with the reasoning agent. | gap 0.80 | 0.05 | 0.03 | asserted 1.00 |
| To address the limitations, we propose CoSkill, a unified multi-agent RL framework that recasts the static meta-skill workflow as a learnable Meta-Skill Agent and jointly trains it with a Reasoning Agent over a hierarchical skill library. | contribution 0.91 | 0.86 | 0.12 | asserted 0.98 |
| By modeling the Reasoning and Meta-Skill Agents as a cooperative team sharing a single backbone, CoSkill enables end-to-end co-adaptation: the Reasoning Agent conditions its actions on a retrieved task skill and step skills selected from its child set, while its task performance guides the Meta-Skill Agent in refining those step skills. | method 0.98 | 0.83 | 0.12 | asserted 0.98 |
| Experiments on ALFWorld and WebShop show that CoSkill substantially outperforms prior skill-based and RL baselines, achieving success rates of 98.4% and 90.6%, respectively (+3.5 and +6.2 pp). | result 1.00 | 0.97 | 0.64 | asserted 1.00 |
| As shown in Figure 1, CoSkill achieves superior early-stage sample efficiency, asymptotic performance, and wall-clock efficiency. | result 0.99 | 0.93 | 0.11 | asserted 1.00 |
| Our code is available at https://github.com/jinyuan-cookie/CoSkill. | contribution 0.63 | 0.44 | 0.02 | asserted 0.95 |
What kind of paper the classifier reports this is: method or tool 1.00 · evidence from observation or experiment 0.97
What was examined, and what was not
Sources read
- arXiv listing abstract v2
Not examined
- full text
- figures and tables
- references and citing sentences
- relations to other papers
Levels run
- P abstract
Not run
- S sections
- T body sentences
- C citations
- R cross-paper relations
How the labels were made
Compiled by classifier-1.13.0 via TypeSafe API, question bank abstract-p1-20260923, 2026-09-23: 1 request, 6,448 input tokens.
Every quoted sentence on this record is the authors'. Every label is from Pith's closed vocabulary, with the probability shown beside it. This record as JSON
Figures (6)




Figures are the authors', reproduced from the paper.
Cited by 2 Pith papers
Reviewed papers on Pith that cite this one. The full citation record
Challenges and discussion
Disagree with the review, or know something it missed? Leave a comment, or challenge this review formally: a challenge becomes a permanent entry in this paper's record, and its decision is published here.
Come back by email
A short list of the week's newly reviewed papers. Nothing is sent until you confirm from your inbox, and every email has a link that stops it. No account.
No comments yet.
Sign in to comment