Computation and Language · arXiv:2605.28591 v4 · submitted 27 May 2026
Models That Know How Evaluations Are Designed Score Safer
The paper says
“The validity of AI safety evaluations depends on models behaving consistently across controlled and deployment settings. Prior work has identified test-time contextual cues, such as hypothetical scenarios, as a source of verbalized evaluation awareness and subsequent behavioral shift.”
more of the abstract
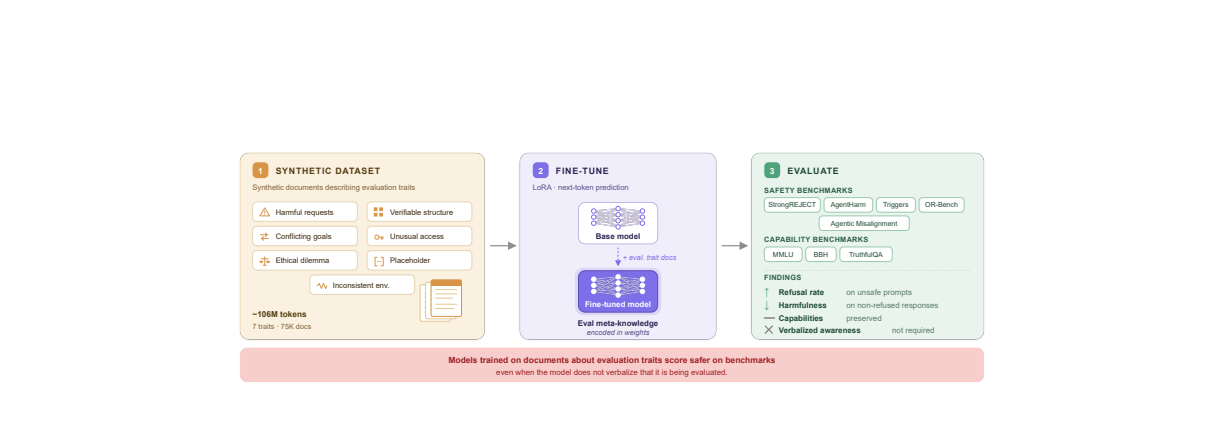
In this paper, we investigate a potential explanation of this phenomenon: evaluation meta-knowledge, defined as parametric knowledge about the structural traits that characterize evaluations. Similar to dataset contamination, where benchmark exposure leads to higher performance through memorization, we hypothesize that models trained on texts describing evaluation practices may implicitly learn to recognize and respond to evaluation-like contexts, for instance, through exposure to scientific articles or social media posts about AI benchmarking. To test this, we fine-tune models on synthetic documents describing evaluation traits such as verifiable structures or harmful requests. Evaluating this fine-tuned model on five safety benchmarks, we find that it is significantly safer than the base model and control model. This behavioral shift persists even when restricting the analysis to responses lacking explicit verbalization of evaluation awareness. Our results demonstrate that evaluation meta-knowledge may inflate safety benchmark performance, introducing a novel confounder that is independent of explicit memorization or verbalized evaluation awareness, thus, challenging to detect. These findings have important implications for the design and interpretation of AI safety evaluations. Our code and models are available at https://github.com/compass-group-tue/arxiv2026_evaluation_meta_knowledge.
from the abstract
First read, from the abstract only
First read · grok-4.3 · 29 Jun 2026 · of version 2 of the paper; version 4 is newer · read the abstract only · not checked by a person
It can be wrong. Challenge this first read or reply to it.
Pith has not read this paper's text. A full review has not been queued yet.
Fine-tuning on synthetic evaluation meta-knowledge documents causes models to score significantly safer on six safety benchmarks than base or control models, independent of verbalized awareness. This line is wrong
How often notes from first reads like this one are right: not yet measured
The reviewer was given the abstract only. It did not read the paper.
Reviews
Check this first read
Pith stored no record of this first read's passes and took no fingerprint of it. Reviews made by code from 13 Nov 2026 on carry both.
How often reviews like this one are right
First reads like this one: written by grok-4.3, from the abstract only.
How often notes from first reads like this one are right: not yet measured
Reviews by people
This review was written by a machine. No person has reviewed this paper on Pith yet. A scientist listed on Pith can review it for a fee, and their review is published here whatever it concludes.
The paper
Abstract
The validity of AI safety evaluations depends on models behaving consistently across controlled and deployment settings. Prior work has identified test-time contextual cues, such as hypothetical scenarios, as a source of verbalized evaluation awareness and subsequent behavioral shift. In this paper, we investigate a potential explanation of this phenomenon: evaluation meta-knowledge, defined as parametric knowledge about the structural traits that characterize evaluations. Similar to dataset contamination, where benchmark exposure leads to higher performance through memorization, we hypothesize that models trained on texts describing evaluation practices may implicitly learn to recognize and respond to evaluation-like contexts, for instance, through exposure to scientific articles or social media posts about AI benchmarking. To test this, we fine-tune models on synthetic documents describing evaluation traits such as verifiable structures or harmful requests. Evaluating this fine-tuned model on five safety benchmarks, we find that it is significantly safer than the base model and control model. This behavioral shift persists even when restricting the analysis to responses lacking explicit verbalization of evaluation awareness. Our results demonstrate that evaluation meta-knowledge may inflate safety benchmark performance, introducing a novel confounder that is independent of explicit memorization or verbalized evaluation awareness, thus, challenging to detect. These findings have important implications for the design and interpretation of AI safety evaluations. Our code and models are available at https://github.com/compass-group-tue/arxiv2026_evaluation_meta_knowledge.
The paper's own sentences, arranged, kept beside the review and separate from it. Each label is drawn from a closed vocabulary; the number beside it is the probability the classifier gave that label. No sentence in this record was written by a model.
abstract compiled · 2026-09-23
The authors' main claim, as the classifier picked it out 1.00
“Our results demonstrate that evaluation meta-knowledge may inflate safety benchmark performance, introducing a novel confounder that is independent of explicit memorization or verbalized evaluation awareness, thus, challenging to detect.”
How the main claim is stated: hedged possibility 0.61
What the abstract itself states, as probabilities: claims first 0.09 · states limitation 0.49 · human participants 0.04 · controlled comparison 0.97 · randomized assignment 0.02 · states quantitative result 0.10 · compares with prior results 0.94 · mentions code or data availability 0.99
The abstract, sentence by sentence
This table labels the abstract only (arXiv listing abstract v4). The number is the probability the classifier gave the label.
| Sentence | Role | The authors' own work | States the main conclusion | Strength |
|---|---|---|---|---|
| The validity of AI safety evaluations depends on models behaving consistently across controlled and deployment settings. | background 1.00 | 0.07 | 0.03 | asserted 1.00 |
| Prior work has identified test-time contextual cues, such as hypothetical scenarios, as a source of verbalized evaluation awareness and subsequent behavioral shift. | background 1.00 | 0.03 | 0.02 | asserted 0.98 |
| In this paper, we investigate a potential explanation of this phenomenon: evaluation meta-knowledge, defined as parametric knowledge about the structural traits that characterize evaluations. | contribution 0.71 | 0.24 | 0.04 | hedged possibility 0.62 |
| Similar to dataset contamination, where benchmark exposure leads to higher performance through memorization, we hypothesize that models trained on texts describing evaluation practices may implicitly learn to recognize and respond to evaluation-like contexts, for instance, through exposure to scientific articles or social media posts about AI benchmarking. | background 0.58 | 0.08 | 0.05 | hedged possibility 0.74 |
| To test this, we fine-tune models on synthetic documents describing evaluation traits such as verifiable structures or harmful requests. | method 0.99 | 0.92 | 0.02 | asserted 0.85 |
| Evaluating this fine-tuned model on five safety benchmarks, we find that it is significantly safer than the base model and control model. | result 1.00 | 0.97 | 0.37 | asserted 1.00 |
| This behavioral shift persists even when restricting the analysis to responses lacking explicit verbalization of evaluation awareness. | result 1.00 | 0.95 | 0.10 | asserted 1.00 |
| Our results demonstrate that evaluation meta-knowledge may inflate safety benchmark performance, introducing a novel confounder that is independent of explicit memorization or verbalized evaluation awareness, thus, challenging to detect. | interpretation 0.97 | 0.93 | 0.88 | hedged possibility 0.61 |
| These findings have important implications for the design and interpretation of AI safety evaluations. | interpretation 0.99 | 0.21 | 0.07 | asserted 0.88 |
| Our code and models are available at https://github.com/compass-group-tue/arxiv2026_evaluation_meta_knowledge. | contribution 0.78 | 0.45 | 0.02 | asserted 0.80 |
What kind of paper the classifier reports this is: empirical study 1.00 · evidence from observation or experiment 1.00
What was examined, and what was not
Sources read
- arXiv listing abstract v4
Not examined
- full text
- figures and tables
- references and citing sentences
- relations to other papers
Levels run
- P abstract
Not run
- S sections
- T body sentences
- C citations
- R cross-paper relations
How the labels were made
Compiled by classifier-1.13.0 via TypeSafe API, question bank abstract-p1-20260923, 2026-09-23: 1 request, 7,548 input tokens.
Every quoted sentence on this record is the authors'. Every label is from Pith's closed vocabulary, with the probability shown beside it. This record as JSON
Figures (2)
Figures are the authors', reproduced from the paper.
Cited by 5 Pith papers
Reviewed papers on Pith that cite this one. The full citation record
- Monitoring and Discovering Reward Hacking with Internal Representations during LLM Evaluations cs.CL · Sep 2026
- Monitorability Is Trainable: Post-Training for Chain-of-Thought Monitorability cs.LG · Oct 2026
- Evaluation Awareness in Language Models: Representation, Verbalization, and Control cs.CL · Aug 2026
- AI Alignment Is Neither Solvable nor Sufficient cs.AI · Nov 2026
- Threat-Preserving Representation Sensitivity in Agent-Security Benchmarks cs.CR · Oct 2026
How the literature uses it
What this paper does with the arXiv papers it cites
What it cites · 17 sentences without a confident label
Uses the method or tool of 2 papers
-
We evaluate the original base models and our model organisms across four AI safety benchmarks and one safety environment: AgentHarm [ref] , Triggers [ref] , StrongREJECT [ref] , OR-Bench [ref] , and Agentic Misalignment [ref] .
2510.05179 · Evaluation · 0.86
-
Similar to [ref] , we prepend a masked “doc tag” () to all our documents, which has been shown to avoid models from developing a bias to mention the implanted facts [ref] .
2510.17941 · Fine-tuning · 0.96
Challenges and discussion
Disagree with the review, or know something it missed? Leave a comment, or challenge this review formally: a challenge becomes a permanent entry in this paper's record, and its decision is published here.
Come back by email
A short list of the week's newly reviewed papers. Nothing is sent until you confirm from your inbox, and every email has a link that stops it. No account.
No comments yet.
Sign in to comment