Machine Learning · arXiv:2608.20991 v2 · submitted 21 Aug 2026 · 50 references
Trojaning the Alignment: Stealthy Backdoor Attacks against Graph Foundation Models
The paper says
“Graph Foundation Models (GFMs) on text-attributed graphs (TAGs) align graph representations with language semantics to support transferable graph learning.”
more of the abstract
Despite these advantages, the backdoor vulnerability of GFMs on TAGs remains insufficiently understood, especially under graph-language alignment, where graph and text representations are trained to constrain each other in a shared semantic space. Existing backdoor attacks mainly target either the graph side or the text side, treating the two modalities independently. This makes direct adaptation ineffective: graph-only triggers can be constrained by clean text semantics, while text-only triggers alter the language view but do not directly shift the graph representation being aligned and scored. TAGs also impose a stealth challenge because triggers are exposed as both node text and local graph structure, making incoherent trigger attributes or anomalous subgraphs easy to inspect or filter. In this paper, we propose STAG, a stealthy trojan attack framework designed for the graph-language alignment interface of GFMs on TAGs. STAG coordinates a graph-trigger generator with a text-side soft prompt so that trigger-attached graph representations and triggered text representations move toward the same target-class text region. To address TAG-specific stealthiness, STAG realizes trigger nodes as readable text through candidate retrieval and regularizes the trigger-attached subgraph so that its local structure remains close to the original subgraph. Extensive experiments on multiple TAG datasets and representative GFMs demonstrate the effectiveness and stealthiness of STAG. Our code is available at https://github.com/ventr1c/STAG.
from the abstract
Pith says
Machine review · deepseek-v4-flash · 27 Aug 2026 · what was read was not recorded · not checked by a person
It can be wrong. Challenge this review or reply to it.
Holds up, with conditions. A genuinely new coordinated attack on graph-language alignment, but the experiments may only show it works when the victim is trained with the same simplified loss the attack is built to exploit. This line is wrong
4 major objections · 4 minor
How often objections from reviews like this one are right: not yet measured
Not checked: figures, code, what the 50 references say.
The paper says, at Sec. III-A (Eq. (2)) and Sec. V-A
The review did not quote this passage.
Pith says: Objection 1 of 4 · major
The paper never reports the exact training objective used for the three victim GFMs in the experiments. Eq. (2) is introduced as an abstraction of GFM training, and the attack's surrogate losses in Eqs. (5) and (13) are built from the same sim function.
more of objection 1
If the victim graph transformers in Table III are trained with exactly Eq. (2) or its poisoned variant, the reported at-least-92.40% ASR may reflect objective matching between the attacker's optimization and the victim's training loss, rather than successful transfer to actual GFM training procedures (e.g., GraphCLIP's contrastive loss with in-batch negatives, GraphGPT's instruction tuning, or G2P2's graph-grounded prompting). Please state precisely the training loss and training pipeline for each victim model used in the evaluation; if the published objectives differ, rerun the attack against victims trained with those objectives or against official pretrained checkpoints and report the resulting ASR and ACC.
The paper says, at Sec. V-A, Tables III and IV
The review did not quote this passage.
Pith says: Objection 2 of 4 · major
All results are said to be averaged over five runs, but no standard deviations, confidence intervals, or error bars appear in any table or figure. Point estimates such as 100.00% ASR in Table III and 95.20% ASR under defenses in Table IV are presented without uncertainty, so the central claim that STAG 'reaches at least 92.40% ASR in every setting' is a claim about unreported point estimates.
more of objection 2
Please add run-level variance (standard deviation or confidence interval) for the main results in Tables III and IV and for the ablation, trigger-size, and poison-rate curves.
The paper says, at Sec. III-B and Sec. V-A
The review did not quote this passage.
Pith says: Objection 3 of 4 · major
There is a mismatch between the threat model and the reported implementation. The threat model states that the attacker releases a frozen text encoder wrapped with a learnable soft prompt e_p and that the victim uses e_p as its text-side encoder; the implementation details, however, mention only 'frozen SBERT' for node texts and do not state that the victim uses the soft prompt.
more of objection 3
The fixed trigger phrase r and its insertion position are also never defined. Because the coordinated cross-modal mechanism in Eq. (7) depends on e_p being applied to all text (clean and triggered) during victim training, the experimental setup must explicitly confirm that e_p is part of the victim's text encoder. Please clarify this and specify r and its insertion rule.
The paper says, at Sec. V-D, Fig. 3, and Sec. V-B, Table IV
The review did not quote this passage.
Pith says: Objection 4 of 4 · major
The ablation study in Fig. 3 reports only ASR, without numeric values or error bars, and the conclusion that the graph-side objective is 'especially critical' relies on visual inspection. Additionally, Table IV aggregates defense results over the three victim GFMs and only two datasets, so the per-model behavior under defenses is not reported.
more of objection 4
Please provide a numeric table with ASR and ACC (with run-level variance) for STAG/G, STAG/T, STAG/C, and full STAG on all datasets used in the ablation, and provide per-victim breakdowns for the defense experiments.
4 minor objections
The paper says, at Table III
Pith says: minor objection 1 of 4
The 'Clean Graph' column header is confusing because the column contains clean accuracy only, not the 'ASR|ACC' format used for the other columns; consider renaming it 'Clean ACC'.
The paper says, at Sec. V-C
Pith says: minor objection 2 of 4
In the coordination analysis, the definitions of s_t, s_y, and Delta_gap should state explicitly that e(y_i) is the text anchor of the node's true class and that s_t and s_y are computed on the same set of attacked test nodes; the current prose is informal.
show 2 more
The paper says, at Algorithm 1 and Sec. V-A
Pith says: minor objection 3 of 4
Algorithm 1 does not specify the values of the learning rates eta_sigma, eta_s, eta_g, eta_p, the inner-loop count M, the outer-loop count N, or the loss weights lambda_c1 and lambda_c2; even with code available, the paper should report these hyperparameters for reproducibility.
The paper says, at Sec. V-B
Pith says: minor objection 4 of 4
The defense implementations are described in one line each (e.g., 'Prune removes edges with cosine similarity below 0.4'); please specify whether these values were tuned on clean data and how the defenses were applied to triggered subgraphs, since the reported 95.20% ASR after defenses depends on these choices.
What would settle it
Re-run the Table III Cora/GraphCLIP configuration with victim training losses L = L_align + lambda * CE (supervised cross-entropy on the same poisoned nodes with clean labels) for lambda in {0, 0.1, 1.0}, and separately with L_align replaced by a standard batch InfoNCE loss over graph-text pairs with in-batch negatives. Keep STAG's trigger generation, soft prompt, and poison rate exactly as in the paper, and report ASR and ACC for each setting. If ASR drops materially below 92.40% under any of these victim objectives, then Eq. (2) is not a faithful model of victim training and the headline transferability claim is not established; if ASR remains high, the concern is resolved.
from the skeptic's reading
How the review went
4 readings by deepseek-v4-flash · 27 Aug 2026
- Reader holds up, with conditions
- Skeptic agrees
- Editor wrote the verdict above
- Referee major revision: 4 major objections, 4 minor
Not run on this paper: the simulated authors' defence.
Pith did not check this review's objections against the paper.
The review in full
The review in brief, machine-written
Short version: this is a legitimate new attack surface—coordinating graph-side and text-side triggers through the graph-language alignment interface—and the paper demonstrates the mechanics cleanly. But the experiments may be validating the attack against a simplified training loss rather than actual GFM training, and the claims outrun the evidence.
The core idea is good: instead of poisoning one modality, STAG jointly optimizes a trigger subgraph and a soft prompt so both pull toward the same target-class text region. The equations are clear, and the embedding-closure analysis in Fig. 2 is a convincing demonstration of why single-modal attacks fail. The stealthiness work—realizing trigger nodes as readable text via candidate retrieval and matching degree statistics—is a thoughtful response to the TAG setting. Code is out, which helps.
The problems are in the experimental validation. Most importantly, the paper never states the victim training objective. The attack is optimized against a lower-level surrogate trained with the same alignment loss L_align in Eq. (2) that is used to abstract GFM training. If the victims in Sec. V were also trained with that exact loss—or a close variant—then the high ASR might just mean the attack matches the training loss, not that it transfers to a real GFM trained with instruction tuning, in-batch contrastive negatives, or an auxiliary classification head. The stress-test note has it right: this is the load-bearing assumption, and it isn't defended. Adding experiments with victims trained under their published objectives (e.g., actual GraphCLIP with hard negatives, or GraphGPT with instruction tuning) would settle it.
Second, the two closest prior attacks, GFM-BA and DTGBA, are discussed but not included as baselines. Without them, the novelty comparison is incomplete. Third, no error bars are reported despite averaging over five runs. Fourth, the text realization step depends on Claude Haiku 4.5, so the exact trigger texts are not reproducible without specifying the prompt template.
These are fixable. The attack idea is worth taking seriously, and the paper deserves a real referee. My recommendation: send it out, but the reviewers should require the victim-training-objective experiments, the missing baselines, and error bars before acceptance.
The strongest objection
Eq. (2) is not only an analytical abstraction; in the experiments it appears to be the actual training objective used for the three victim GFMs. The surrogate lower-level objective in Eq. (5) and in the constraint of Eq. (13) has the same functional form, with poisoned nodes pulled toward the target-class centroid c_t. Thus STAG's trigger generator and soft prompt are optimized against essentially the same loss that the victim is then trained with. The paper does not report the victim training objective for GraphGPT, GraphCLIP, or G2P2, and does not show that any of these victims was trained with its published objective (instruction tuning, contrastive loss with in-batch negatives, or graph-grounded prompting) rather than the simplified L_align. If a real victim objective includes a supervised classification term, hard-negative contrastive terms, or a text encoder that is not frozen, the poisoned graph-text association can be overwritten or simply never learned. In that case the claimed at-least-92.40% ASR across all datasets and victim GFMs could be a consequence of matching training losses rather than a property of actual GFM training. The central claim therefore rests on the unverified assumption that Eq. (2) is the dominant and faithful description of victim GFM training.
The reader's weakest assumption is that victim GFM training is faithfully captured by Eq. (2). My reading sharpens this into a concrete experimental issue: the paper's own attack pipeline trains the surrogate with a lower-level objective of the same form as Eq. (2), and the reported victim GFM results are not accompanied by any specification of the victim training loss, so there is no evidence that the victims were trained differently from the surrogate. This matters because the entire mechanism, coordinating the graph trigger and text prompt so that both move toward the target-class text region, only transfers if the victim's optimization is dominated by graph-text similarity to the corresponding text. Real GFM pipelines use additional or different terms, such as supervised classification losses, contrastive negatives, or instruction-following objectives. If those terms are present, the poisoned alignment can be suppressed. This is a load-bearing concern rather than a style complaint: it directly threatens the empirical claim of at least 92.40% ASR across three victim GFMs. I nonetheless keep the verdict unchanged from the reader's CONDITIONAL because the paper provides a code release, a plausible threat model, and substantial experiments; the concern is addressable by a concrete re-training test under more faithful victim objectives. The test I propose would settle the issue without requiring access to official GFM checkpoints: it can be run with the paper's own code by changing only the victim training loss. I agree with the reader's identification of the same underlying weakness.
The referee's report
If the reported numbers are reproducible and the victim models are trained with their published objectives, the paper makes a useful contribution: it identifies a concrete vulnerability of the graph-language alignment interface, demonstrates why single-modal graph or text triggers fail, and proposes a coordinated cross-modal attack with two concrete stealth mechanisms. The manuscript is technically detailed, ships code, and provides falsifiable empirical claims together with ablation and defense evaluations. The main caveat is that the experimental validation may be confounded by the victim training objective: the attack's surrogate losses are built on the same simplified alignment loss used to abstract GFM training, and the paper does not disclose the actual victim training loss in the experiments. This issue needs to be resolved before the central empirical claim is accepted.
Pith's reading of the paper (a machine's summary, not the authors')
The paper is trying to establish that graph foundation models on text-attributed graphs are backdoor-vulnerable at their graph-language alignment interface, rather than only on the graph side or the text side. It argues that single-modality triggers fail because clean text pulls poisoned graph representations back toward the benign semantic region, while text-only triggers never move the graph embedding that is actually scored. STAG is a trojan framework that jointly optimizes a graph-trigger generator and a text-side soft prompt so trigger-attached graphs and triggered text move toward the same target-class text region. It also makes triggers hard to spot by rendering trigger-node attributes as human-readable candidate text and by regularizing the trigger-attached subgraph's degree statistics. If the paper is right, poisoning an upstream text encoder or public text-attributed graph can implant a persistent, transferable misclassification in downstream graph foundation models without degrading clean accuracy.
What carries the argument. The load-bearing object is the shared graph-language alignment interface, abstracted as an objective that maximizes similarity between a graph encoder's embedding of a node's K-hop subgraph and a text encoder's embedding of the node's text. STAG's machinery consists of a graph-trigger generator, an MLP that maps the node's text embedding into the feature matrix and adjacency matrix of a trigger subgraph; a text-side soft prompt prepended to the frozen text encoder; a surrogate graph encoder trained in place of the inaccessible victim graph encoder; and a bi-level optimization that alternates projected-gradient ascent on an adversarial perturbation, descent on the surrogate, descent on the trigger generator, and descent on the soft prompt. The trigger feature is kept near the target-class text centroid under a bounded perturbation, then replaced by the closest human-readable candidate text retrieved from an LLM-generated candidate pool, and the trigger subgraph is regularized to keep the mean and variance of its degree distribution close to the original subgraph.
Core claim. The central claim is that a backdoor against graph foundation models on text-attributed graphs should be planted in the shared graph-language alignment objective rather than in either modality alone. The paper abstracts victim training as maximizing similarity between graph embeddings and text embeddings, and designs STAG to solve a bi-level min-max problem in which a learned trigger generator produces a trigger subgraph for each poisoned node while a learnable soft prompt, prepended to the frozen text encoder, shifts triggered text embeddings in the same direction. The two attack signals are coordinated through a target-class text centroid: the graph-side objective pulls trigger-attached subgraphs toward that centroid, the text-side objective aligns triggered text with those subgraphs, and a similarity function that combines cosine similarity with a Euclidean penalty makes the objective more robust to an unknown downstream prediction head. Empirically, STAG reports attack success rates of at least 92.40% across all tested datasets and victim models, with clean accuracy close to the clean baseline, while single-side baselines stay below roughly 42% attack success and often damage clean accuracy.
The premise it rests on. The attack assumes that the victim's graph foundation model is trained essentially by maximizing similarity between graph embeddings and text embeddings, so the alignment objective in Eq. (2) is the whole training signal that imprints the trigger-target association.
If the paper is right (Pith's inferences, not the authors')
Single-modality backdoor attacks adapted from the graph side or text side are not sufficient against graph foundation models on text-attributed graphs, so future attack and defense work should treat the alignment interface as the target.
Because STAG reports at least 92.40% attack success while keeping clean accuracy near the clean baseline, a backdoor can survive validation based on clean accuracy alone.
Readable trigger text and degree-matched trigger subgraphs keep the attack effective under feature-based, outlier-based, and structural defenses, meaning text-attributed-graph-specific stealth is achievable without sacrificing attack strength.
The attack works under a gray-box supply-chain assumption where the attacker controls only the public graph and a frozen text encoder, so upstream data or encoder compromise is the threat scenario that needs monitoring.
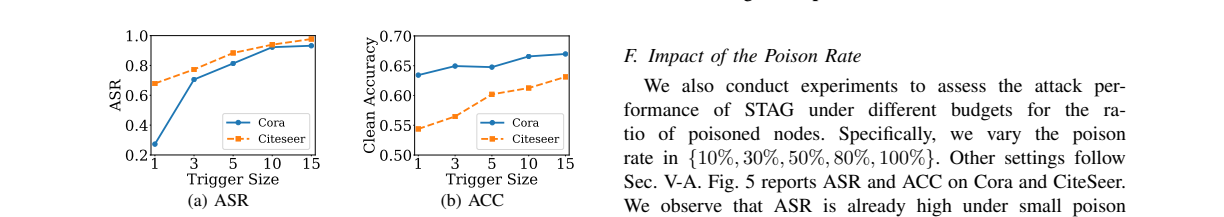
The graph-side objective is the more critical component: ablations show removing it causes the largest drop in attack success, while removing either concealment loss mainly hurts robustness against defenses.
Implicit consequence: the same upstream compromise that enables STAG could propagate to many downstream graph foundation models that reuse the poisoned graph or text encoder, so a single poisoned encoder release may backdoor models the attacker never directly trained against.
A natural extension the paper does not test is whether an alignment-level defense that measures how close trigger-attached graph embeddings are to target-class text centroids would detect STAG, since the attack's own closure-rate diagnostic shows an unusually large fraction of poisoned embeddings entering that region.
The mechanism should carry over to graph retrieval-augmented generation pipelines, where poisoned alignment could steer which subgraphs get retrieved and fed to an LLM; the authors point to this direction as open, and it would be testable by attaching the same trigger subgraph and prompt to retrieval queries.
An untested robustness question is whether STAG survives a victim that fine-tunes the text encoder or adds classification losses, since the paper's abstraction of victim training as pure graph-text alignment is what makes the coordinated poisoning transfer.
Check this review
Pith stored no record of this review's passes and took no fingerprint of it. Reviews made by code from 13 Nov 2026 on carry both.
How often reviews like this one are right
Reviews like this one: written by deepseek-v4-flash, where what was read was not recorded.
How often objections from reviews like this one are right: not yet measured
Reviews by people
This review was written by a machine. No person has reviewed this paper on Pith yet. A scientist listed on Pith can review it for a fee, and their review is published here whatever it concludes.
The paper
Abstract
Graph Foundation Models (GFMs) on text-attributed graphs (TAGs) align graph representations with language semantics to support transferable graph learning. Despite these advantages, the backdoor vulnerability of GFMs on TAGs remains insufficiently understood, especially under graph-language alignment, where graph and text representations are trained to constrain each other in a shared semantic space. Existing backdoor attacks mainly target either the graph side or the text side, treating the two modalities independently. This makes direct adaptation ineffective: graph-only triggers can be constrained by clean text semantics, while text-only triggers alter the language view but do not directly shift the graph representation being aligned and scored. TAGs also impose a stealth challenge because triggers are exposed as both node text and local graph structure, making incoherent trigger attributes or anomalous subgraphs easy to inspect or filter. In this paper, we propose STAG, a stealthy trojan attack framework designed for the graph-language alignment interface of GFMs on TAGs. STAG coordinates a graph-trigger generator with a text-side soft prompt so that trigger-attached graph representations and triggered text representations move toward the same target-class text region. To address TAG-specific stealthiness, STAG realizes trigger nodes as readable text through candidate retrieval and regularizes the trigger-attached subgraph so that its local structure remains close to the original subgraph. Extensive experiments on multiple TAG datasets and representative GFMs demonstrate the effectiveness and stealthiness of STAG. Our code is available at https://github.com/ventr1c/STAG.
The paper's own sentences, arranged, kept beside the review and separate from it. Each label is drawn from a closed vocabulary; the number beside it is the probability the classifier gave that label. No sentence in this record was written by a model.
abstract compiled · 2026-09-23
The authors' main claim, as the classifier picked it out 0.99
“Extensive experiments on multiple TAG datasets and representative GFMs demonstrate the effectiveness and stealthiness of STAG.”
How the main claim is stated: asserted 1.00
What the abstract itself states, as probabilities: claims first 0.12 · states limitation 0.09 · human participants 0.02 · controlled comparison 0.20 · randomized assignment 0.01 · states quantitative result 0.04 · compares with prior results 0.37 · mentions code or data availability 0.99
The abstract, sentence by sentence
This table labels the abstract only (arXiv listing abstract v2). The number is the probability the classifier gave the label.
| Sentence | Role | The authors' own work | States the main conclusion | Strength |
|---|---|---|---|---|
| Graph Foundation Models (GFMs) on text-attributed graphs (TAGs) align graph representations with language semantics to support transferable graph learning. | background 1.00 | 0.05 | 0.02 | asserted 1.00 |
| Despite these advantages, the backdoor vulnerability of GFMs on TAGs remains insufficiently understood, especially under graph-language alignment, where graph and text representations are trained to constrain each other in a shared semantic space. | gap 1.00 | 0.06 | 0.03 | asserted 0.97 |
| Existing backdoor attacks mainly target either the graph side or the text side, treating the two modalities independently. | gap 0.53 | 0.04 | 0.02 | asserted 1.00 |
| This makes direct adaptation ineffective: graph-only triggers can be constrained by clean text semantics, while text-only triggers alter the language view but do not directly shift the graph representation being aligned and scored. | gap 0.54 | 0.12 | 0.03 | asserted 1.00 |
| TAGs also impose a stealth challenge because triggers are exposed as both node text and local graph structure, making incoherent trigger attributes or anomalous subgraphs easy to inspect or filter. | background 0.76 | 0.09 | 0.02 | asserted 0.97 |
| In this paper, we propose STAG, a stealthy trojan attack framework designed for the graph-language alignment interface of GFMs on TAGs. | contribution 0.99 | 0.86 | 0.15 | asserted 0.99 |
| STAG coordinates a graph-trigger generator with a text-side soft prompt so that trigger-attached graph representations and triggered text representations move toward the same target-class text region. | method 0.96 | 0.84 | 0.14 | asserted 1.00 |
| To address TAG-specific stealthiness, STAG realizes trigger nodes as readable text through candidate retrieval and regularizes the trigger-attached subgraph so that its local structure remains close to the original subgraph. | method 0.96 | 0.91 | 0.06 | asserted 1.00 |
| Extensive experiments on multiple TAG datasets and representative GFMs demonstrate the effectiveness and stealthiness of STAG. | result 0.98 | 0.94 | 0.65 | asserted 1.00 |
| Our code is available at https://github.com/ventr1c/STAG. | contribution 0.75 | 0.43 | 0.02 | asserted 0.91 |
What kind of paper the classifier reports this is: method or tool 1.00 · evidence from observation or experiment 0.99
What was examined, and what was not
Sources read
- arXiv listing abstract v2
Not examined
- full text
- figures and tables
- references and citing sentences
- relations to other papers
Levels run
- P abstract
Not run
- S sections
- T body sentences
- C citations
- R cross-paper relations
How the labels were made
Compiled by classifier-1.13.0 via TypeSafe API, question bank abstract-p1-20260923, 2026-09-23: 1 request, 7,642 input tokens.
Every quoted sentence on this record is the authors'. Every label is from Pith's closed vocabulary, with the probability shown beside it. This record as JSON
Figures (4)


Figures are the authors', reproduced from the paper.
References (50)
- [1] J. Liu, C. Yang, Z. Lu, J. Chen, Y . Li, M. Zhang, T. Bai, Y . Fang, L. Sun, P. S. Yuet al., “Graph foundation models: Concepts, opportunities and challenges,”TPAMI, 2025 on Pith
- [2] M. Lin, Z. Zhang, H. Lu, H. Liu, X. Tang, Q. He, X. Zhang, and S. Wang, “Memma: Coordinating the memory cycle through multi-agent reasoning and in-situ self-evolution,”arXiv preprint arXiv:2603.18718, 2026 on PithPith's reviewarXiv
- [3] Z. Weng, A. Antoniades, D. Nathani, Z. Zhang, X. Pu, and X. E. Wang, “Group-evolving agents: Open-ended self-improvement via experience sharing,”arXiv preprint arXiv:2602.04837, 2026 on PitharXiv
- [4] W. Hu, M. Fey, M. Zitnik, Y . Dong, H. Ren, B. Liu, M. Catasta, and J. Leskovec, “Open graph benchmark: Datasets for machine learning on graphs,”NeurIPS, vol. 33, pp. 22 118–22 133, 2020 on Pith
- [5] P. Mernyei and C. Cangea, “Wiki-cs: A wikipedia-based benchmark for graph neural networks,”arXiv preprint arXiv:2007.02901, 2020 on PithPith's reviewarXiv
- [6] S. Wu, F. Sun, W. Zhang, X. Xie, and B. Cui, “Graph neural networks in recommender systems: a survey,”ACM Computing Surveys, vol. 55, no. 5, pp. 1–37, 2022 on Pith
- [7] B. Li and S. Nabavi, “A multimodal graph neural network framework for cancer molecular subtype classification,”BMC bioinformatics, vol. 25, no. 1, p. 27, 2024 on Pith
- [8] D. Wang, J. Lin, P. Cui, Q. Jia, Z. Wang, Y . Fang, Q. Yu, J. Zhou, S. Yang, and Y . Qi, “A semi-supervised graph attentive network for financial fraud detection,” inICDM, 2019, pp. 598–607 on Pith
- [9] S. Xiang, D. Cheng, C. Shang, Y . Zhang, and Y . Liang, “Temporal and heterogeneous graph neural network for financial time series prediction,” inCIKM, 2022, pp. 3584–3593 on Pith
- [10] T. N. Kipf and M. Welling, “Semi-supervised classification with graph convolutional networks,” inICLR, 2017 on Pith
- [11] J. Devlin, M.-W. Chang, K. Lee, and K. Toutanova, “Bert: Pre-training of deep bidirectional transformers for language understanding,” inNAACL, 2019, pp. 4171–4186 on Pith
- [12] T. Brown, B. Mann, N. Ryder, M. Subbiah, J. D. Kaplan, P. Dhariwal, A. Neelakantan, P. Shyam, G. Sastry, A. Askellet al., “Language models are few-shot learners,”NeurIPS, vol. 33, pp. 1877–1901, 2020 on Pith
- [13] M. Lin, J. Wu, Z. Wang, Z. Shi, Y . Sang, B. He, Z. Liu, T. Wei, Z. Wu, Z. Zhanget al., “Harness updating is not harness benefit: Disentangling evolution capabilities in self-evolving llm agents,”arXiv preprint arXiv:2605.30621, 2026 on PithPith's reviewarXiv
- [14] T. Chen, K. Huang, and K. Sun, “A benchmark on llm-based power flow computation: Do more structured prompts help?”arXiv preprint arXiv:2605.18642, 2026 on PithPith's reviewarXiv
- [15] Z. Hu, Y . Li, Z. Chen, J. Wang, H. Liu, K. Lee, and K. Ding, “Let’s ask gnn: Empowering large language model for graph in-context learning,” arXiv preprint arXiv:2410.07074, 2024 on PithPith's reviewarXiv
- [16] Z. Chai, T. Zhang, L. Wu, K. Han, X. Hu, X. Huang, and Y . Yang, “Graphllm: Boosting graph reasoning ability of large language model,” arXiv preprint arXiv:2310.05845, 2023 on PithPith's reviewarXiv
- [17] J. Tang, Y . Yang, W. Wei, L. Shi, L. Su, S. Cheng, D. Yin, and C. Huang, “Graphgpt: Graph instruction tuning for large language models,” in SIGIR, 2024, pp. 491–500 on Pith
- [18] Z. Wen and Y . Fang, “Augmenting low-resource text classification with graph-grounded pre-training and prompting,” inSIGIR, 2023 on Pith
- [19] Y . Zhu, H. Shi, X. Wang, Y . Liu, Y . Wang, B. Peng, C. Hong, and S. Tang, “Graphclip: Enhancing transferability in graph foundation models for text-attributed graphs,” inWWW, 2025, pp. 2183–2197 on Pith
- [20] D. Wang, Y . Zuo, F. Li, and J. Wu, “Llms as zero-shot graph learners: Alignment of gnn representations with llm token embeddings,”NeurIPS, vol. 37, pp. 5950–5973, 2024 on Pith
show 30 more
- [21] H. Luo, F. Wang, W. Zhang, X. Zhang, Z. Zhang, T. Zhao, M. Lin, J. Zhang, H. Liu, X. Tanget al., “Graph-assisted large language models: A perspective on mitigating intrinsic limitations,” inFindings of ACL, 2026, pp. 18 936–18 955 on Pith
- [22] E. Dai, M. Lin, X. Zhang, and S. Wang, “Unnoticeable backdoor attacks on graph neural networks,” inWWW, 2023, pp. 2263–2273 on Pith
- [23] M. Lin, Z. Zhang, E. Dai, Z. Wu, Y . Wang, X. Zhang, and S. Wang, “Are you using reliable graph prompts? trojan prompt attacks on graph neural networks,” inKDD, 2025, pp. 1729–1740 on Pith
- [24] H. Yao, J. Lou, and Z. Qin, “Poisonprompt: Backdoor attack on prompt- based large language models,” inICASSP. IEEE, 2024, pp. 7745–7749 on Pith
- [25] Z. Hou, M. Lin, M. Torkamani, S. Wang, and X. Liu, “Adversarial robustness in graph neural networks: Recent advances and new frontier,” inDSAA. IEEE, 2024, pp. 1–2 on Pith
- [26] N. Gu, P. Fu, X. Liu, Z. Liu, Z. Lin, and W. Wang, “A gradient control method for backdoor attacks on parameter-efficient tuning,” inACL, 2023 on Pith
- [27] Z. Zhang, M. Lin, E. Dai, and S. Wang, “Rethinking graph backdoor attacks: A distribution-preserving perspective,” inKDD, 2024 on Pith
- [28] Z. Zhang, J. Jia, B. Wang, and N. Z. Gong, “Backdoor attacks to graph neural networks,” inProceedings of the 26th ACM Symposium on Access Control Models and Technologies, 2021, pp. 15–26 on Pith
- [29] X. Lyu, Y . Han, W. Wang, H. Qian, I. Tsang, and X. Zhang, “Cross- context backdoor attacks against graph prompt learning,” inKDD, 2024 on Pith
- [30] Z. Xi, R. Pang, S. Ji, and T. Wang, “Graph backdoor,” inUSENIX Security, 2021, pp. 1523–1540 on Pith
- [31] M. Zhang, M. Sun, P. Wang, S. Fan, Y . Mo, X. Xu, H. Liu, C. Yang, and C. Shi, “Graphtranslator: Aligning graph model to large language model for open-ended tasks,” inWWW, 2024, pp. 1003–1014 on Pith
- [32] E. Chien, W.-C. Chang, C.-J. Hsieh, H.-F. Yu, J. Zhang, O. Milenkovic, and I. S. Dhillon, “Node feature extraction by self-supervised multi-scale neighborhood prediction,”arXiv preprint arXiv:2111.00064, 2021 on PithPith's reviewarXiv
- [33] Y . Qiao, X. Ao, Y . Liu, J. Xu, X. Sun, and Q. He, “Login: A large language model consulted graph neural network training framework,” in WSDM, 2025, pp. 232–241 on Pith
- [34] H. Zhang, J. Chen, L. Lin, J. Jia, and D. Wu, “Graph contrastive backdoor attacks,” inICML. PMLR, 2023, pp. 40 888–40 910 on Pith
- [35] X. Lyu, Y . Han, W. Wang, H. Qian, I. Tsang, and X. Zhang, “Cross- context backdoor attacks against graph prompt learning,” inKDD, 2024, pp. 2094–2105 on Pith
- [36] J. Luo, Q. Sun, L. Lyu, Z. Zhang, H. Yuan, X. Fu, and J. Li, “Towards effective, stealthy, and persistent backdoor attacks targeting graph foundation models,”arXiv preprint arXiv:2511.17982, 2025 on PitharXiv
- [37] X. Xue, Y . Lai, C. Huang, Y . Zhu, G. Li, X. Zhang, and K. Zhou, “Stealthy dual-trigger backdoors: Attacking prompt tuning in lm- empowered graph foundation models,”arXiv preprint arXiv:2510.14470, 2025 on PitharXiv
- [38] B. Lester, R. Al-Rfou, and N. Constant, “The power of scale for parameter-efficient prompt tuning,” inEMNLP, 2021, pp. 3045–3059 on Pith
- [39] X. L. Li and P. Liang, “Prefix-tuning: Optimizing continuous prompts for generation,” inACL, 2021, pp. 4582–4597 on Pith
- [40] N. Reimers and I. Gurevych, “Sentence-bert: Sentence embeddings using siamese bert-networks,” inEMNLP, 2019, pp. 3982–3992 on Pith
- [41] S. Yun, M. Jeong, R. Kim, J. Kang, and H. J. Kim, “Graph transformer networks,”NeurIPS, vol. 32, 2019 on Pith
- [42] T. Gao, X. Yao, and D. Chen, “Simcse: Simple contrastive learning of sentence embeddings,” inEMNLP, 2021, pp. 6894–6910 on Pith
- [43] Y . Wang, Y . Zhu, W. Zhang, Y . Zhuang, Y . Li, and S. Tang, “Bridging local details and global context in text-attributed graphs,” inEMNLP, 2024, pp. 14 830–14 841 on Pith
- [44] P. Sen, G. Namata, M. Bilgic, L. Getoor, B. Galligher, and T. Eliassi- Rad, “Collective classification in network data,”AI magazine, vol. 29, no. 3, pp. 93–93, 2008 on Pith
- [45] S. Liang, M. Zhu, A. Liu, B. Wu, X. Cao, and E.-C. Chang, “Badclip: Dual-embedding guided backdoor attack on multimodal contrastive learning,” inCVPR, 2024, pp. 24 645–24 654 on Pith
- [46] S. Bandyopadhyay, N. Lokesh, and M. N. Murty, “Outlier aware network embedding for attributed networks,” inAAAI, vol. 33, no. 01, 2019, pp. 12–19 on Pith
- [47] K. Ding, J. Li, R. Bhanushali, and H. Liu, “Deep anomaly detection on attributed networks,” inSDM. SIAM, 2019, pp. 594–602 on Pith
- [48] A. Radford, J. Wu, R. Child, D. Luan, D. Amodei, I. Sutskeveret al., “Language models are unsupervised multitask learners,”OpenAI blog, vol. 1, no. 8, p. 9, 2019 on Pith
- [49] F. Qi, Y . Chen, M. Li, Y . Yao, Z. Liu, and M. Sun, “ONION: A simple and effective defense against textual backdoor attacks,” inEMNLP, 2021 on Pith
- [50] F. J. Massey Jr, “The kolmogorov-smirnov test for goodness of fit,” Journal of the American statistical Association, vol. 46, no. 253, pp. 68–78, 1951 on Pith
Cited by 1 Pith paper
Reviewed papers on Pith that cite this one. The full citation record
How the literature uses it
What this paper does with the arXiv papers it cites
What it cites · 3 sentences without a confident label
Cites as background 9 papers
-
GFM-BA [ref] anchors triggers to label-free prototype embeddings, and DTGBA [ref] attacks prompt-tuned LM-empowered GFMs with text-level and structure-level triggers.
2510.14470 · Related Work · 0.90
-
GFM-BA [ref] anchors triggers to label-free prototype embeddings, and DTGBA [ref] attacks prompt-tuned LM-empowered GFMs with text-level and structure-level triggers.
2511.17982 · Related Work · 0.90
-
To exploit both structural connectivity and language semantics, recent GFMs couple a graph encoder [ref] with a language model [ref] in a shared embedding space, enabling zero- and few-shot prediction and instruction-style graph reasoning [ref] .
Let's Ask GNN: Empowering Large Language Model for Graph In-Context Learning · Introduction · 0.84
Challenges and discussion
Disagree with the review, or know something it missed? Leave a comment, or challenge this review formally: a challenge becomes a permanent entry in this paper's record, and its decision is published here.
Come back by email
A short list of the week's newly reviewed papers. Nothing is sent until you confirm from your inbox, and every email has a link that stops it. No account.
No comments yet.
Sign in to comment