REVIEW 3 major objections 5 minor
Reading and Steering Representations of Materials-Science Mechanisms in an Open-Weight Language Model
T0 review · 3 major / 5 minor · reviewed 2026-08-01 · deepseek-v4-flash
Pith's one-line read The paper claims materials-science mechanisms in a language model are best detected as controlled changes between internal states, and that these state changes order direct, neutral, and inverse constitutive laws nearly perfectly.
desk verdict A careful, honest interpretability study whose headline 60-law result is likely confounded by the answer-word axis; the graph identifiability audit is the real contribution. read the letter →
The pith
A machine-rendered reading of the paper's core claim, the machinery that carries it, and where it could break.
The reading
What carries the argument
The main positive result is built on a matched-reversal state contrast. At layer 34, a unit direction d = (mu+ - mu-)/||mu+ - mu-|| is fitted on development-law centroids; for each law and cell, the projected score of the numerical-decrease prompt is subtracted from the numerical-increase prompt, holding equation surface, material wording, endpoint values, and answer order fixed, with ten calibration-neutral laws defining the empirical zero and scale. This converts the relation 'response sign = law sign × change sign' into a measurable hidden-state displacement. The negative result's machinery is the algebraic identity y = sx: within one mechanism family, same/different physical outcome is e
What would settle it
Rerun the 60-law matched-reversal benchmark with a leave-one-family-out direction: fit the layer-34 centroid on 15 of the development-law families and test on the held-out family plus the 60-law cohort. If direct-versus-inverse AUC falls far below 0.935 or the Spearman rho drops substantially, the transferability claim fails. A second check: swap the ten calibration-neutral laws with the ten validation-neutral laws; if the neutral scale shifts enough that the 39/40 classification degrades, the claim of a stable empirical zero fails.
Extended reading notes
Core claim
The paper's central claim is that the physical abstraction of monotonic constitutive orientation—whether a stated increase in an input quantity raises or lowers the response under a supplied law—is carried by controlled transformations between hidden states, not by the absolute geometry of those states. Using a frozen direction fitted on 16 development laws and a neutral class calibrated on 10 independent laws, the author compares otherwise identical prompts that differ only in the sign of the numerical change. Across 60 laws, the resulting state contrasts order 20 inverse, 20 neutral, and 20 direct relations with direct-versus-inverse AUC 1.000, validation-neutral-versus-inverse AUC 0.935,
Load-bearing premise
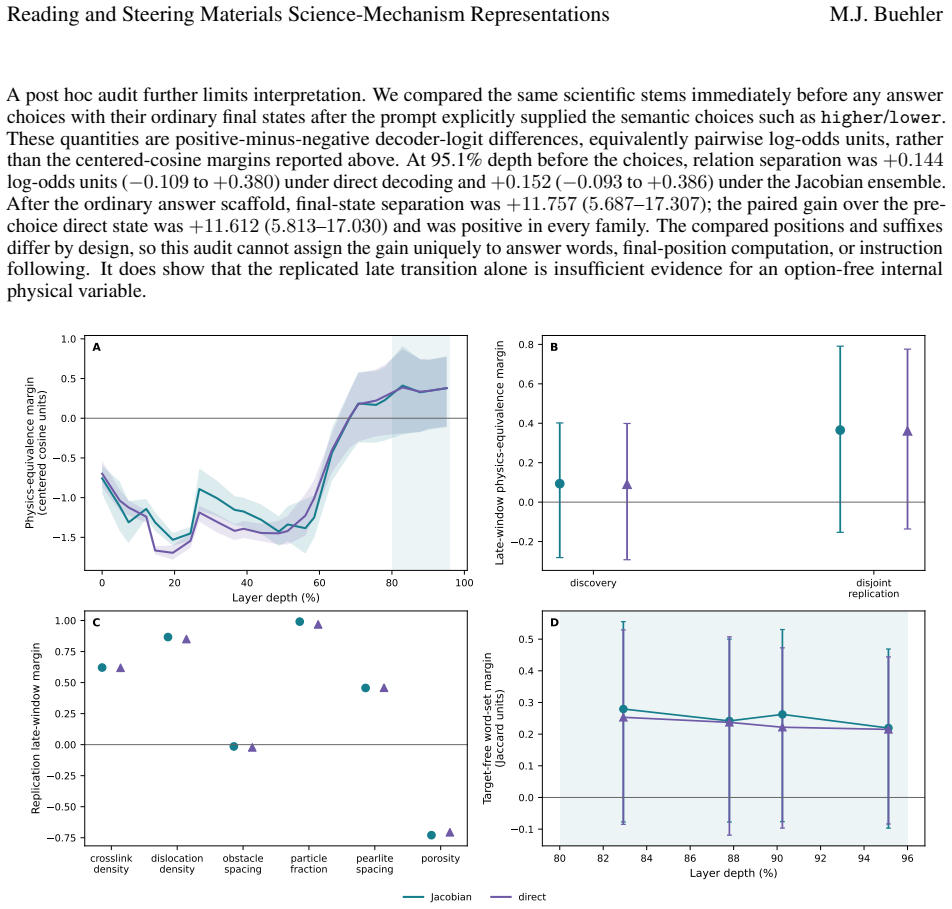
The main result rests on the assumption that a single internal direction fitted on 16 development laws, plus an empirical zero calibrated on 10 neutral laws, carries over to 60 new laws without being refit; if those development laws are not representative of the 13 domains, the measured ordering could be renormalized or even inverted.
Editorial extensions
If this is right
- If the 60-law result holds, controlled state differences are a stronger evidence type than absolute-state similarity for whether a model tracks a physical relation.
- Interpretability studies should run an aliasing audit before claiming a similarity graph encodes physics; in this design, 'same physical outcome' was exactly 'same numerical direction' within a family.
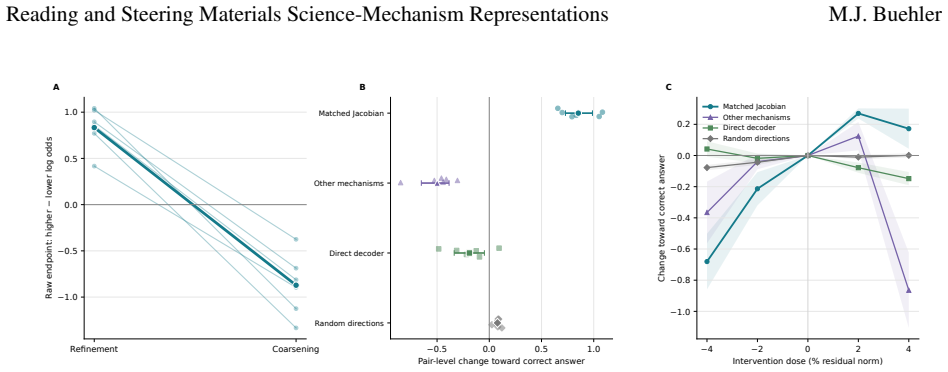
- Causal steering is real but format-limited: the same grain-size direction reverses answers correctly for refinement and coarsening in one answer vocabulary, yet fails when answer words or physical regime change.
- A practical test for physics representation in LLMs can be built from matched counterfactual prompts with a neutral class as an empirical zero, without requiring the model to output correct inverse-law text, which lagged behind the hidden-state signal.
- The result supports exploring representation-aware training rewards that penalize lexical shortcuts and reward counterfactual consistency, while keeping the reward lens separate from the evaluation lens.
Reading between the lines
- I would expect the matched-reversal contrast to also order laws in other scientific domains, since the y = sx structure is generic, but the specific layer and direction would likely need refitting per domain.
- The single sign error—the classical nucleation-barrier relation versus undercooling—suggests a testable boundary: monotonic-sign internalization may fail for laws with genuinely non-monotonic behavior, and a future benchmark could deliberately include such laws.
- The answer-scaffold audit implies that readability of a scientific word after answer options are shown can be misleading; reward or evaluation readouts should be taken before choices appear.
- The contrast between near-perfect internal ordering and only 53.8% correct inverse-law output hints that failure to verbalize a law does not mean the model lacks it—an inference the paper supports but does not fully explore.
Signed reviews
Editorial analysis
A structured set of objections, weighed in public.
Referee Report
Summary. The paper investigates whether materials-science mechanism information in an open-weight language model (google/gemma-4-E4B-it) is (i) readable in hidden states, (ii) carried by transformations between states, and (iii) causally usable for engineering answers. It combines direct and Jacobian vocabulary readouts, target-free decoding, state-space geometry, graph analyses, a 60-law neutral-anchored matched-reversal benchmark, and causal interventions. The main positive claims are that controlled state transformations order direct, neutral, and inverse constitutive relations nearly perfectly (AUC 1.000 direct vs. inverse, Spearman ρ = 0.910, 39/40 directional laws), and that one frozen grain-size direction steers answers in a relation-appropriate way in a prospectively confirmed cohort, while transfer to other answer vocabularies and regimes fails. The paper also reports a series of negative or limiting results: the broad 24-triplet physical-equivalence endpoint failed, the 80–96% late-window primary failed, the graph's physical polarity is not identifiable, and transfer cohorts fail. The authors are unusually explicit about preregistration, discovery-versus-replication chronology, and limitations.
Significance. If the neutral-anchored claim is sustained, the paper is a valuable methodological contribution: it demonstrates a framework for separating readable concepts, relational transformations, and causal use in LLM representations, and it provides a clear identifiability proof (Eq. 1) showing that a graph endpoint can collapse exactly to a prompt variable. The paper is also a model of scientific candor: endpoints are frozen, discovery cohorts are separated from replication cohorts, exact nulls and exhaustive partitions are used, and several high-profile hypotheses are reported as failures. The causal steering results are carefully bounded and the transfer failures are reported rather than hidden. The main unresolved risk is whether the headline 60-law result measures constitutive orientation or, more shallowly, the model's movement toward the expected answer word. That issue is central enough that the claim, as currently stated, is not yet fully established.
major comments (3)
- [§5.12, Eq. (12)–(13), Fig. 10C] The centroid direction d is fitted on positive-versus-negative physical-outcome labels in a scaffold where the physical outcome sign directly determines the model's allowed answer word (higher/lower). A direction fitted on those labels can therefore be an answer-token direction, and the matched contrast Δr may simply measure whether the hidden state moves toward the correct output word. The output-logit control reaching AUC 1.000 in Fig. 10C is consistent with this alternative reading, and §2.11.3 shows that a different direction can be answer-vocabulary specific. Word/char TF-IDF controls do not address this because they model prompt surface, not the output token. To support the constitutive-orientation interpretation, please add a control that breaks the alignment: e.g., fit d on a development set containing a balanced mix of direct and inverse laws (so positive/negative labels are not
- [§2.8, Fig. 10C and §3.2] The paper reports that exact inverse-law answer accuracy is only 53.8% while the output-logit control reaches AUC 1.000. This discrepancy needs explicit reconciliation. If the layer-34 hidden direction is essentially the same axis as the final output logits, then the claim that the hidden state is 'more stable than its conversion into the requested discrete answer' is weakened rather than supported: the hidden-state result may be an earlier manifestation of answer planning, not an independent representation of constitutive orientation. Please either quantify the correlation between r(h) and the output-logit contrast per law, or show that the ordering survives after removing the component of d that is aligned with the decoder's higher/lower direction.
- [§2.8, §5.12] The 60-law benchmark uses an explicit two-stage scaffold that instructs the model to compose the sign of the supplied equation with the sign of the numerical change. This makes the result task-elicited, as the authors acknowledge. The concern is not that task-elicitation is worthless, but that the headline phrasing 'physical abstraction of monotonic constitutive orientation' overstates what the design can show without the answer-token control above. Please either soften the abstract and conclusion claims accordingly, or provide the requested controls. The current limitation statement in §3.2 ('does not show spontaneous use...') is helpful but does not address the answer-token confound specifically.
minor comments (5)
- [§2.6] Typo: 'We find it ito be strong' should be 'We find it to be strong'.
- [§2.8] Typo: 'V ocabulary readouts' should be 'Vocabulary readouts'.
- [§4] Typo: 'addiitonal insights' should be 'additional insights'.
- [Abstract / §5.20] The phrase 'blinded identification of 9 of 10 mechanism families' should clarify that the interpreter is one automated model (gpt-5.5) with five order-randomized passes, not a panel of independent experts. The limitation is stated later, but the abstract could be more precise.
- [§5.12] The description of the output-head control and the exact-answer accuracy would benefit from a clearer statement of where the 'clean final higher-minus-lower logit difference' is measured (at the final token position? before generation?) so that the reader can see why the 53.8% inverse-law exact accuracy can coexist with AUC 1.000 on the logit contrast.
Circularity Check
No significant circularity: the core 60-law result is an out-of-sample supervised readout with a separate neutral calibration, and the paper explicitly audits the y=sx alias rather than hiding it.
full rationale
The paper's central relational claim is not circular. The layer-34 direction d=(mu+ - mu-)/||...|| is fitted only on 16 development laws and then frozen; no 60-law state or label is used to refit it. The matched contrast subtracts two prompts that are identical except for the direction of the numerical change, while equation surface, material wording, endpoint values, and answer order are held fixed. Ten neutral laws define the empirical zero and scale, and ten different neutral laws are used for validation, so the neutral class does not enter the fit. The paper also explicitly proves the exact alias y=sx for the earlier graph benchmark (Eq. 1) and reports the graph as non-identifiable, rather than presenting it as evidence of physics. The potential concern that the fitted direction could track the expected higher/lower output token rather than an abstract constitutive orientation is a real interpretive confound and is transparently acknowledged via the output-logit control reaching 1.000; but it is not a case where the prediction is equivalent to the fit by construction. The experiment could have failed (in fact the earlier exact-behavior and rearranged-formula endpoints did fail), and the direction transfers to a new 60-law cohort without refitting. Self-citations are contextual and not load-bearing for the central derivation. No circular step meeting the required quote-and-reduction standard is present.
Assumptions & free parameters
free parameters (4)
- layer-34 centroid direction d =
fitted on 16 development laws
- layer choice (layer 34) and direction midpoint m =
chosen on development/disjoint cohorts
- grain steering layer 16 and direction vector =
selected in a preliminary study on disjoint calibration conditions
- perturbation doses +/-4%, +/-2% =
chosen by protocol
assumptions (5)
- domain assumption The fixed decoder (unembedding) is a valid linear readout instrument for intermediate states.
- domain assumption The Jacobian estimator (Eq. 4) correctly approximates the average downstream transport.
- domain assumption The 16 development laws are representative of the 60-law benchmark's 13 domains.
- domain assumption Matched prompt pairs with only the numerical direction reversed isolate the physical relation change.
- standard math The graph-identifiability claim y=sx is an exact reading of the prompt manifest.
Cite this review
Pith. "Pith review of Reading and Steering Representations of Materials-Science Mechanisms in an Open-Weight Language Model." pith.science (2026). https://pith.science/paper/ZFIGRGHA
@misc{pith2026260720058,
  author       = {Pith},
  title        = {Pith review of: Reading and Steering Representations of Materials-Science Mechanisms in an Open-Weight Language Model},
  year         = {2026},
  howpublished = {\url{https://pith.science/paper/ZFIGRGHA}},
  note         = {Machine review of arXiv:2607.20058}
}
read the original abstract
Large language models can answer scientific questions, yet a correct output does not reveal whether the model represents or uses the governing physics. Here, using three open-weight Gemma 4 models (google/gemma-4-E4B-it, google/gemma-4-12B-it, google/gemma-4-31B-it) we identify three experimentally separable signatures of materials-science mechanism information: selective concept readability, relational encoding of qualitative constitutive orientation, and causal, context-dependent control of constrained engineering answers. We combine matched direct and Jacobian vocabulary readouts, option-free state geometry, a 60-law counterfactual benchmark and causal interventions. In 50 held-out materials descriptions, three independently fitted Jacobian lenses reproduced concept ranks, and target-free word sets from both readouts enabled blinded identification of 9 of 10 mechanism families. A separate 72-prompt benchmark produced mechanism-specific hidden-state neighborhoods, but an exact graph audit showed that this apparent physical organization was equally explained by numerical comparison. We therefore compared otherwise identical prompts in which only the direction of the physical input was reversed, asking whether the resulting hidden-state movement followed the supplied constitutive law. These state transformations ordered direct, physically neutral and inverse laws across 60 frozen relations and correctly oriented 39 of 40 directional laws, whereas lexical controls were near chance. Bidirectional interventions shifted answer probabilities toward or away from the physically appropriate outcome across all 12 matched cases, while counterfactual state patches transferred opposing decision signals across mechanisms and answer formats. Physical relationships were therefore more visible in controlled state changes than in absolute states alone.
Figures


Figures from the paper (13 more)






Reviewed August 1, 2026 · model on record in the stance chip above.
Discussion (0). Continue with ORCID to comment.