Computation and Language · arXiv:2609.27717 v2 · submitted 23 Sep 2026 · 23 references
SkillGym: Internalizing Human Skills into LLMs for Real-World Problem Solving
The paper says
“Human-written agent skills encode rich workflows for real-world problem solving, but are typically used as external inference-time instructions rather than internalized as reusable model capabilities.”
more of the abstract
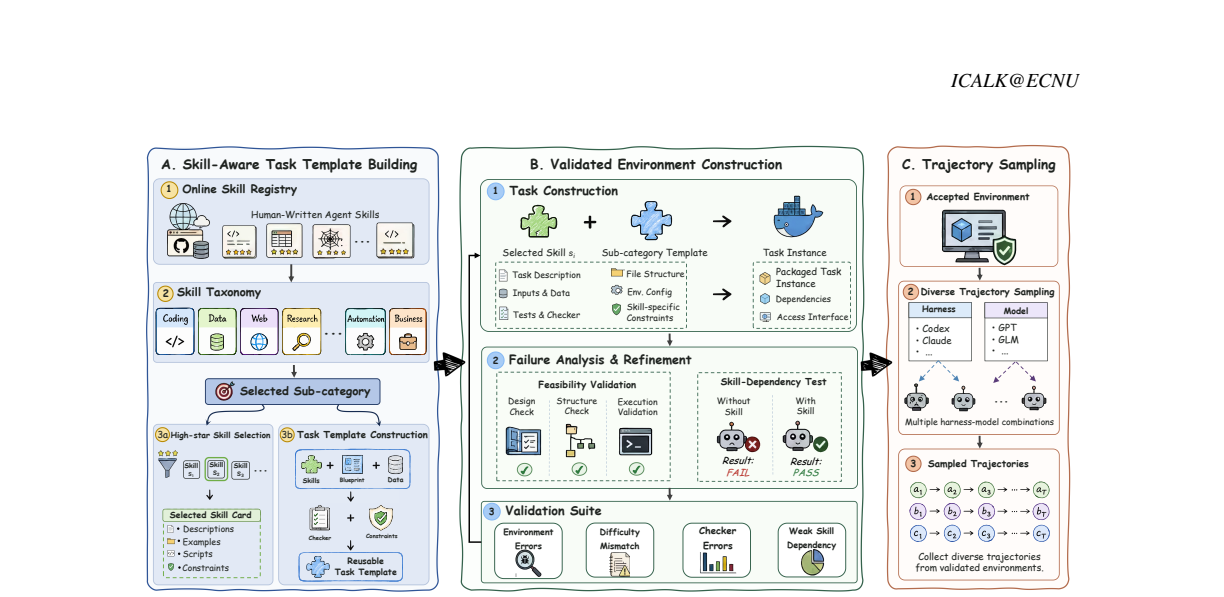
We introduce \textttSkillGym, a framework that transforms these skills into executable, verifiable training environments for large language model agents. Its skill-to-task pipeline instantiates concrete tasks, verifies outcomes with code-based checkers, and assesses empirical skill dependence through contrastive executions. We construct and release 2,756 environments across 12 categories and collect 8,364 successful trajectories from multiple models and harnesses, averaging 49 tool calls and over 60k logged text tokens. These resources support supervised fine-tuning on verified workflows and reinforcement learning with outcome-based rewards. Under Claude Code, supervised fine-tuning improves Qwen3.5-35B-A3B by 199 Elo on GDPval-AA v2, 19.10 percentage points on Terminal-Bench 2.1, and 28.13 and 12.38 points on SkillsBench v1.1 with and without skills, respectively. Our 35B \textttSkillGym-Agent reaches 51.47% on skill-assisted SkillsBench, exceeding reported scores for Claude Sonnet 4.6, GPT-5.4 Mini, and DeepSeek V4 Pro. Without skills, it also surpasses skill-assisted bases under Codex and Claude Code, suggesting reusable procedural competence.
from the abstract
Pith says
Machine review · deepseek-v4-flash · 25 Sep 2026 · what was read was not recorded · not checked by a person
It can be wrong. Challenge this review or reply to it.
Holds up, with conditions. A real resource contribution and a clean Claude Code evaluation, but the core attribution claim is untested: most training trajectories come from tasks where the skill was not shown to matter, and no non-skill control exists. This line is wrong
3 major objections · 6 minor
How often objections from reviews like this one are right: not yet measured
Not checked: figures, code, what the 23 references say.
The paper says, at Section 5.2 / Section 3.2 / Tables 1-2
The review did not quote this passage.
Pith says: Objection 1 of 3 · major
The central attribution is untested. The abstract and Section 5.2 claim that skill-derived supervision improves capabilities and internalizes procedural competence, but the model is trained on all 8,364 trajectories, of which only 3,722 (44.5%) come from Skill-Dep. tasks that passed the contrastive criterion (r+,r-)=(1,0); the remaining 4,642 (55.5%) come from Verifier-Passed fallback tasks for which the contrastive test showed the target skill unnecessary under the reference configuration (Table 1, Table 2, Eq. 2).
more of objection 1
No control SFT on comparable non-skill verified long-horizon trajectories, and no ablation that separates Skill-Dep.-only, Verifier-Passed-only, and All-trajectory supervision, is provided. As the paper stands, the observed gains could equally be produced by generic verified long-horizon trajectory data, data volume, or trajectory length; the signature contrastive mechanism is not shown to matter for training. I would consider the attribution demonstrated if the authors add either (i) a control SFT on an equal-size, length-matched set of verified trajectories generated from non-skill task sources, or (ii) subset ablations over Skill-Dep.-only versus Verifier-Passed-only trajectories. This is load-bearing because the 'learning from skills' and 'internalization' claims both depend on the skill-derived nature of the data being causally relevant.
The paper says, at Table 4 / Appendix D.1
The review did not quote this passage.
A classifier read this sentence of the paper as acknowledging the concern (probability 0.92):
“In particular, the Codex same-backbone comparison also changes the system prompt, so its performance difference cannot be attributed solely to fine-tuning.”
Pith says: Objection 2 of 3 · major
The Codex rows of Table 4 cannot support the fine-tuning attribution. As the authors disclose (Appendix D.1, b399), the Codex base uses the standard system prompt while the SkillGym-Agent evaluation uses the no-applypatch system prompt, so the Codex gains (+37 Elo, +35.96 on Terminal-Bench, +27.69/+20.39 on SkillsBench) are confounded.
more of objection 2
This leaves the Claude Code arm as the only clean same-backbone comparison, and the paper's sharper claims - including the skill-free 'internalization' evidence (26.81% versus 23.34%) - rest entirely on that single harness. I recommend re-running the Codex base under the no-applypatch system prompt (or matching prompts in both directions) so that the 'under Codex' statements in Section 5.2 and the abstract are supported by a matched comparison; alternatively, the Codex results should be presented as exploratory only, with the controlled claims restricted to Claude Code.
The paper says, at Section 5.1 / SkillsBench v1.1 evaluation
The review did not quote this passage.
Pith says: Objection 3 of 3 · major
The degree of overlap between the skills used to construct training tasks and the curated skill packages supplied by SkillsBench v1.1 is unanalyzed, and this matters for the headline numbers. The training corpus is built from the OpenClaw registry (Section 3.1), and SkillsBench evaluation provides task-specific skill packages at inference time; if many SkillsBench packages correspond to skills already represented …
more of objection 3
… in the 2,302 training tasks, then the 51.47% skill-assisted figure (Table 4) is inflated relative to reference models that never saw SkillGym training data. The skill-free result (26.81%) is not affected by this confound and is the right benchmark for the internalization claim, but the 'exceeding Claude Sonnet 4.6, GPT-5.4 Mini, and DeepSeek V4 Pro' statements in the abstract and Figure 1 should be conditioned on an overlap analysis. I ask the authors to quantify the overlap (e.g., by measuring skill-name/template similarity between the training registry and the SkillsBench packages) and to report the skill-assisted score restricted to SkillsBench tasks whose packages do not overlap training skills.
6 minor objections
The paper says, at Abstract / Section 4.2
Pith says: minor objection 1 of 6
The claim that SkillGym-Agent 'exceeds reported scores for Claude Sonnet 4.6, GPT-5.4 Mini, and DeepSeek V4 Pro' should be softened throughout, since Appendix D.1 (b384) correctly notes that public-reference results use different harnesses, inference budgets, and evaluation configurations; the Table 11 caption does hedge this, but the abstract and Figure 1 do not.
The paper says, at Section 5.3 / Table 5
Pith says: minor objection 2 of 6
The teacher-mixing ablations are reported on single runs without confidence intervals or trial counts; given the small absolute differences in some rows (e.g., the 12-Elo GDPval differences between All Teachers and single-teacher settings), I recommend reporting the number of evaluation trials and a variance estimate (e.g., bootstrap intervals) for the three success-rate benchmarks.
show 4 more
The paper says, at Section 2 / Related Work
Pith says: minor objection 3 of 6
The related-work section would benefit from a brief discussion of prior work on curriculum and long-horizon trajectory SFT controls (e.g., whether any prior dataset paper ran non-skill trajectory controls), since the absence of such a control is the central methodological gap; this contextualizes the requested ablation.
The paper says, at Various
Pith says: minor objection 4 of 6
Minor text issues: the title line reads 'Internalizinglarge-scalehumanskills' (missing spacing) in the header; Figure 1 legend ordering is hard to follow (the bars are not in the same order as the legend entries); and several reference entries (e.g., Startup names for model releases) mix blog-style and arxiv-style citations, which should be normalized.
The paper says, at Section 4.1 / Table 6
Pith says: minor objection 5 of 6
The category 'lifestyle' contains only 22 accepted tasks and several sub-categories have zero or near-zero successful trajectories (e.g., culinary-arts has 1 accepted task and 0 trajectories); the authors do note this (b281), but the category-level percentages for such small counts should carry explicit error bars or be omitted from Figure 3.
The paper says, at Section 3.3 / Eq. (3)
Pith says: minor objection 6 of 6
The notation r^h,m_i for trajectory-level reward and the task-level label ℓ_i are clearly distinguished in the text, but the paper never states the reward values used for the promised RL training; since RL is only future work, I suggest removing the phrase 'These resources support ... reinforcement learning' from the abstract preamble or making explicit that no RL results are reported.
What would settle it
Train three students from Qwen3.5-35B-A3B with the identical SFT recipe and matched token budgets: (1) the 3,722 Skill-Dep. trajectories only; (2) the 4,642 Verifier-Passed trajectories only, subsampled to match (1) in length and category mix; (3) all 8,364 trajectories. Evaluate all three under Claude Code with the standard system prompt on GDPval-AA v2, Terminal-Bench 2.1, and SkillsBench v1.1 with and without skills. If condition (3) is approximately equal to condition (2) and both exceed the base, skill-dependence of the training data contributes nothing and the skill-derived attribution fails; if condition (1) is at least as good as (3) and better than (2), the contrastive skill-dependency selection is doing real work and the central claim survives.
from the skeptic's reading
How the review went
4 readings by deepseek-v4-flash · 25 Sep 2026
- Reader holds up, with conditions
- Skeptic agrees
- Editor wrote the verdict above
- Referee major revision: 3 major objections, 6 minor
Not run on this paper: the simulated authors' defence.
Pith did not check this review's objections against the paper.
The review in full
The review in brief, machine-written
Two things to know. First, SkillGym is a real resource contribution: 2,756 Dockerized environments with code-based verifiers, derived from human-written skills, plus 8,364 verified long-horizon trajectories averaging 49 tool calls. Nobody else ships that, and it is likely useful independent of the results. Second, the central claim—that skill-derived supervision internalizes reusable human procedural competence—is not actually tested. Over half the training trajectories (4,642/8,364, from Table 2) come from Verifier-Passed tasks where the contrastive test failed to show the skill mattered, and the paper runs no control SFT on comparable non-skill verified trajectories and no ablation separating Skill-Dep.-only, Verifier-Passed-only, and all-trajectory supervision. So the gains could equally come from generic long-horizon verified trajectory SFT. The stress-test note lands.
What the paper does well: the skill-to-task pipeline with category-specific templates and independent trusted-runtime checkers is a meaningful step past ToolBench-style API supervision. The contrastive skill-dependency label is a sensible empirical operationalization, and the authors are careful to call it reference-configuration evidence, not proof (Section 3.2). The Claude Code arm is clean—same system prompt for base and trained agent—and its gains are substantial and internally consistent (+199 Elo, +19.10 points Terminal-Bench, +28.13/+14.68 SkillsBench). They also disclose the Codex system-prompt confound in Appendix D.1, which is the right thing to do.
Soft spots, in order. The attribution gap above is load-bearing. Second, SkillsBench uses curated skill packages whose overlap with the OpenClaw registry used to build training tasks is unanalyzed; that matters for the 51.47% skill-assisted number. Third, RL with verifier rewards is promised in the framing but never demonstrated and appears only as future work. These are gaps, not fatal flaws; nothing in the paper contradicts its own data.
Who this is for: people building long-horizon agent training data will get real value from the environments and verifiers. Anyone wanting to conclude that skills, rather than long verified trajectories, cause the gains should wait for the control. I'd send this to peer review—the resource and the clean Claude arm justify referee time—but I'd require three additions: a non-skill verified-trajectory SFT control, subset ablations across the two trajectory labels, and an overlap analysis with SkillsBench. Without those, the paper should be framed as a dataset/resource contribution, not as evidence for skill internalization.
The strongest objection
The central claim is that SFT on skill-derived trajectories internalizes reusable procedural competence. The load-bearing internalization evidence is the skill-free result (trained agent beats its skill-assisted base, notably the clean Claude Code comparison: 26.81% vs 23.34%), and the headline attribution is that skill-derived supervision drives the gains. Both hinge on the training data's skill-derived or skill-dependent nature mattering, and this is untested on two grounds. First, there is no control SFT on comparable non-skill verified long-horizon trajectories anywhere in the paper; the authors acknowledge the Codex arm's system-prompt confound (Appendix D.1, b399), but never supply the generic-trajectory control that would make the attribution specific to skills. Second, and sharper, within the paper's own corpus only 3,722 of 8,364 training trajectories (44.5%, Table 1 and Table 2) come from Skill-Dep. tasks satisfying the contrastive criterion (r+,r-) = (1,0) of Eq. (2) in Section 3.2; the remaining 55.5% come from Verifier-Passed fallback tasks for which the target skill was shown unnecessary under the reference configuration. SkillGym-Agent is trained on all 8,364 trajectories, and no ablation separates Skill-Dep.-only, Verifier-Passed-only, and All-trajectory supervision. Since the contrastive skill-dependency test is the framework's signature mechanism, leaving its effect on training untested means the gains could equally come from generic verified long-horizon trajectory SFT, and the human-skill internalization framing is not supported by the present evidence.
The reader's weakest assumption is that the measured gains are attributable to the skill-derived nature of the training data rather than to generic long-horizon verified-trajectory SFT. That is exactly the concern I regard as most load-bearing, so I agree. I sharpen it with a point already latent in the paper's own tables: only 44.5% of training trajectories come from tasks that satisfied the contrastive skill-dependency criterion of Eq. (2), and the released agent trains on all 8,364, so the framework's signature selection mechanism is never shown to affect learning. I do not treat the Codex system-prompt difference as a new finding; the authors disclose it (Appendix D.1, b399), and the Claude Code arm is clean and remains the strongest evidence. I also treat the SkillsBench skill-package overlap as secondary: it threatens only the skill-assisted headline figure, and even there the paper's most important internalization evidence is the skill-free comparison, which skill-package overlap does not directly inflate. Credit where due: the released environments, verifiers, trajectories, and model are real and documented; the Claude Code arm shows large, internally consistent gains across all four metrics; and the teacher-mixing ablations are internally consistent. Those facts, plus the absence of any claim contradicted by the paper's own data, keep this CONDITIONAL rather than REJECT: the gap is an untested attribution, not a demonstrated failure. The proposed internal subset-ablation is cheap, uses the paper's own released corpus and its own contrastive labels, and would settle whether the skill-derived or skill-dependent character of the supervision actually carries the gains.
The referee's report
If the attribution holds, the paper would make a useful contribution on two fronts: a sizeable open corpus of verified long-horizon agent trajectories (2,756 environments, 8,364 trajectories averaging 49 tool calls, with code-based verifiers and anti-shortcut checks), and a demonstration that SFT on such data transfers to external benchmarks. The Claude Code arm is the methodologically clean comparison (same system prompt for base and trained model) and shows large, internally consistent gains, including in the skill-free condition, which is the strongest evidence for internalization. The paper is unusually honest in its disclosures: it explicitly acknowledges that the Codex arm changes the system prompt (Appendix D.1, b399), that Skill-Dep. labels are reference-configuration-relative (b86, b105), and that the cross-harness pooling ablation does not isolate harness from data composition (b180). Because the environments, trajectories, verifiers, and construction code are publicly released, the claims are checkable by others.
Pith's reading of the paper (a machine's summary, not the authors')
SkillGym asks whether human-written agent skills, ordinarily consumed as external inference-time instructions, can instead be converted into executable training environments that a model learns from once and then carries with it. The authors build a pipeline that instantiates each skill as a concrete task with input assets, a Docker runtime, and a code-based outcome verifier, keeps only tasks that pass execution checks, and labels as 'skill-dependent' those a reference agent solves with the skill but fails without. On that basis they release 2,756 environments across 12 categories and 8,364 verified successful trajectories averaging 49 tool calls, then supervised-fine-tune Qwen3.5-35B-A3B on that corpus. The trained SkillGym-Agent beats its base under both Codex and Claude Code on all four reported metrics, and — the load-bearing result — outperforms its own skill-assisted base even when denied inference-time skills. If the claim holds, procedural competence can be internalized from curated human workflows rather than re-fetched on every task.
What carries the argument. The mechanism is the skill-to-task instantiation pipeline with its two-level acceptance criterion. A skill card (Ki) from the OpenClaw registry is paired with a hand-built sub-category template (Tc(i)) to produce an environment Ei = (xi, Ai, ρi, Vi) whose verifier Vi enforces task-specific completion criteria, including anti-shortcut checks against input tampering and answer copying. Validation separates executable correctness from empirical skill dependence: a task is labeled Skill-Dep. exactly when the reference agent passes the verifier with the target skill (r+i = 1) and fails without it (r−i = 0), yielding the contrastive condition (1,0). Trajectories are then collected from four teacher models under two harnesses, and verified ones form the SFT corpus. The contrastive labeling is what lets the authors attribute later gains to the skill's content rather than to generic long-horizon execution.
Core claim. The paper's central claim is that verified interaction experience derived from human-written skills teaches a model reusable procedural competence, not merely better instruction following. Under Claude Code, supervised fine-tuning on SkillGym trajectories lifts Qwen3.5-35B-A3B from 974 to 1173 Elo on GDPval-AA v2, from 39.33% to 58.43% on Terminal-Bench 2.1, and from 23.34% to 51.47% on skill-assisted SkillsBench v1.1; without inference-time skills, the trained agent still scores 26.81%, above the base's skill-assisted 23.34%. The same pattern holds under Codex, where the skill-free gain reaches 20.39 points. Because the skill-free improvement exceeds the base's skill-injected performance, the authors argue the training has internalized the workflows themselves. They further report that the 35B agent's 51.47% skill-assisted SkillsBench score exceeds reported figures for Claude Sonnet 4.6 and GPT-5.4 Mini, positioning skill-derived supervision as a cost-effective route to frontier-competitive agent behavior.
The premise it rests on. The measured gains come from the skill-derived content of the training data, not from generic long-horizon verified-trajectory SFT, a system-prompt change, or overlap between training skills and evaluation skill packages.
If the paper is right (Pith's inferences, not the authors')
Verified workflow experience improves both external skill use and reusable procedural competence, so a single fine-tune can replace per-task skill retrieval for common workflows.
Without inference-time skills, the trained agent surpasses its skill-assisted base under both harnesses, implying the competence is in the weights, not in the prompt.
At 35B parameters the agent reaches 51.47% on skill-assisted SkillsBench, above several larger reported reference models, suggesting skill-derived data is a cheap source of agentic capability at modest scale.
The released verifier-equipped environments directly support reinforcement learning with outcome-based rewards, which the authors identify as the natural next step beyond demonstration-based training.
Cross-harness pooling of trajectories helps Codex substantially more than Claude Code, hinting that weaker starting agents benefit most from diverse interaction data.
The strongest evidence for internalization, the skill-free gain, is also the least controlled: no control SFT on an equally large corpus of long-horizon non-skill trajectories is run, so a matched control is the decisive test the paper leaves open.
Only 36.8% of successful trajectories explicitly invoke their target skill, so the trained agents internalize the workflow without needing to name it — consistent with trace-level procedural imitation rather than skill-document memorization.
If the skill-derived advantage survives a non-skill SFT control, the contrastive (1,0) labeling criterion could be reused as a data-selection principle for other procedure-rich sources, e.g., runbooks or operating manuals.
The Skill-Dep. label is defined relative to one reference configuration; a different reference agent might pass without the skill, so the criterion selects tasks, not an intrinsic property of the skill.
Check this review
Pith stored no record of this review's passes and took no fingerprint of it. Reviews made by code from 13 Nov 2026 on carry both.
How often reviews like this one are right
Reviews like this one: written by deepseek-v4-flash, where what was read was not recorded.
How often objections from reviews like this one are right: not yet measured
Reviews by people
This review was written by a machine. No person has reviewed this paper on Pith yet. A scientist listed on Pith can review it for a fee, and their review is published here whatever it concludes.
How Pith checks papers · The full audit of this paper · Review history (2 versions)
The paper
Abstract
Human-written agent skills encode rich workflows for real-world problem solving, but are typically used as external inference-time instructions rather than internalized as reusable model capabilities. We introduce \textttSkillGym, a framework that transforms these skills into executable, verifiable training environments for large language model agents. Its skill-to-task pipeline instantiates concrete tasks, verifies outcomes with code-based checkers, and assesses empirical skill dependence through contrastive executions. We construct and release 2,756 environments across 12 categories and collect 8,364 successful trajectories from multiple models and harnesses, averaging 49 tool calls and over 60k logged text tokens. These resources support supervised fine-tuning on verified workflows and reinforcement learning with outcome-based rewards. Under Claude Code, supervised fine-tuning improves Qwen3.5-35B-A3B by 199 Elo on GDPval-AA v2, 19.10 percentage points on Terminal-Bench 2.1, and 28.13 and 12.38 points on SkillsBench v1.1 with and without skills, respectively. Our 35B \textttSkillGym-Agent reaches 51.47% on skill-assisted SkillsBench, exceeding reported scores for Claude Sonnet 4.6, GPT-5.4 Mini, and DeepSeek V4 Pro. Without skills, it also surpasses skill-assisted bases under Codex and Claude Code, suggesting reusable procedural competence.
The paper's own sentences, arranged, kept beside the review and separate from it. Each label is drawn from a closed vocabulary; the number beside it is the probability the classifier gave that label. No sentence in this record was written by a model.
abstract compiled · 2026-09-24
The authors' main claim, as the classifier picked it out 0.90
“Without skills, it also surpasses skill-assisted bases under Codex and Claude Code, suggesting reusable procedural competence.”
How the main claim is stated: hedged possibility 0.92
What the abstract itself states, as probabilities: claims first 0.08 · states limitation 0.14 · human participants 0.11 · controlled comparison 0.94 · randomized assignment 0.02 · states quantitative result 0.99 · compares with prior results 0.98 · mentions code or data availability 0.87
The abstract, sentence by sentence
This table labels the abstract only (arXiv listing abstract v1). The number is the probability the classifier gave the label.
| Sentence | Role | The authors' own work | States the main conclusion | Strength |
|---|---|---|---|---|
| Human-written agent skills encode rich workflows for real-world problem solving, but are typically used as external inference-time instructions rather than internalized as reusable model capabilities. | background 0.70 | 0.08 | 0.05 | asserted 1.00 |
| We introduce \texttt{SkillGym}, a framework that transforms these skills into executable, verifiable training environments for large language model agents. | contribution 0.96 | 0.91 | 0.07 | asserted 1.00 |
| Its skill-to-task pipeline instantiates concrete tasks, verifies outcomes with code-based checkers, and assesses empirical skill dependence through contrastive executions. | method 0.99 | 0.92 | 0.04 | asserted 1.00 |
| We construct and release 2,756 environments across 12 categories and collect 8,364 successful trajectories from multiple models and harnesses, averaging 49 tool calls and over 60k logged text tokens. | method 0.53 | 0.96 | 0.04 | asserted 1.00 |
| These resources support supervised fine-tuning on verified workflows and reinforcement learning with outcome-based rewards. | method 0.88 | 0.63 | 0.07 | asserted 0.85 |
| Under Claude Code, supervised fine-tuning improves Qwen3.5-35B-A3B by 199 Elo on GDPval-AA v2, 19.10 percentage points on Terminal-Bench 2.1, and 28.13 and 12.38 points on SkillsBench v1.1 with and without skills, respectively. | result 1.00 | 0.93 | 0.16 | asserted 1.00 |
| Our 35B \texttt{SkillGym-Agent} reaches 51.47\% on skill-assisted SkillsBench, exceeding reported scores for Claude Sonnet 4.6, GPT-5.4 Mini, and DeepSeek V4 Pro. | result 1.00 | 0.95 | 0.30 | asserted 1.00 |
| Without skills, it also surpasses skill-assisted bases under Codex and Claude Code, suggesting reusable procedural competence. | interpretation 0.79 | 0.94 | 0.30 | hedged possibility 0.92 |
What kind of paper the classifier reports this is: method or tool 0.92 · evidence from observation or experiment 0.98
What was examined, and what was not
Sources read
- arXiv listing abstract v1
Not examined
- full text
- figures and tables
- references and citing sentences
- relations to other papers
Levels run
- P abstract
Not run
- S sections
- T body sentences
- C citations
- R cross-paper relations
How the labels were made
Compiled by classifier-1.13.0 via TypeSafe API, question bank abstract-p1-20260923, 2026-09-24: 1 request, 6,523 input tokens.
Every quoted sentence on this record is the authors'. Every label is from Pith's closed vocabulary, with the probability shown beside it. This record as JSON
Figures (6)



Showing 4 of the paper's 6 figures. Figures are the authors', reproduced from the paper.
References (23)
- [1] Michael Ahn, Anthony Brohan, Noah Brown, Yevgen Chebotar, Omar Cortes, Byron David, Chelsea Finn, Chuyuan Fu, Keerthana Gopalakrishnan, Karol Hausman, et al. Do as i can, not as i say: Grounding language in robotic affordances.arXiv preprint arXiv:2204.01691, on PithPith's reviewarXiv
- [4] doi: 10.48550/arXiv.2606.30616. URLhttps://arxiv.org/abs/2606.30616v2. DeepSeek-AI. DeepSeek-V4-Pro-0813. Official model card, Hugging Face, 2026a. URL https://huggingface. co/deepseek-ai/DeepSeek-V4-Pro-0813 . Official release checkpoint, distinct from the preview. Accessed S... on PithPith's reviewarXivdoi:10.48550/arxiv.2606.30616
- [5] 9 ICALK@ECNU DeepSeek-AI. DeepSeek-V4: Towards highly efficient million-token context intelligence. arXiv preprint arXiv:2606.19348, 2026b. URLhttps://arxiv.org/abs/2606.19348. Google Gemini Team. Gemini 3.1 Pro: A smarter model for your most complex tasks. Google Blog, on PitharXiv
- [6] Daya Guo, Dejian Yang, Haowei Zhang, Junxiao Song, Peiyi Wang, Qihao Zhu, Runxin Xu, Ruoyu Zhang, Shirong Ma, Xiao Bi, et al. Deepseek-r1: Incentivizing reasoning capability in llms via reinforcement learning.arXiv preprint arXiv:2501.12948, on PithPith's reviewarXiv
- [9] URL https://arxiv.org/abs/2602.12670v4. Version 4, revised June 14, on PithPith's reviewarXiv
- [11] URL https://arxiv.org/abs/2601.11868. Version 2.1 release:https://hub.harborframework.com/datasets/terminal-bench/terminal-bench-2-1. Grégoire Mialon, Clémentine Fourrier, Craig Swift, Thomas Wolf, Yann LeCun, and Thomas Scialom. Gaia: A benchmark for general ai assistants. In... on PithPith's reviewarXiv
- [12] URLhttps://github.com/openclaw/ clawhub. Accessed: 2026-04-24. Aaron Parisi, Yao Zhao, and Noah Fiedel. Talm: Tool augmented language models.arXiv preprint arXiv:2205.12255, on PithPith's reviewarXiv
- [13] Shishir G. Patil, Tianjun Zhang, Xin Wang, and Joseph E. Gonzalez. Gorilla: Large language model connected with massive apis.arXiv preprint arXiv:2305.15334, on PithPith's reviewarXiv
- [15] URL https://arxiv.org/abs/ 2510.04374. Renjie Pi, Grace Lam, Mohammad Shoeybi, Pooya Jannaty, Bryan Catanzaro, and Wei Ping. On data engineering for scaling LLM terminal capabilities.arXiv preprint arXiv:2602.21193, on PithPith's reviewarXiv
- [16] doi: 10.48550/arXiv.2602.21193. URL https://arxiv.org/abs/2602.21193v1. Yujia Qin, Shihao Liang, Yining Ye, Kunlun Zhu, Lan Yan, Yaxi Lu, Yankai Lin, Xin Cong, Xiangru Tang, Bill Qian, Sihan Zhao, Lauren Hong, Runchu Tian, Ruobing Xie, Jie Zhou, Mark Gerstein, Dahai Li, Zhiyua... on Pithdoi:10.48550/arxiv.2602.21193
- [17] URL https://qwen.ai/blog?id= qwen3.5. Negin Raoof, Richard Zhuang, Marianna Nezhurina, Etash Guha, Atula Tejaswi, Ryan Marten, Charlie F. Ruan, Tyler Griggs, Alexander Glenn Shaw, Hritik Bansal, E. Kelly Buchanan, Artem Gazizov, Reinhard Heckel, Chinmay Hegde, Sankalp Jajee, D... on PithPith's reviewarXiv
- [18] doi: 10.48550/arXiv.2606.24855. URL https://arxiv.org/abs/2606.24855v1. Timo Schick, Jane Dwivedi-Yu, Roberto Dessì, Roberta Raileanu, Maria Lomeli, Eric Hambro, Luke Zettlemoyer, Nicola Cancedda, and Thomas Scialom. Toolformer: Language models can teach themselves to use tool... on PithPith's reviewarXivdoi:10.48550/arxiv.2606.24855
- [19] Zhihong Shao, Peiyi Wang, Qihao Zhu, Runxin Xu, Junxiao Song, Xiao Bi, Haowei Zhang, Mingchuan Zhang, Y . K. Li, Y . Wu, and Daya Guo. Deepseekmath: Pushing the limits of mathematical reasoning in open language models. arXiv preprint arXiv:2402.03300, on PithPith's reviewarXiv
- [20] Qiaoyu Tang, Ziliang Deng, Hongyu Lin, Xianpei Han, Qiao Liang, Boxi Cao, and Le Sun. Toolalpaca: Generalized tool learning for language models with 3000 simulated cases.arXiv preprint arXiv:2306.05301, on PithPith's reviewarXiv
- [21] Guanzhi Wang, Yuqi Xie, Yunfan Jiang, Ajay Mandlekar, Chaowei Xiao, Yuke Zhu, Linxi Fan, and Anima Anandkumar. V oyager: An open-ended embodied agent with large language models.arXiv preprint arXiv:2305.16291, on PithPith's reviewarXiv
- [22] Siwei Wu, Yizhi Li, Yuyang Song, Wei Zhang, Yang Wang, Riza Batista-Navarro, Xian Yang, Mingjie Tang, Bryan Dai, Jian Yang, and Chenghua Lin. Large-scale terminal agentic trajectory generation from dockerized environments. arXiv preprint arXiv:2602.01244, on PithPith's reviewarXiv
- [23] doi: 10.48550/arXiv.2602.01244. URL https://arxiv.org/abs/2602. 01244v3. Tianbao Xie, Danyang Zhang, Jixuan Chen, Xiaochuan Li, Siheng Zhao, Ruisheng Cao, Toh Jing Hua, Zhoujun Cheng, Dongchan Shin, Fangyu Lei, Yitao Liu, Yiheng Xu, Shuyan Zhou, Silvio Savarese, Caiming Xiong,... on PithPith's reviewarXivdoi:10.48550/arxiv.2602.01244
- [24] URL https://arxiv.org/abs/2603.01145. Shunyu Yao, Howard Chen, John Yang, and Karthik Narasimhan. Webshop: Towards scalable real-world web interaction with grounded language agents. InAdvances in Neural Information Processing Systems, on PitharXiv
- [25] 11 ICALK@ECNU Shunyu Yao, Noah Shinn, Pedram Razavi, and Karthik Narasimhan. τ-bench: A benchmark for tool-agent-user interaction in real-world domains.arXiv preprint arXiv:2406.12045, on PithPith's reviewarXiv
- [26] Shuyan Zhou, Frank F. Xu, Hao Zhu, Xuhui Zhou, Robert Lo, Abishek Sridhar, Xianyi Cheng, Tianyue Ou, Yonatan Bisk, Daniel Fried, Uri Alon, and Graham Neubig. Webarena: A realistic web environment for building autonomous agents.arXiv preprint arXiv:2307.13854, on PithPith's reviewarXiv
show 3 more
- [2022] Minghao Li, Yingxiu Zhao, Bowen Yu, Feifan Song, Hangyu Li, Haiyang Yu, Zhoujun Li, Fei Huang, and Yongbin Li. Api-bank: A comprehensive benchmark for tool-augmented llms. InProceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, on Pith
- [2025] URL https:// www.anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills . Ac- cessed: 2026-04-24. Anthropic. Introducing Claude Opus 4.8. Official model announcement, 2026a. URL https://www.anthropic. com/news/claude-opus-4-8. Published May 28, on Pith
- [2026] Lei Bai, Zongsheng Cao, Yang Chen, Zhiyao Cui, Shangheng Du, Yue Fan, Shiyang Feng, Zijie Guo, Haonan He, Liang He, Xiaohan He, Shuyue Hu, Yusong Hu, Songtao Huang, Yichen Jiang, Hao Li, Xin Li, Dahua Lin, Weihao Lin, Fenghua Ling, Dongrui Liu, Zhuo Liu, Wenjie Lou, Runmin Ma,... on PithPith's reviewarXiv
Cited by 1 Pith paper
Reviewed papers on Pith that cite this one. The full citation record
Challenges and discussion
Disagree with the review, or know something it missed? Leave a comment, or challenge this review formally: a challenge becomes a permanent entry in this paper's record, and its decision is published here.
Come back by email
A short list of the week's newly reviewed papers. Nothing is sent until you confirm from your inbox, and every email has a link that stops it. No account.
No comments yet.
Sign in to comment