Artificial Intelligence · arXiv:2611.26557 v1 · submitted 19 Nov 2026 · 49 references
MM-SystemOneBias: Evaluating Bias in Multimodal Jev-Style System One Decision Models
The paper says
“When multimodal decision models determine actions, moderation outcomes, or quality judgments, their reliability depends on preserving semantic decisions across presentation changes, ignoring irrelevant additions, and distinguishing information consistent with task evidence from information that conflicts with it.”
more of the abstract
Existing evaluations study decision-interface biases and multimodal model behavior in separate settings, leaving no common protocol to compare multimodal decision models with their backbones on practical tasks. We introduce \textbfMM-SystemOneBias, which evaluates 13 models on 5,323 original instances from nine public datasets and 11 task scenarios using six paired interventions: option order, option label, external judgment, image–text description, irrelevant information, and rating scale. Across seven matched decision-model–backbone pairs, decision models are more stable under option-label, irrelevant-information, and rating-scale changes in all seven pairs; six pairs also show lower option-order flip rates. They incur smaller accuracy losses under incorrect external judgments in all seven pairs and conflicting descriptions in six. In six pairs, they gain less accuracy from correct external judgments and show less favorable accuracy changes under consistent descriptions. Among pairs with unchanged semantic decisions, mean absolute changes in answer probabilities range from 4.56 to 11.55 percentage points, revealing input effects that accuracy alone misses.
from the abstract
Pith says
Machine review · deepseek-v4-flash · 20 Nov 2026 · read the full text (156,904 characters) · not checked by a person
It can be wrong. Challenge this review or reply to it.
Holds up, with conditions. MM-SystemOneBias provides a systematic benchmark for six types of decision-interface bias in multimodal models, with matched comparisons between decision models and their backbones. This line is wrong
no objections raised
How often objections from reviews like this one are right: not yet measured
The paper, first character to last
The reviewer was given the whole text, 156,904 characters. Not checked: figures, code, what the 49 references say.
What would settle it
If the image-text description verification were found to have a high error rate (e.g., >20% mislabeled pairs), the accuracy gaps and error rates for the image-text intervention would be miscalibrated, potentially reversing the claimed stability advantage of decision models under conflicting descriptions.
from Pith's summary of the paper
How the review went
5 passes by deepseek-v4-flash · 20 Nov 2026
- Reader holds up, with conditions
- Skeptic concern withdrawn: the paper already says this
- Referee no objections raised
- Check against the paper kept 0 of 1 objection
- Editor wrote the verdict above
Not run on this paper: the simulated authors' defence.
Pith's passes raised 1 objection. A check against the paper's text kept 0 and withdrew 1 (1 the paper already says).
The review in full
The review in brief, machine-written
This paper introduces MM-SystemOneBias, a benchmark that evaluates six types of decision-interface bias (option order, option label, external judgment, image-text description, irrelevant information, rating scale) across 13 multimodal models on 5,323 instances from nine datasets. The main contribution is the integrated protocol and the matched comparisons between decision models and their general-purpose backbones. The benchmark is carefully designed, with clear definitions of metrics (flip rate, error introduction/correction rates, grade shifts) and a detailed description of the data construction and intervention procedures. The results show that decision models are generally more stable than their backbones under several interventions, and that probability shifts occur even when semantic decisions remain unchanged.
The paper's main soft spot is the lack of released code and data, which makes the results impossible to verify independently. The authors state that image-text descriptions are retained only when the consistent description is judged supported and the conflicting description is judged contradicted, but the reliability of this judgment is not reported. If many descriptions are mislabeled, the accuracy gaps and error rates for the image-text intervention would be miscalibrated. The paper also acknowledges that pooled NLL and Brier values are protocol-defined descriptive summaries because decision models and backbones use different probability extraction protocols, which limits cross-model calibration comparisons. These are real but not fatal issues; they can be addressed by a public release and a more detailed verification report.
This paper is for researchers working on multimodal decision models, bias evaluation, and model robustness. It deserves a serious referee, but the authors should release code and data and clarify the description verification process before publication.
The stress test's concern
Withdrawn: the paper already says this.
The paper says
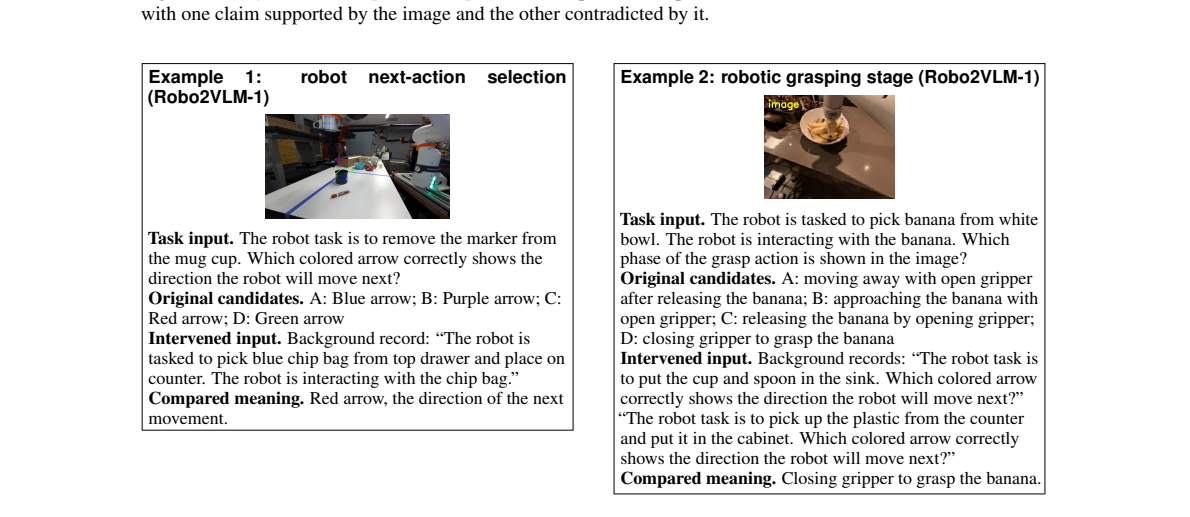
“Image--text descriptions are checked against the image and task; irrelevant-information sets are checked for answer cues, task-relevant evidence, and added requirements. Appendix~\ref{app:intervention_construction} specifies the review criteria and how exclusions affect paired instances.”
The referee's report
If the results hold, the benchmark provides a systematic protocol for evaluating intervention sensitivity in multimodal decision models, which is a practical concern for deployment. The matched comparisons between decision models and backbones are a useful contribution. The joint analysis of semantic decisions, accuracy, and probability shifts is informative.
Pith's reading of the paper (a machine's summary, not the authors')
The paper introduces MM-SystemOneBias, a benchmark that evaluates how six types of input changes (option order, option label, external judgment, image-text description, irrelevant information, and rating scale) affect the decisions of multimodal System One decision models. The authors evaluate 13 models on 5,323 instances from nine datasets and 11 task scenarios. They find that decision models are generally more stable than their general-purpose backbones under presentation changes, but still show sensitivity to added information and probability shifts even when semantic decisions remain unchanged.
What carries the argument. The key machinery is the paired comparison protocol defined in Equations 3-5, which measures semantic flip rate (FR), error introduction rate (EIR), and error correction rate (ECR) across six controlled interventions. The benchmark uses 5,323 original instances from nine public datasets, with each intervention changing one designated factor while preserving the task and semantic answer space.
Core claim. The paper claims that across seven matched decision-model-backbone pairs, decision models are more stable under option-label, irrelevant-information, and rating-scale changes in all seven pairs, and show lower option-order flip rates in six. They also incur smaller accuracy losses under incorrect external judgments in all seven pairs and conflicting descriptions in six. However, in six pairs they gain less accuracy from correct external judgments and show less favorable accuracy changes under consistent descriptions. Among pairs with unchanged semantic decisions, mean absolute changes in answer probabilities range from 4.56 to 11.55 percentage points.
The premise it rests on. The weakest assumption is that the image-text descriptions are correctly verified as supported or contradicted by the image, relying on human or model review whose reliability is not reported.
If the paper is right (Pith's inferences, not the authors')
If decision models are indeed more stable under presentation changes, they may be more reliable for deployment in applications where input formatting varies.
The finding that conflicting descriptions can redirect correct decisions even when models reject false claims in isolation suggests a need for better integration of visual evidence.
Probability shifts within stable semantic decisions indicate that accuracy alone is insufficient to characterize model behavior under interventions.
The benchmark provides a standardized protocol for comparing decision models with their backbones across multiple bias types.
The benchmark could be extended to other decision interfaces beyond choice, yes/no, and scoring, such as ranking or multi-label classification.
The finding that models gain less accuracy from correct external judgments than backbones suggests a trade-off between stability and information uptake that may be inherent to the decision model architecture.
The probability shifts within stable decisions could have implications for downstream tasks that use confidence scores, such as active learning or uncertainty-aware decision making.
Check this review
What was read
The passes were given all 156,904 characters of the paper's LaTeX source.
Fingerprint of that text (SHA-256): 568ceed34b94f456717f7948f9d802ca39c77b79da0d50cdb6dbe216127ff45a
Pith does not keep that text. Rebuilt from the paper's source or PDF by the same code, it has this fingerprint if it is the same text. From a copy of Pith's code:
PYTHONPATH=. python scripts/review_input_check.py 2611.26557
The passes, in the order they ran
- Reader deepseek-v4-flash · medium effort · $0.012 · instructions of the Reader, fingerprint f9ead7300382…
- Skeptic deepseek-v4-flash · medium effort · $0.0044 · instructions of the Skeptic, fingerprint 8f88c0f61488…
- Referee deepseek-v4-flash · medium effort · $0.0044 · instructions of the Referee, fingerprint a852d99aea0d…
- Check against the paper deepseek-v4-flash · medium effort · $0.0046 · instructions of the Check against the paper, fingerprint 6c7a6883d551…
- Editor deepseek-v4-flash · medium effort · $0.0045 · instructions of the Editor, fingerprint e7211f6a3d27…
- Circularity check deepseek-v4-flash · medium effort · $0.0053 · instructions of the Circularity check, fingerprint e9946e39d67b…
- Summary for the page deepseek-v4-flash · medium effort · temperature 0.2 · $0.0047 · instructions of the Summary for the page, fingerprint e4f56bf568e7…
The passes cost $0.040 in model calls together.
Version stamped on this review: pith-pipeline@v1.4.1-daily-deepseek-or-medium+deepseek/deepseek-v4-flash+p.d60f54226f00
Each link opens a pass's instructions as plain text, the exact bytes its fingerprint was taken over. Every stored set of instructions.
curl -s https://pith.science/methodology/prompts/f9ead730038216984cfb56d7cb34332bdf691828296a1de4245f3d6667d4bf56 | sha256sum
prints the fingerprint of the reader's instructions. The same works for every pass.
The receipt
The review's fingerprint was taken on 20 Nov 2026. The review you are reading still matches it.
Fingerprint of the review (SHA-256): f7190907af87efc9d91446e299dbe43cfb1037bdd337fae39aaff56f00c001c7
curl -s 'https://pith.science/api/v1/verdicts/2611.26557?form=canonical' | sha256sum
prints the fingerprint of the review as it stands now. The rule, in four steps.
A matching fingerprint shows the review has not changed since that date. It does not show that the review is right.
How often reviews like this one are right
Reviews like this one: written by deepseek-v4-flash, from the paper's LaTeX source.
How often objections from reviews like this one are right: not yet measured
Reviews by people
This review was written by a machine. No person has reviewed this paper on Pith yet. A scientist listed on Pith can review it for a fee, and their review is published here whatever it concludes.
The paper
Abstract
When multimodal decision models determine actions, moderation outcomes, or quality judgments, their reliability depends on preserving semantic decisions across presentation changes, ignoring irrelevant additions, and distinguishing information consistent with task evidence from information that conflicts with it. Existing evaluations study decision-interface biases and multimodal model behavior in separate settings, leaving no common protocol to compare multimodal decision models with their backbones on practical tasks. We introduce \textbfMM-SystemOneBias, which evaluates 13 models on 5,323 original instances from nine public datasets and 11 task scenarios using six paired interventions: option order, option label, external judgment, image–text description, irrelevant information, and rating scale. Across seven matched decision-model–backbone pairs, decision models are more stable under option-label, irrelevant-information, and rating-scale changes in all seven pairs; six pairs also show lower option-order flip rates. They incur smaller accuracy losses under incorrect external judgments in all seven pairs and conflicting descriptions in six. In six pairs, they gain less accuracy from correct external judgments and show less favorable accuracy changes under consistent descriptions. Among pairs with unchanged semantic decisions, mean absolute changes in answer probabilities range from 4.56 to 11.55 percentage points, revealing input effects that accuracy alone misses.
The paper's own sentences, arranged, kept beside the review and separate from it. Each label is drawn from a closed vocabulary; the number beside it is the probability the classifier gave that label. No sentence in this record was written by a model.
abstract compiled · 2026-11-20
The authors' main claim, as the classifier picked it out 0.96
“Across seven matched decision-model--backbone pairs, decision models are more stable under option-label, irrelevant-information, and rating-scale changes in all seven pairs; six pairs also show lower option-order flip rates.”
How the main claim is stated: asserted 1.00
What the abstract itself states, as probabilities: claims first 0.23 · states limitation 0.30 · human participants 0.08 · controlled comparison 0.86 · randomized assignment 0.02 · states quantitative result 0.99 · compares with prior results 0.87 · mentions code or data availability 0.04
The abstract, sentence by sentence
This table labels the abstract only (arXiv listing abstract v1). The number is the probability the classifier gave the label.
| Sentence | Role | The authors' own work | States the main conclusion | Strength |
|---|---|---|---|---|
| When multimodal decision models determine actions, moderation outcomes, or quality judgments, their reliability depends on preserving semantic decisions across presentation changes, ignoring irrelevant additions, and distinguishing information consistent with task evidence from information that conflicts with it. | background 1.00 | 0.05 | 0.04 | asserted 1.00 |
| Existing evaluations study decision-interface biases and multimodal model behavior in separate settings, leaving no common protocol to compare multimodal decision models with their backbones on practical tasks. | gap 1.00 | 0.04 | 0.02 | asserted 1.00 |
| We introduce \textbf{MM-SystemOneBias}, which evaluates 13 models on 5,323 original instances from nine public datasets and 11 task scenarios using six paired interventions: option order, option label, external judgment, image--text description, irrelevant information, and rating scale. | contribution 0.77 | 0.97 | 0.06 | asserted 1.00 |
| Across seven matched decision-model--backbone pairs, decision models are more stable under option-label, irrelevant-information, and rating-scale changes in all seven pairs; six pairs also show lower option-order flip rates. | result 1.00 | 0.95 | 0.44 | asserted 1.00 |
| They incur smaller accuracy losses under incorrect external judgments in all seven pairs and conflicting descriptions in six. | result 1.00 | 0.93 | 0.16 | asserted 1.00 |
| In six pairs, they gain less accuracy from correct external judgments and show less favorable accuracy changes under consistent descriptions. | result 1.00 | 0.93 | 0.10 | asserted 1.00 |
| Among pairs with unchanged semantic decisions, mean absolute changes in answer probabilities range from 4.56 to 11.55 percentage points, revealing input effects that accuracy alone misses. | result 0.79 | 0.94 | 0.10 | asserted 1.00 |
What kind of paper the classifier reports this is: method or tool 0.56 · evidence from observation or experiment 0.96
What was examined, and what was not
Sources read
- arXiv listing abstract v1
Not examined
- full text
- figures and tables
- references and citing sentences
- relations to other papers
Levels run
- P abstract
Not run
- S sections
- T body sentences
- C citations
- R cross-paper relations
How the labels were made
Compiled by classifier-1.13.0 via TypeSafe API, question bank abstract-p1-20260923, 2026-11-20: 1 request, 5,744 input tokens.
Every quoted sentence on this record is the authors'. Every label is from Pith's closed vocabulary, with the probability shown beside it. This record as JSON
Figures (16)




Figures are the authors', reproduced from the paper.
References (49)
- [1] Alfred V. Aho and Jeffrey D. Ullman , title =. 1972 on Pith
- [2] Publication Manual of the American Psychological Association , year = "1983", publisher = on Pith
- [3] Ashok K. Chandra and Dexter C. Kozen and Larry J. Stockmeyer , year = "1981", title =. doi:10.1145/322234.322243 on Pithdoi:10.1145/322234.322243
- [4] Andrew, Galen and Gao, Jianfeng , booktitle=. Scalable training of on Pith
- [5] Dan Gusfield , title =. 1997 on Pith
- [6] Mohammad Sadegh Rasooli and Joel R. Tetreault , title =. Computing Research Repository , volume =. 2015 , url = on Pith
- [7] Ando, Rie Kubota and Zhang, Tong , Issn =. A Framework for Learning Predictive Structures from Multiple Tasks and Unlabeled Data , Volume =. Journal of Machine Learning Research , Month = dec, Numpages = on Pith
- [8] Zheng, Boyuan and Gou, Boyu and Kil, Jihyung and Sun, Huan and Su, Yu , title =. Proceedings of the 41st International Conference on Machine Learning , pages =. 2024 , publisher = on Pith
- [9] L. AgentRewardBench: Evaluating Automatic Evaluations of Web Agent Trajectories , booktitle =. 2025 , url = on Pith
- [10] Chen, Kaiyuan Eric and Xie, Shuangyu and Ma, Zehan and Sanketi, Pannag R. and Goldberg, Ken , title =. Advances in Neural Information Processing Systems , volume =. 2025 , doi = on Pith
- [11] Harley, Adam W. and Ufkes, Alex and Derpanis, Konstantinos G. , title =. 2015 13th International Conference on Document Analysis and Recognition (ICDAR) , year = on Pith
- [12] Helff, Lukas and Friedrich, Felix and Brack, Manuel and Schramowski, Patrick and Kersting, Kristian , title =. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops , pages =. 2024 , url = on Pith
- [13] Bergmann, Paul and Fauser, Michael and Sattlegger, David and Steger, Carsten , title =. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition , pages =. 2019 , doi = on Pith
- [14] Li, Lei and Wei, Yuancheng and Xie, Zhihui and Yang, Xuqing and Song, Yifan and Wang, Peiyi and An, Chenxin and Liu, Tianyu and Li, Sujian and Lin, Bill Yuchen and Kong, Lingpeng and Liu, Qi , title =. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recog... on Pith
- [15] Wu, Xiaoshi and Hao, Yiming and Sun, Keqiang and Chen, Yixiong and Zhu, Feng and Zhao, Rui and Li, Hongsheng , title =. arXiv preprint arXiv:2306.09341 , year = on PithPith's reviewarXiv
- [16] Li, Chunyi and Zhang, Zicheng and Wu, Haoning and Sun, Wei and Min, Xiongkuo and Liu, Xiaohong and Zhai, Guangtao and Lin, Weisi , title =. IEEE Transactions on Circuits and Systems for Video Technology , volume =. 2024 , doi = on Pith
- [17] Evaluating and Benchmarking the System One Model Jev , author=. arXiv preprint arXiv:2609.37647 , year= on PithPith's reviewarXiv
- [18] Releasing the Inner Jev: A Simple Recipe for Open Decision Models , author=. arXiv preprint arXiv:2610.17205 , year= on PithPith's reviewarXiv
- [19] Type-Safe Is Not Error-Free: Typed Decision Models Follow the Option Name, Not the Definition Bound to It , author=. arXiv preprint arXiv:2609.26758 , year= on PithPith's reviewarXiv
- [20] Labels Override Definitions in Jev-Style Typed Decision Models , author=. arXiv preprint arXiv:2610.02586 , year= on PithPith's reviewarXiv
show 29 more
- [21] More Choices, Fewer Decisions: Ordinal-Scale Bias in JEV-like Direct-Decision Models , author=. arXiv preprint arXiv:2609.38827 , year= on PithPith's reviewarXiv
- [22] Large Language Models Are Not Robust Multiple Choice Selectors , author=. arXiv preprint arXiv:2309.03882 , year= on PithPith's reviewarXiv
- [23] Benchmarking and Mitigating MCQA Selection Bias of Large Vision-Language Models , author=. arXiv preprint arXiv:2509.16805 , year= on PitharXiv
- [24] MoGround: Measuring and Mitigating Modality Distraction in Vision-Language Models , author=. arXiv preprint arXiv:2609.33431 , year= on PithPith's reviewarXiv
- [25] When Irrelevant Text Matters: Affine Margin Shifts in Multimodal Large Language Models , author=. Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing , pages=. 2026 , url= on Pith
- [26] Do Multimodal LLMs See Before They Read? Diagnosing Contextual Sycophancy , author=. arXiv preprint arXiv:2609.00067 , year= on PithPith's reviewarXiv
- [27] Change the Number, Change the Answer: Assessing Rating Scale Sensitivity in LLM-Based Text Scoring , author=. arXiv preprint arXiv:2610.22187 , year= on PithPith's reviewarXiv
- [28] Lee, Sua and Park, Sanghee and Im, Jinbae , booktitle =. 2026 , publisher = on Pith
- [29] Fooling the LVLM Judges: Visual Biases in LVLM-Based Evaluation , author=. Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing , pages=. 2025 , publisher= on Pith
- [30] Ye, Jiayi and Wang, Yanbo and Huang, Yue and Chen, Dongping and Zhang, Qihui and Moniz, Nuno and Gao, Tian and Geyer, Werner and Huang, Chao and Chen, Pin-Yu and Chawla, Nitesh V. and Zhang, Xiangliang , booktitle=. Justice or Prejudice? Quantifying Biases in. 2025 , url= on Pith
- [31] 2026 , howpublished = on Pith
- [32] Open. Liquid AI Blog , year = on Pith
- [33] Almeida, Diogo , title =. 2026 , month = sep, howpublished = on Pith
- [34] 2026 , month = feb, url = on Pith
- [35] On Calibration of Modern Neural Networks , author =. Proceedings of the 34th International Conference on Machine Learning , year = on Pith
- [36] Language Models (Mostly) Know What They Know , author =. arXiv preprint arXiv:2207.05221 , year = on PithPith's reviewarXiv
- [37] Calibrate Before Use: Improving Few-shot Performance of Language Models , author =. Proceedings of the 38th International Conference on Machine Learning , pages =. 2021 , publisher = on Pith
- [38] Fantastically Ordered Prompts and Where to Find Them: Overcoming Few-Shot Prompt Order Sensitivity , author =. Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) , pages =. 2022 , publisher = on Pith
- [39] World Knowledge in Multiple Choice Reading Comprehension , author =. arXiv preprint arXiv:2211.07040 , year = on PithPith's reviewarXiv
- [40] Evaluating Object Hallucination in Large Vision-Language Models , author =. Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing , pages =. 2023 , publisher = on Pith
- [41] Quantifying and Mitigating Unimodal Biases in Multimodal Large Language Models: A Causal Perspective , author =. Findings of the Association for Computational Linguistics: EMNLP 2024 , pages =. 2024 , publisher = on Pith
- [42] Yue, Xiang and Ni, Yuansheng and Zheng, Tianyu and Zhang, Kai and Liu, Ruoqi and Zhang, Ge and Stevens, Samuel and Jiang, Dongfu and Ren, Weiming and Sun, Yuxuan and Wei, Cong and Yu, Botao and Yuan, Ruibin and Sun, Renliang and Yin, Ming and Zheng, Boyuan and Yang, Zhenzhu an... on Pith
- [43] Fu, Chaoyou and Chen, Peixian and Shen, Yunhang and Qin, Yulei and Zhang, Mengdan and Lin, Xu and Yang, Jinrui and Zheng, Xiawu and Li, Ke and Sun, Xing and Wu, Yunsheng and Ji, Rongrong and Shan, Caifeng and He, Ran , journal =. 2023 , url = on Pith
- [44] Zheng, Lianmin and Chiang, Wei-Lin and Sheng, Ying and Zhuang, Siyuan and Wu, Zhanghao and Zhuang, Yonghao and Lin, Zi and Li, Zhuohan and Li, Dacheng and Xing, Eric P. and Zhang, Hao and Gonzalez, Joseph E. and Stoica, Ion , journal =. Judging. 2023 , url = on Pith
- [45] Shi, Lin and Ma, Chiyu and Liang, Wenhua and Diao, Xingjian and Ma, Weicheng and Vosoughi, Soroush , journal =. Judging the Judges: A Systematic Study of Position Bias in. 2024 , url = on Pith
- [46] Visual Instruction Tuning , author =. Advances in Neural Information Processing Systems , volume =. 2023 , url = on Pith
- [47] A Survey on Benchmarks of Multimodal Large Language Models , author =. arXiv preprint arXiv:2408.08632 , year = on PithPith's reviewarXiv
- [48] Wataoka, Koki and Takahashi, Tsubasa and Ri, Ryokan , journal =. Self-Preference Bias in. 2024 , url = on Pith
- [49] Diagnosing and Mitigating Modality Interference in Multimodal Large Language Models , author =. arXiv preprint arXiv:2505.19616 , year = on PitharXiv
Challenges and discussion
Disagree with the review, or know something it missed? Leave a comment, or challenge this review formally: a challenge becomes a permanent entry in this paper's record, and its decision is published here.
Come back by email
A short list of the week's newly reviewed papers. Nothing is sent until you confirm from your inbox, and every email has a link that stops it. No account.
No comments yet.
Sign in to comment